# Advanced Scraping Guide
Source: https://docs.firecrawl.dev/advanced-scraping-guide
Configure scrape options, browser actions, crawl, map, and the agent endpoint with Firecrawl's full API surface.
Reference for every option across Firecrawl's scrape, crawl, map, and agent endpoints.
## Basic scraping
To scrape a single page and get clean markdown content, use the `/scrape` endpoint.
```python Python theme={null}
# pip install firecrawl
from firecrawl import Firecrawl
firecrawl = Firecrawl(api_key="fc-YOUR-API-KEY")
doc = firecrawl.scrape("https://firecrawl.dev")
print(doc.markdown)
```
```js Node theme={null}
// npm install firecrawl
import { Firecrawl } from 'firecrawl-js';
const firecrawl = new Firecrawl({ apiKey: 'fc-YOUR-API-KEY' });
const doc = await firecrawl.scrape('https://firecrawl.dev');
console.log(doc.markdown);
```
```bash cURL theme={null}
curl -X POST https://api.firecrawl.dev/v2/scrape \
-H 'Content-Type: application/json' \
-H 'Authorization: Bearer fc-YOUR-API-KEY' \
-d '{
"url": "https://docs.firecrawl.dev"
}'
```
## Scraping PDFs
Firecrawl supports PDFs. Use the `parsers` option (e.g., `parsers: ["pdf"]`) when you want to ensure PDF parsing. You can control the parsing strategy with the `mode` option:
* **`auto`** (default) — attempts fast text-based extraction first, then falls back to OCR if needed.
* **`fast`** — text-based parsing only (embedded text). Fastest, but skips scanned/image-heavy pages.
* **`ocr`** — forces OCR parsing on every page. Use for scanned documents or when `auto` misclassifies a page.
`{ type: "pdf" }` and `"pdf"` both default to `mode: "auto"`.
## Scraping images
Firecrawl also OCRs raster images (PNG, JPEG, JPEG 2000, TIFF, GIF, BMP, WebP, AVIF) and returns the text as markdown. SVG and HEIC are not supported. The `image` parser is on by default, so you do not need to set it. It has no options: `"image"` and `{ "type": "image" }` are the same.
The default is `parsers: ["pdf", "image"]`. If you pass a list, parsers that are not in the list are off. For example, `parsers: ["pdf"]` turns off image OCR, so an image URL fails as an unsupported file.
```json theme={null}
"parsers": [{ "type": "pdf", "mode": "fast", "maxPages": 50 }]
```
## Scrape options
When using the `/scrape` endpoint, you can customize the request with the following options.
### Formats (`formats`)
The `formats` array controls which output types the scraper returns. Default: `["markdown"]`.
**String formats**: pass the name directly (e.g. `"markdown"`).
| Format | Description |
| - | - |
| `markdown` | Page content converted to clean Markdown. |
| `html` | Processed HTML with unnecessary elements removed. |
| `rawHtml` | Original HTML exactly as returned by the server. |
| `rawBase64` | Base64-encoded original HTTP response body, as a bare Base64 string. Must be the only format in the request. The MIME type is in `metadata.contentType`. |
| `links` | All links found on the page. |
| `images` | All images found on the page. |
| `summary` | An LLM-generated summary of the page content. |
| `branding` | Extracts brand identity (colors, fonts, typography, spacing, UI components). |
| `product` | Extracts a structured product (title, price, availability, images, variants) from product pages via multi-source structured data. |
**Object formats**: pass an object with `type` and additional options.
| Format | Options | Description |
| - | - | - |
| `json` | `prompt?: string`, `schema?: object` | Extract structured data using an LLM. Provide a JSON schema and/or a natural-language prompt (max 10,000 characters). |
| `screenshot` | `fullPage?: boolean`, `quality?: number`, `viewport?: { width, height }` | Capture a screenshot. Max one per request. Viewport max resolution is 7680×4320. Screenshot URLs expire after 24 hours. |
| `changeTracking` | `modes?: ("json" \| "git-diff")[]`, `tag?: string`, `schema?: object`, `prompt?: string` | Track changes between scrapes. Requires `"markdown"` to also be in the formats array. |
| `attributes` | `selectors: [{ selector: string, attribute: string }]` | Extract specific HTML attributes from elements matching CSS selectors. |
### Mobile scraping
Set `mobile: true` to emulate a mobile device. This is useful when a responsive site hides content on desktop or serves a different layout to mobile browsers.
For region-specific sites, combine with `location` and a mobile screenshot to verify the rendered layout:
```python Python theme={null}
from firecrawl import Firecrawl
firecrawl = Firecrawl(api_key="fc-YOUR-API-KEY")
doc = firecrawl.scrape(
"https://example.com",
mobile=True,
location={"country": "GB", "languages": ["en-GB"]},
formats=[
"markdown",
{"type": "screenshot", "fullPage": True, "viewport": {"width": 390, "height": 844}},
],
only_main_content=False,
wait_for=2000,
)
print(doc.markdown)
```
```js Node theme={null}
import { Firecrawl } from 'firecrawl-js';
const firecrawl = new Firecrawl({ apiKey: 'fc-YOUR-API-KEY' });
const doc = await firecrawl.scrape('https://example.com', {
mobile: true,
location: { country: 'GB', languages: ['en-GB'] },
formats: [
'markdown',
{ type: 'screenshot', fullPage: true, viewport: { width: 390, height: 844 } },
],
onlyMainContent: false,
waitFor: 2000,
});
console.log(doc.markdown);
```
```bash cURL theme={null}
curl -X POST https://api.firecrawl.dev/v2/scrape \
-H 'Content-Type: application/json' \
-H 'Authorization: Bearer fc-YOUR-API-KEY' \
-d '{
"url": "https://example.com",
"mobile": true,
"location": {
"country": "GB",
"languages": ["en-GB"]
},
"formats": [
"markdown",
{ "type": "screenshot", "fullPage": true, "viewport": { "width": 390, "height": 844 } }
],
"onlyMainContent": false,
"waitFor": 2000
}'
```
If the site still serves a desktop layout despite `mobile: true`, add a mobile User-Agent via `headers`:
```json theme={null}
{
"headers": {
"User-Agent": "Mozilla/5.0 (iPhone; CPU iPhone OS 17_0 like Mac OS X) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/17.0 Mobile/15E148 Safari/604.1"
}
}
```
### Content filtering
These parameters control which parts of the page appear in the output. When `onlyMainContent` is `true` (the default), boilerplate (nav, footer, etc.) is stripped. `includeTags` and `excludeTags` are applied against the original page DOM, not the post-filtered result, so your selectors should target elements as they appear in the source HTML. Set `onlyMainContent: false` to use the full page as the starting point for tag filtering.
| Parameter | Type | Default | Description |
| - | - | - | - |
| `onlyMainContent` | `boolean` | `true` | Return only the main content. Set `false` for the full page. |
| `includeTags` | `array` | — | CSS selectors to include — tags, classes, IDs, or attribute selectors (e.g. `["h1", "p", ".main-content", "[data-testid=\"main\"]"]`). |
| `excludeTags` | `array` | — | CSS selectors to exclude — tags, classes, IDs, or attribute selectors (e.g. `["#ad", "#footer", "[role=\"banner\"]"]`). |
### Timing and cache
| Parameter | Type | Default | Description |
| - | - | - | - |
| `waitFor` | `integer` (ms) | `0` | Extra wait time before scraping, on top of smart-wait. Use sparingly. |
| `maxAge` | `integer` (ms) | `172800000` | Return a cached version if fresher than this value (default is 2 days). Set `0` to always fetch fresh. |
| `timeout` | `integer` (ms) | `60000` | Max request duration before aborting (default is 60 seconds). Minimum is 1000 (1 second). |
### Prompt injection check
| Parameter | Type | Default | Description |
| - | - | - | - |
| `checkPromptInjection` | `boolean` | `false` | Scan the page content for prompt injection attempts before any LLM-backed format (such as `json`, `summary` or `question`) runs. Works with any format except `rawBase64`. A detection fails the request with a `403` and `SCRAPE_PROMPT_INJECTION_DETECTED`. Adds 4 credits when the check scans the whole page. See [Prompt injection detection](/features/llm-extract#prompt-injection-detection). |
### PDF parsing
| Parameter | Type | Default | Description |
| - | - | - | - |
| `parsers` | `array` | `["pdf", "image"]` | Controls PDF and image processing. Each item is `"pdf"`, `"image"`, or a parser object. A list turns off the parsers it leaves out. `[]` to skip parsing and return the PDF as base64 (1 credit flat). |
```json theme={null}
{ "type": "pdf", "mode": "fast" | "auto" | "ocr", "maxPages": 10, "pages": true, "blocks": true, "pageMarkers": true }
```
| Property | Type | Default | Description |
| - | - | - | - |
| `type` | `"pdf"` | *(required)* | Parser type. |
| `mode` | `"fast" \| "auto" \| "ocr"` | `"auto"` | `fast`: text-based extraction only. `auto`: fast with OCR fallback. `ocr`: force OCR. |
| `maxPages` | `integer` | — | Cap the number of pages to parse. |
| `pages` | `boolean` | `false` | Also return physical per-page markdown in the document's `pages` field. No additional cost. |
| `blocks` | `boolean` | `false` | Also return per-page typed layout blocks (normalized bounding boxes, block types, reading order, markdown character spans) in the document's `blocks` field. No additional cost. |
| `pageMarkers` | `boolean` | `false` | Annotate page breaks in the document markdown with `` markers (between pages only; numbering may skip pages merged across a break — see [Parse](/features/parse#page-markers-pdf)). No additional cost. |
The `image` parser object is `{ "type": "image" }`. It has no other properties, and the PDF properties above do not apply to images.
### Actions
Run browser actions before scraping. This is useful for dynamic content, navigation, or user-gated pages. You can include up to 50 actions per request, and the combined wait time across all `wait` actions and `waitFor` must not exceed 60 seconds.
| Action | Parameters | Description |
| - | - | - |
| `wait` | `milliseconds?: number`, `selector?: string` | Wait for a fixed duration **or** until an element is visible (provide one, not both). When using `selector`, times out after 30 seconds. |
| `click` | `selector: string`, `all?: boolean` | Click an element matching the CSS selector. Set `all: true` to click every match. |
| `write` | `text: string` | Type text into the currently focused field. You must focus the element with a `click` action first. |
| `press` | `key: string` | Press a keyboard key (e.g. `"Enter"`, `"Tab"`, `"Escape"`). |
| `scroll` | `direction?: "up" \| "down"`, `selector?: string` | Scroll the page or a specific element. Direction defaults to `"down"`. |
| `screenshot` | `fullPage?: boolean`, `quality?: number`, `viewport?: { width, height }` | Capture a screenshot. Max viewport resolution is 7680×4320. |
| `scrape` | *(none)* | Capture the current page HTML at this point in the action sequence. |
| `executeJavascript` | `script: string` | Run JavaScript code in the page. Return values are available in the `actions.javascriptReturns` array of the response. |
| `pdf` | `format?: string`, `landscape?: boolean`, `scale?: number` | Generate a PDF. Supported formats: `"A0"` through `"A6"`, `"Letter"`, `"Legal"`, `"Tabloid"`, `"Ledger"`. Defaults to `"Letter"`. |
```python Python theme={null}
from firecrawl import Firecrawl
firecrawl = Firecrawl(api_key='fc-YOUR-API-KEY')
doc = firecrawl.scrape('https://example.com', {
'actions': [
{ 'type': 'wait', 'milliseconds': 1000 },
{ 'type': 'click', 'selector': '#accept' },
{ 'type': 'scroll', 'direction': 'down' },
{ 'type': 'click', 'selector': '#q' },
{ 'type': 'write', 'text': 'firecrawl' },
{ 'type': 'press', 'key': 'Enter' },
{ 'type': 'wait', 'milliseconds': 2000 }
],
'formats': ['markdown']
})
print(doc.markdown)
```
```js Node theme={null}
import { Firecrawl } from 'firecrawl-js';
const firecrawl = new Firecrawl({ apiKey: 'fc-YOUR-API-KEY' });
const doc = await firecrawl.scrape('https://example.com', {
actions: [
{ type: 'wait', milliseconds: 1000 },
{ type: 'click', selector: '#accept' },
{ type: 'scroll', direction: 'down' },
{ type: 'click', selector: '#q' },
{ type: 'write', text: 'firecrawl' },
{ type: 'press', key: 'Enter' },
{ type: 'wait', milliseconds: 2000 }
],
formats: ['markdown']
});
console.log(doc.markdown);
```
```bash cURL theme={null}
curl -X POST https://api.firecrawl.dev/v2/scrape \
-H 'Content-Type: application/json' \
-H 'Authorization: Bearer fc-YOUR-API-KEY' \
-d '{
"url": "https://example.com",
"actions": [
{ "type": "wait", "milliseconds": 1000 },
{ "type": "click", "selector": "#accept" },
{ "type": "scroll", "direction": "down" },
{ "type": "click", "selector": "#q" },
{ "type": "write", "text": "firecrawl" },
{ "type": "press", "key": "Enter" },
{ "type": "wait", "milliseconds": 2000 }
],
"formats": ["markdown"]
}'
```
#### Action execution notes
* **Write** requires a preceding `click` to focus the target element.
* **Scroll** accepts an optional `selector` to scroll a specific element instead of the page.
* **Wait** accepts either `milliseconds` (fixed delay) or `selector` (wait until visible).
* Actions run **sequentially**: each step completes before the next begins.
* Actions are **not supported for PDFs**. If the URL resolves to a PDF the request will fail.
#### Advanced action examples
**Taking a screenshot:**
```bash cURL theme={null}
curl -X POST https://api.firecrawl.dev/v2/scrape \
-H 'Content-Type: application/json' \
-H 'Authorization: Bearer fc-YOUR-API-KEY' \
-d '{
"url": "https://example.com",
"actions": [
{ "type": "click", "selector": "#load-more" },
{ "type": "wait", "milliseconds": 1000 },
{ "type": "screenshot", "fullPage": true, "quality": 80 }
]
}'
```
**Clicking multiple elements:**
```bash cURL theme={null}
curl -X POST https://api.firecrawl.dev/v2/scrape \
-H 'Content-Type: application/json' \
-H 'Authorization: Bearer fc-YOUR-API-KEY' \
-d '{
"url": "https://example.com",
"actions": [
{ "type": "click", "selector": ".expand-button", "all": true },
{ "type": "wait", "milliseconds": 500 }
],
"formats": ["markdown"]
}'
```
**Generating a PDF:**
```bash cURL theme={null}
curl -X POST https://api.firecrawl.dev/v2/scrape \
-H 'Content-Type: application/json' \
-H 'Authorization: Bearer fc-YOUR-API-KEY' \
-d '{
"url": "https://example.com",
"actions": [
{ "type": "pdf", "format": "A4", "landscape": false }
]
}'
```
**Executing JavaScript (e.g. extracting embedded page data):**
```bash cURL theme={null}
curl -X POST https://api.firecrawl.dev/v2/scrape \
-H 'Content-Type: application/json' \
-H 'Authorization: Bearer fc-YOUR-API-KEY' \
-d '{
"url": "https://example.com",
"actions": [
{ "type": "executeJavascript", "script": "document.querySelector(\"#__NEXT_DATA__\").textContent" }
],
"formats": ["markdown"]
}'
```
The return value of each `executeJavascript` action is captured in the `actions.javascriptReturns` array of the response.
### Full scrape example
The following request combines multiple scrape options:
```bash cURL theme={null}
curl -X POST https://api.firecrawl.dev/v2/scrape \
-H 'Content-Type: application/json' \
-H 'Authorization: Bearer fc-YOUR-API-KEY' \
-d '{
"url": "https://docs.firecrawl.dev",
"formats": [
"markdown",
"links",
"html",
"rawHtml",
{ "type": "screenshot", "fullPage": true, "quality": 80 }
],
"includeTags": ["h1", "p", "a", ".main-content"],
"excludeTags": ["#ad", "#footer"],
"onlyMainContent": false,
"waitFor": 1000,
"timeout": 15000,
"parsers": ["pdf"]
}'
```
This request returns markdown, HTML, raw HTML, links, and a full-page screenshot. It scopes content to `
)}
```
## Scrape a page
Create `src/pages/api/scrape.ts`:
```typescript theme={null}
import type { APIRoute } from "astro";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: import.meta.env.FIRECRAWL_API_KEY,
});
export const POST: APIRoute = async ({ request }) => {
const { url } = await request.json();
const result = await firecrawl.scrape(url);
return new Response(JSON.stringify(result), {
headers: { "Content-Type": "application/json" },
});
};
```
Or scrape at request time in a server-rendered page (`src/pages/scrape.astro`):
```astro theme={null}
---
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: import.meta.env.FIRECRAWL_API_KEY,
});
const target = Astro.url.searchParams.get("url");
let markdown = null;
if (target) {
const result = await firecrawl.scrape(target);
markdown = result.markdown;
}
---
Scraped Content
{markdown ?
{markdown}
:
Pass ?url= to scrape a page
}
```
## Interact with a page
Create `src/pages/api/interact.ts`:
```typescript theme={null}
import type { APIRoute } from "astro";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: import.meta.env.FIRECRAWL_API_KEY,
});
export const POST: APIRoute = async () => {
const result = await firecrawl.scrape("https://www.amazon.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, {
prompt: "Search for iPhone 16 Pro Max",
});
const response = await firecrawl.interact(scrapeId, {
prompt: "Click on the first result and tell me the price",
});
await firecrawl.stopInteraction(scrapeId);
return new Response(JSON.stringify({ output: response.output }), {
headers: { "Content-Type": "application/json" },
});
};
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# AWS Lambda
Source: https://docs.firecrawl.dev/quickstarts/aws-lambda
Use Firecrawl with AWS Lambda to search, scrape, and interact with web data in serverless functions.
## Prerequisites
* AWS account with Lambda access
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
mkdir firecrawl-lambda && cd firecrawl-lambda
npm init -y
npm install firecrawl
```
## Search the web
Create `index.mjs` with a search handler:
```javascript theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function handler(event) {
const body = JSON.parse(event.body || "{}");
if (body.action === "search") {
const results = await firecrawl.search(body.query, { limit: 5 });
return {
statusCode: 200,
body: JSON.stringify(results),
};
}
return { statusCode: 400, body: JSON.stringify({ error: "Unknown action" }) };
}
```
## Scrape a page
Add a `scrape` action to the same handler:
```javascript theme={null}
if (body.action === "scrape") {
const result = await firecrawl.scrape(body.url);
return {
statusCode: 200,
body: JSON.stringify(result),
};
}
```
## Interact with a page
Add an `interact` action to control a live browser session — click buttons, fill forms, and extract dynamic content:
```javascript theme={null}
if (body.action === "interact") {
const result = await firecrawl.scrape("https://www.amazon.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, {
prompt: "Search for iPhone 16 Pro Max",
});
const response = await firecrawl.interact(scrapeId, {
prompt: "Click on the first result and tell me the price",
});
await firecrawl.stopInteraction(scrapeId);
return {
statusCode: 200,
body: JSON.stringify({ output: response.output }),
};
}
```
## Deploy
Package and deploy with the AWS CLI:
```bash theme={null}
zip -r function.zip index.mjs node_modules/
aws lambda create-function \
--function-name firecrawl-scraper \
--runtime nodejs20.x \
--handler index.handler \
--zip-file fileb://function.zip \
--role arn:aws:iam::YOUR_ACCOUNT:role/lambda-role \
--environment Variables="{FIRECRAWL_API_KEY=fc-YOUR-API-KEY}" \
--timeout 60
```
> [!NOTE]
>
> Set the Lambda timeout to at least 30 seconds. Scraping dynamic pages and interact sessions can take longer than the default 3-second timeout.
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Bun
Source: https://docs.firecrawl.dev/quickstarts/bun
Use Firecrawl with Bun to build fast servers that search, scrape, and interact with the web.
## Prerequisites
* Bun 1.0+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
bun add firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
Bun has a built-in HTTP server. Create `index.ts`:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
Bun.serve({
port: 3000,
async fetch(req) {
const url = new URL(req.url);
if (req.method === "POST" && url.pathname === "/search") {
const { query } = await req.json();
const results = await firecrawl.search(query, { limit: 5 });
return Response.json(results);
}
return new Response("Not found", { status: 404 });
},
});
console.log("Server running on port 3000");
```
Run it:
```bash theme={null}
bun run index.ts
```
## Scrape a page
Add a `/scrape` route to the same server:
```typescript theme={null}
if (req.method === "POST" && url.pathname === "/scrape") {
const { url: targetUrl } = await req.json();
const result = await firecrawl.scrape(targetUrl);
return Response.json(result);
}
```
## Interact with a page
Use interact to control a live browser session — click buttons, fill forms, and extract dynamic content.
```typescript theme={null}
if (req.method === "POST" && url.pathname === "/interact") {
const { url: targetUrl } = await req.json();
const result = await firecrawl.scrape(targetUrl, { formats: ['markdown'] });
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, { prompt: 'Search for iPhone 16 Pro Max' });
const response = await firecrawl.interact(scrapeId, { prompt: 'Click on the first result and tell me the price' });
await firecrawl.stopInteraction(scrapeId);
return Response.json({ output: response.output });
}
```
## Script usage
Use Firecrawl in a standalone Bun script:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
const app = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
const results = await app.search("firecrawl web scraping", { limit: 5 });
console.log(results);
```
```bash theme={null}
bun run search.ts
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Firecrawl in Claude & Claude Code
Source: https://docs.firecrawl.dev/quickstarts/claude-code
Search the web and read pages from Claude or your Claude Code session.
Give Claude the context API for AI agents: search the web and read pages from Claude or Claude Code. Choose the setup for the app you use. Both paths are optional; connect only the one you want.
## Optional: Add to Claude

Add to Claude
[Open](https://claude.ai/directory/connectors/firecrawl)
1. Open the Firecrawl connector using the button above.
2. Connect your Firecrawl account and approve access when prompted.
3. Start a new Claude conversation, enable Firecrawl, and ask it to search or read a page.
```text theme={null}
Use Firecrawl to search for the latest Next.js release notes and summarize the sources.
```
## Optional: Set up Claude Code
Connect Claude Code through the hosted MCP server. Run the command below, then sign in through your browser.
### 1. Add Firecrawl
Run:
```bash theme={null}
claude mcp add --transport http firecrawl https://mcp.firecrawl.dev/v2/mcp-oauth
```
`https://mcp.firecrawl.dev/v2/mcp-oauth` is a client configuration value, not a page to open directly in a browser.
### 2. Sign in and verify
Enter `/mcp` in Claude Code, choose `firecrawl`, and complete the browser sign-in. Start a new Claude Code session if you changed an existing Firecrawl connection.
Confirm that only one `firecrawl` server is active, then try:
```text theme={null}
Search for the latest Next.js release notes and summarize the sources.
```
```text theme={null}
Scrape https://firecrawl.dev and explain what it does.
```
## What you can do
> [card] [Search](/features/search)
>
> Find current information and read the content of relevant results.
> [card] [Scrape](/features/scrape)
>
> Turn URLs into clean markdown or structured data.
> [card] [Interact](/features/interact)
>
> Navigate, click, and fill forms to reach the data you need.
> [card] [Alexandria](/features/alexandria)
>
> Discover structured data tools, inspect inputs and pricing, then run them through Firecrawl.
## Other connection modes
* [Try keyless MCP](/mcp-server/keyless#try-keyless) for Search, Scrape, and Parse without an account or key.
* [Configure an API key](/mcp-server/keyless#add-an-api-key) for unattended use. Keep the secret outside agent chat and use an environment-variable reference.
* [Run MCP locally](/mcp-server/local) only when you need a local process or a self-hosted Firecrawl API. The local package requires Node.js 22 or newer.
## Optional: literature research
For paper and literature work, the research-index skill routes those queries to the `firecrawl_research_*` tools and the [Research Index](/features/research) instead of general web search:
```bash theme={null}
npx skills add firecrawl/skills@firecrawl-research-index
```
## Troubleshooting
* **A Firecrawl server already exists:** run `claude mcp remove firecrawl`, add the intended connection once, then start a new session.
* **The browser does not open:** enter `/mcp`, select `firecrawl`, and start authentication from the client.
* **The server shows `401`:** sign in again through `/mcp`; do not paste an API key into the conversation or OAuth URL.
# Firecrawl in Claude Desktop and Cowork
Source: https://docs.firecrawl.dev/quickstarts/claude-desktop
Connect Firecrawl once and use it in Claude Desktop chat, Cowork, and the Code tab.
Claude Desktop, Cowork, and the Code tab all read connectors from your Claude account. Connect Firecrawl once, under the server name `firecrawl`, and it is available in every tab.
| Setting | Value |
| - | - |
| Server name | `firecrawl` |
| Custom connector URL | `https://mcp.firecrawl.dev/v2/mcp-oauth` (only if you add a custom connector instead of the directory one) |
| Sign-in | Browser sign-in to Firecrawl, then approve a team |
`https://mcp.firecrawl.dev/v2/mcp-oauth` is a client configuration value, not a page to open directly in a browser.
## 1. Add the Firecrawl connector

Add to Claude
[Open](https://claude.ai/directory/connectors/firecrawl)
1. Open the [Firecrawl connector](https://claude.ai/directory/connectors/firecrawl) in the Claude connectors directory, or go to **Customize > Connectors** in Claude Desktop and search for Firecrawl.
2. Click **Connect**. Claude opens Firecrawl in your browser.
3. Sign in to Firecrawl, choose a team, and approve access.
On Team or Enterprise plans, an organization Owner may need to allow the connector before members can connect.
> [accordion] Can't use the directory connector? Add a custom connector
>
> 1. In Claude Desktop, go to **Customize > Connectors**.
> 2. Click **Add**, then add a custom connector.
> 3. Enter `firecrawl` as the name and `https://mcp.firecrawl.dev/v2/mcp-oauth` as the remote MCP server URL.
> 4. Keep the detected sign-in settings, add the connector, then click **Connect** and complete the browser sign-in.
>
> Organization Owners add custom connectors from **Organization settings > Connectors** instead.
## 2. Use it in Cowork and chat
In the Cowork or Chat tab, open the **+** menu next to the prompt box, go to **Connectors**, and make sure Firecrawl is enabled. Then try:
```text theme={null}
Use Firecrawl to search for the latest Next.js release notes and summarize the sources.
```
```text theme={null}
Scrape https://firecrawl.dev and explain what it does.
```
## 3. Use it in the Code tab
Local Code tab sessions can use the same connector. Click the **+** button next to the prompt box, select **Connectors**, and enable Firecrawl.
The Code tab also loads MCP servers you added to Claude Code, for example with `claude mcp add`. If you already set up Firecrawl there with the [Claude Code guide](/quickstarts/claude-code), keep the server name `firecrawl` and confirm that only one Firecrawl server is active in the session.
## Troubleshooting
* **Firecrawl tools don't appear.** Start a new conversation or session after connecting, and check that Firecrawl is enabled in the **Connectors** menu.
* **Firecrawl appears more than once.** Remove extra entries so a single connector named `firecrawl` remains. Connectors you add in **Customize > Connectors** work in Cowork; local servers in `claude_desktop_config.json` do not, so prefer the connector.
* **Wrong team.** Review or revoke the connection from [MCP settings](https://www.firecrawl.dev/app/settings?tab=mcp), then connect again and choose the right team.
## What you can do
> [card] [Search](/features/search)
>
> Find current information and read the content of relevant results.
> [card] [Scrape](/features/scrape)
>
> Turn URLs into clean markdown or structured data.
> [card] [Interact](/features/interact)
>
> Navigate, click, and fill forms to reach the data you need.
> [card] [Alexandria](/features/alexandria)
>
> Discover structured data tools, inspect inputs and pricing, then run them through Firecrawl.
## More
* [Get Started](/mcp-server) with Firecrawl MCP in other clients.
* [For Humans](/mcp-server/oauth) covers browser sign-in in Codex, Cursor, and other clients.
* [Choose a tool](/mcp-server/tools) to see what each Firecrawl MCP tool does.
# Cloudflare Workers
Source: https://docs.firecrawl.dev/quickstarts/cloudflare-workers
Use Firecrawl with Cloudflare Workers to search, scrape, and interact with web data at the edge.
## Prerequisites
* Wrangler CLI (`npm install -g wrangler`)
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
npm create cloudflare@latest my-scraper
cd my-scraper
npm install firecrawl
```
Add your API key as a secret:
```bash theme={null}
wrangler secret put FIRECRAWL_API_KEY
```
## Search the web
Create a handler that searches the web and returns results with full page content.
Edit `src/index.ts`:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
export interface Env {
FIRECRAWL_API_KEY: string;
}
export default {
async fetch(request: Request, env: Env): Promise {
const firecrawl = new Firecrawl({ apiKey: env.FIRECRAWL_API_KEY });
const url = new URL(request.url);
if (request.method === "POST" && url.pathname === "/search") {
const { query } = (await request.json()) as { query: string };
const results = await firecrawl.search(query, { limit: 5 });
return Response.json(results);
}
return new Response("Not found", { status: 404 });
},
};
```
## Scrape a page
Add a `/scrape` route to extract clean markdown from any URL.
```typescript theme={null}
if (request.method === "POST" && url.pathname === "/scrape") {
const { url: targetUrl } = (await request.json()) as { url: string };
const result = await firecrawl.scrape(targetUrl);
return Response.json(result);
}
```
## Interact with a page
Add an `/interact` route to control a live browser session — click buttons, fill forms, and extract dynamic content.
```typescript theme={null}
if (request.method === "POST" && url.pathname === "/interact") {
const result = await firecrawl.scrape("https://www.amazon.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, {
prompt: "Search for iPhone 16 Pro Max",
});
const response = await firecrawl.interact(scrapeId, {
prompt: "Click on the first result and tell me the price",
});
await firecrawl.stopInteraction(scrapeId);
return Response.json({ output: response.output });
}
```
## Deploy
```bash theme={null}
wrangler deploy
```
## Test it
```bash theme={null}
curl -X POST https://my-scraper..workers.dev/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# MCP Web Search & Scrape in Cursor
Source: https://docs.firecrawl.dev/quickstarts/cursor
Add web scraping and search to Cursor in 2 minutes
Connect Firecrawl to Cursor through the hosted MCP server, then sign in with your Firecrawl account to give Cursor's AI agent Search, Scrape, Parse, Crawl, Map, Interact, Agent, and Monitor for clean context from the web.

Add to Cursor
## Quick setup
1. Click **Add to Cursor** above to open the install dialog in Cursor.
2. Confirm the Firecrawl MCP server installation.
3. Use the server's sign-in option in Cursor to connect your Firecrawl account and approve access.
4. Confirm that Firecrawl's tools are available in Cursor.
> [accordion] Prefer to add the configuration manually?
>
> Add this to `~/.cursor/mcp.json`, or to `.cursor/mcp.json` in your project:
>
> ```json theme={null}
> {
> "mcpServers": {
> "firecrawl": {
> "url": "https://mcp.firecrawl.dev/v2/mcp-oauth"
> }
> }
> }
> ```
>
> Save the file, then complete the browser sign-in from Cursor.
The Cursor CLI reads the same `mcp.json`. Run `agent mcp login firecrawl` to sign in from the terminal.
See the [OAuth connection guide](/mcp-server/oauth) for more details. For unattended use, [configure an API key](/mcp-server/keyless#add-an-api-key).
## Try it
```text theme={null}
Search for the latest TypeScript release notes and summarize the sources.
```
```text theme={null}
Scrape https://firecrawl.dev and explain what it does.
```
## What you can do
> [card] [Search](/features/search)
>
> Find current information and read the content of relevant results.
> [card] [Scrape](/features/scrape)
>
> Turn URLs into clean markdown or structured data.
> [card] [Interact](/features/interact)
>
> Navigate, click, and fill forms to reach the data you need.
> [card] [Alexandria](/features/alexandria)
>
> Discover structured data tools, inspect inputs and pricing, then run them through Firecrawl.
## Troubleshooting
* **Server does not connect:** confirm the URL is exactly `https://mcp.firecrawl.dev/v2/mcp-oauth` and check the server's status under **Customize** or in the **MCP Logs** output.
* **Sign-in is required or expires:** start authentication again from Cursor's MCP server list under **Customize**.
* **Another Firecrawl connection already exists:** update the existing server to the OAuth URL and sign in so only one Firecrawl server is active.
# Deno Deploy
Source: https://docs.firecrawl.dev/quickstarts/deno-deploy
Use Firecrawl with Deno Deploy to search, scrape, and interact with web data at the edge.
## Prerequisites
* Deno 1.40+ or Deno 2
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
Create `main.ts`:
```typescript theme={null}
import Firecrawl from "npm:firecrawl";
const firecrawl = new Firecrawl({
apiKey: Deno.env.get("FIRECRAWL_API_KEY"),
});
```
## Search the web
Add a `/search` route that searches the web and returns results with full page content.
```typescript theme={null}
Deno.serve(async (req) => {
const url = new URL(req.url);
if (req.method === "POST" && url.pathname === "/search") {
const { query } = await req.json();
const results = await firecrawl.search(query, { limit: 5 });
return Response.json(results);
}
return new Response("Not found", { status: 404 });
});
```
## Scrape a page
Add a `/scrape` route to extract clean markdown from any URL.
```typescript theme={null}
if (req.method === "POST" && url.pathname === "/scrape") {
const { url: targetUrl } = await req.json();
const result = await firecrawl.scrape(targetUrl);
return Response.json(result);
}
```
## Interact with a page
Add an `/interact` route to control a live browser session — click buttons, fill forms, and extract dynamic content.
```typescript theme={null}
if (req.method === "POST" && url.pathname === "/interact") {
const result = await firecrawl.scrape("https://www.amazon.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, {
prompt: "Search for iPhone 16 Pro Max",
});
const response = await firecrawl.interact(scrapeId, {
prompt: "Click on the first result and tell me the price",
});
console.log(response.output);
await firecrawl.stopInteraction(scrapeId);
return Response.json({ output: response.output });
}
```
## Run locally
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY deno run --allow-net --allow-env main.ts
```
## Deploy
Install the Deno Deploy CLI (`deployctl`) and deploy:
```bash theme={null}
deployctl deploy --project=my-scraper main.ts
```
Set the environment variable in the Deno Deploy dashboard or via CLI:
```bash theme={null}
deployctl env set FIRECRAWL_API_KEY=fc-YOUR-API-KEY --project=my-scraper
```
## Test it
```bash theme={null}
curl -X POST https://my-scraper.deno.dev/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Django
Source: https://docs.firecrawl.dev/quickstarts/django
Use Firecrawl with Django to scrape, search, and interact with web data in your Python web application.
## Prerequisites
* Django 4+ project
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
pip install firecrawl
```
Add your API key to your Django settings or environment:
```bash theme={null}
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Create views
Add search, scrape, and interact views to your Django app. In `views.py`:
```python theme={null}
import json
import os
from django.http import JsonResponse
from django.views.decorators.csrf import csrf_exempt
from django.views.decorators.http import require_POST
from firecrawl import Firecrawl
firecrawl = Firecrawl(api_key=os.environ["FIRECRAWL_API_KEY"])
@csrf_exempt
@require_POST
def search_view(request):
body = json.loads(request.body)
results = firecrawl.search(body["query"], limit=body.get("limit", 5))
return JsonResponse(
[{"title": r.title, "url": r.url} for r in results.web],
safe=False,
)
@csrf_exempt
@require_POST
def scrape_view(request):
body = json.loads(request.body)
result = firecrawl.scrape(body["url"])
return JsonResponse({
"markdown": result.markdown,
"metadata": result.metadata,
})
@csrf_exempt
@require_POST
def interact_start_view(request):
body = json.loads(request.body)
result = firecrawl.scrape(body["url"], formats=["markdown"])
return JsonResponse({"scrape_id": result.metadata.scrape_id})
@csrf_exempt
@require_POST
def interact_view(request):
body = json.loads(request.body)
response = firecrawl.interact(body["scrape_id"], prompt=body["prompt"])
return JsonResponse({"output": response.output})
@csrf_exempt
@require_POST
def interact_stop_view(request):
body = json.loads(request.body)
firecrawl.stop_interaction(body["scrape_id"])
return JsonResponse({"status": "stopped"})
```
## Wire up URLs
In `urls.py`:
```python theme={null}
from django.urls import path
from . import views
urlpatterns = [
path("api/search/", views.search_view),
path("api/scrape/", views.scrape_view),
path("api/interact/start/", views.interact_start_view),
path("api/interact/", views.interact_view),
path("api/interact/stop/", views.interact_stop_view),
]
```
## Test it
```bash theme={null}
python manage.py runserver
# Search the web
curl -X POST http://localhost:8000/api/search/ \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping", "limit": 5}'
# Scrape a page
curl -X POST http://localhost:8000/api/scrape/ \
-H "Content-Type: application/json" \
-d '{"url": "https://example.com"}'
# Start an interactive session
curl -X POST http://localhost:8000/api/interact/start/ \
-H "Content-Type: application/json" \
-d '{"url": "https://www.amazon.com"}'
```
## Management command
Use Firecrawl in a Django management command for scripts and data pipelines. Create `management/commands/scrape.py`:
```python theme={null}
import os
from django.core.management.base import BaseCommand
from firecrawl import Firecrawl
class Command(BaseCommand):
help = "Scrape a URL and print the markdown"
def add_arguments(self, parser):
parser.add_argument("url", type=str)
def handle(self, *args, **options):
firecrawl = Firecrawl(api_key=os.environ["FIRECRAWL_API_KEY"])
result = firecrawl.scrape(options["url"])
self.stdout.write(result.markdown)
```
```bash theme={null}
python manage.py scrape https://example.com
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Python SDK reference](/sdks/python)
>
> Full SDK reference with crawl, map, async, and more
# .NET
Source: https://docs.firecrawl.dev/quickstarts/dotnet
Get started with Firecrawl in .NET. Scrape, search, and interact with web data using the REST API.
## Prerequisites
* .NET 6.0+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Search the web
Firecrawl works with .NET through the REST API using `HttpClient`.
```csharp theme={null}
using System.Net.Http.Headers;
using System.Text;
using System.Text.Json;
var apiKey = Environment.GetEnvironmentVariable("FIRECRAWL_API_KEY");
var client = new HttpClient();
client.DefaultRequestHeaders.Authorization = new AuthenticationHeaderValue("Bearer", apiKey);
var content = new StringContent(
JsonSerializer.Serialize(new { query = "firecrawl web scraping", limit = 5 }),
Encoding.UTF8,
"application/json"
);
var response = await client.PostAsync("https://api.firecrawl.dev/v2/search", content);
var json = await response.Content.ReadAsStringAsync();
Console.WriteLine(json);
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "success": true,
> "data": {
> "web": [
> {
> "url": "https://docs.firecrawl.dev",
> "title": "Firecrawl Documentation",
> "markdown": "# Firecrawl\n\nFirecrawl is the context API for AI agents..."
> }
> ]
> }
> }
> ```
## Scrape a page
```csharp theme={null}
var scrapeContent = new StringContent(
JsonSerializer.Serialize(new { url = "https://example.com" }),
Encoding.UTF8,
"application/json"
);
var scrapeResponse = await client.PostAsync("https://api.firecrawl.dev/v2/scrape", scrapeContent);
var scrapeJson = await scrapeResponse.Content.ReadAsStringAsync();
using var doc = JsonDocument.Parse(scrapeJson);
var markdown = doc.RootElement.GetProperty("data").GetProperty("markdown").GetString();
Console.WriteLine(markdown);
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "success": true,
> "data": {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "sourceURL": "https://example.com"
> }
> }
> }
> ```
## Interact with a page
Start a browser session, interact with the page using natural-language prompts, then close the session.
### Step 1 — Scrape to start a session
```csharp theme={null}
var sessionContent = new StringContent(
JsonSerializer.Serialize(new { url = "https://www.amazon.com", formats = new[] { "markdown" } }),
Encoding.UTF8,
"application/json"
);
var sessionResponse = await client.PostAsync("https://api.firecrawl.dev/v2/scrape", sessionContent);
var sessionJson = await sessionResponse.Content.ReadAsStringAsync();
using var sessionDoc = JsonDocument.Parse(sessionJson);
var scrapeId = sessionDoc.RootElement
.GetProperty("data")
.GetProperty("metadata")
.GetProperty("scrapeId")
.GetString();
Console.WriteLine($"scrapeId: {scrapeId}");
```
### Step 2 — Send interactions
```csharp theme={null}
var interactUrl = $"https://api.firecrawl.dev/v2/scrape/{scrapeId}/interact";
// Search for a product
var searchBody = new StringContent(
JsonSerializer.Serialize(new { prompt = "Search for iPhone 16 Pro Max" }),
Encoding.UTF8,
"application/json"
);
var searchResult = await client.PostAsync(interactUrl, searchBody);
Console.WriteLine(await searchResult.Content.ReadAsStringAsync());
// Click on the first result
var clickBody = new StringContent(
JsonSerializer.Serialize(new { prompt = "Click on the first result and tell me the price" }),
Encoding.UTF8,
"application/json"
);
var clickResult = await client.PostAsync(interactUrl, clickBody);
Console.WriteLine(await clickResult.Content.ReadAsStringAsync());
```
### Step 3 — Stop the session
```csharp theme={null}
await client.DeleteAsync(interactUrl);
Console.WriteLine("Session stopped");
```
## Reusable client class
For repeated use, wrap the API in a typed client:
```csharp theme={null}
using System.Net.Http.Headers;
using System.Text;
using System.Text.Json;
public class FirecrawlClient
{
private readonly HttpClient _http;
private const string BaseUrl = "https://api.firecrawl.dev/v2";
public FirecrawlClient(string apiKey)
{
_http = new HttpClient();
_http.DefaultRequestHeaders.Authorization = new AuthenticationHeaderValue("Bearer", apiKey);
}
private async Task PostAsync(string endpoint, object payload)
{
var content = new StringContent(
JsonSerializer.Serialize(payload),
Encoding.UTF8,
"application/json"
);
var response = await _http.PostAsync($"{BaseUrl}{endpoint}", content);
response.EnsureSuccessStatusCode();
var json = await response.Content.ReadAsStringAsync();
return JsonDocument.Parse(json);
}
public async Task ScrapeAsync(string url)
{
return await PostAsync("/scrape", new { url });
}
public async Task SearchAsync(string query, int limit = 5)
{
return await PostAsync("/search", new { query, limit });
}
}
// Usage
var firecrawl = new FirecrawlClient(Environment.GetEnvironmentVariable("FIRECRAWL_API_KEY")!);
var result = await firecrawl.SearchAsync("firecrawl web scraping");
Console.WriteLine(result.RootElement);
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [API Reference](/api-reference/v2-introduction)
>
> Complete REST API documentation
# Elixir
Source: https://docs.firecrawl.dev/quickstarts/elixir
Get started with Firecrawl in Elixir. Search, scrape, and interact with web data using the official SDK.
## Prerequisites
* Elixir 1.14+ and OTP 25+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
Add `firecrawl` to your `mix.exs`:
```elixir theme={null}
defp deps do
[
{:firecrawl, "~> 1.0"}
]
end
```
Configure your API key in `config/config.exs`:
```elixir theme={null}
config :firecrawl, api_key: System.get_env("FIRECRAWL_API_KEY")
```
## Search the web
```elixir theme={null}
{:ok, result} = Firecrawl.search_and_scrape(query: "firecrawl web scraping", limit: 5)
for entry <- result.body["data"]["web"] do
IO.puts("#{entry["title"]} - #{entry["url"]}")
end
```
## Scrape a page
```elixir theme={null}
{:ok, result} = Firecrawl.scrape_and_extract_from_url(url: "https://example.com")
IO.puts(result.body["data"]["markdown"])
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "success": true,
> "data": {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "sourceURL": "https://example.com"
> }
> }
> }
> ```
## Interact with a page
Scrape a page, then keep working with it using the browser session API.
```elixir theme={null}
{:ok, scrape} = Firecrawl.scrape_and_extract_from_url(
url: "https://www.amazon.com",
formats: ["markdown"]
)
scrape_id = get_in(scrape.body, ["data", "metadata", "scrapeId"])
# Use the REST API for interact (prompt-based)
headers = [
{"Authorization", "Bearer #{Application.get_env(:firecrawl, :api_key)}"},
{"Content-Type", "application/json"}
]
{:ok, _} = Req.post(
"https://api.firecrawl.dev/v2/scrape/#{scrape_id}/interact",
json: %{prompt: "Search for iPhone 16 Pro Max"},
headers: headers
)
{:ok, response} = Req.post(
"https://api.firecrawl.dev/v2/scrape/#{scrape_id}/interact",
json: %{prompt: "Click on the first result and tell me the price"},
headers: headers
)
IO.inspect(response.body)
# Stop the session
Req.delete(
"https://api.firecrawl.dev/v2/scrape/#{scrape_id}/interact",
headers: headers
)
```
## Environment variable
Set `FIRECRAWL_API_KEY` instead of hardcoding:
```bash theme={null}
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Elixir SDK reference](/sdks/elixir)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Express
Source: https://docs.firecrawl.dev/quickstarts/express
Use Firecrawl with Express to build APIs that search, scrape, and interact with the web.
## Prerequisites
* Node.js 18+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
npm install express firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
```javascript theme={null}
import express from "express";
import { Firecrawl } from "firecrawl";
const app = express();
app.use(express.json());
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
app.post("/search", async (req, res) => {
try {
const { query } = req.body;
const results = await firecrawl.search(query, { limit: 5 });
res.json(results);
} catch (error) {
res.status(500).json({ error: error.message });
}
});
app.listen(3000, () => console.log("Server running on port 3000"));
```
## Scrape a page
```javascript theme={null}
app.post("/scrape", async (req, res) => {
try {
const { url } = req.body;
const result = await firecrawl.scrape(url);
res.json(result);
} catch (error) {
res.status(500).json({ error: error.message });
}
});
```
## Interact with a page
Use interact to control a live browser session — click buttons, fill forms, and extract dynamic content.
```javascript theme={null}
app.post("/interact", async (req, res) => {
try {
const { url } = req.body;
const result = await firecrawl.scrape(url, { formats: ['markdown'] });
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, { prompt: 'Search for iPhone 16 Pro Max' });
const response = await firecrawl.interact(scrapeId, { prompt: 'Click on the first result and tell me the price' });
await firecrawl.stopInteraction(scrapeId);
res.json({ output: response.output });
} catch (error) {
res.status(500).json({ error: error.message });
}
});
```
## Test it
```bash theme={null}
curl -X POST http://localhost:3000/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# MCP Web Search & Scrape in Factory Droid
Source: https://docs.firecrawl.dev/quickstarts/factory-droid
Add Firecrawl web search and scraping to Factory Droid
Connect [Factory Droid](https://docs.factory.com/droid-cli/overview), Factory's coding agent CLI (`droid`), to Firecrawl through the hosted MCP server, then sign in with your Firecrawl account so Droid can search, scrape, and interact with the web.
## Quick setup
### 1. Add Firecrawl
Install the [Droid CLI](https://docs.factory.com/droid-cli/quickstart) if you haven't already, then run:
```bash theme={null}
droid mcp add firecrawl https://mcp.firecrawl.dev/v2/mcp-oauth --type http
```
`https://mcp.firecrawl.dev/v2/mcp-oauth` is a client configuration value, not a page to open directly in a browser.
### 2. Sign in and verify
Run:
```bash theme={null}
droid mcp auth
```
Droid opens the Firecrawl sign-in in your browser, where you choose a team and approve the connection. You can also enter `/mcp` inside Droid, select `firecrawl`, and authenticate from there.
Run `droid mcp list` and confirm that `firecrawl` is connected. Then start Droid from your project's root:
```bash theme={null}
droid
```
Try:
```text theme={null}
Search the web for the latest Next.js release notes and summarize the sources.
```
```text theme={null}
Scrape https://docs.firecrawl.dev and list the top-level sections.
```
## What you can do
> [card] [Search](/features/search)
>
> Find current information and read the content of relevant results.
> [card] [Scrape](/features/scrape)
>
> Turn URLs into clean markdown or structured data.
> [card] [Interact](/features/interact)
>
> Navigate, click, and fill forms to reach the data you need.
> [card] [Alexandria](/features/alexandria)
>
> Discover structured data tools, inspect inputs and pricing, then run them through Firecrawl.
## Migrate from v1 to v2 with Droid
The v1 API stops working on December 10, 2026. The [v1 to v2 migration guide](/migrate-to-v2) has a prompt that finds every v1 call in a project and rewrites it for v2. Copy the prompt from that page, then run it with Droid. The migration does not need the MCP server above.
* **Interactive:** run `droid` from your project's root and paste the prompt. By default, Droid asks before it edits files or runs commands.
* **Headless:** save the prompt to a file outside your project, such as `~/firecrawl-v2-migration.txt`. Sign in to Droid or set `FACTORY_API_KEY`, then run this from your project's root:
```bash theme={null}
droid exec --auto medium -f ~/firecrawl-v2-migration.txt
```
`--auto medium` lets Droid edit files, install the SDK, and run your tests, but not push. If Droid needs a command above that level, it stops and leaves its edits in your working tree.
## Other connection modes
* [Try keyless MCP](/mcp-server/keyless#try-keyless) for Search, Scrape, and Parse without an account or key.
* [Configure an API key](/mcp-server/keyless#add-an-api-key) for unattended use. Keep the secret outside agent chat and source control.
* [Run MCP locally](/mcp-server/local) only when you need a local process or a self-hosted Firecrawl API. The local package requires Node.js 22 or newer.
## Troubleshooting
* **A Firecrawl server already exists:** run `droid mcp remove firecrawl`, add the intended connection once, then start a new session.
* **`droid mcp list` shows `needs authentication`:** run `droid mcp auth`, or enter `/mcp` in Droid, select `firecrawl`, and sign in again. Do not paste an API key into the conversation or the OAuth URL.
* **`droid exec` stops with an authentication error:** sign in to Droid, or set `FACTORY_API_KEY` to a key from your [Factory settings](https://app.factory.ai/settings/api-keys).
* **`droid exec` stops partway through the migration:** Droid needed a command above `--auto medium`. Check `git status`, then finish in an interactive `droid` session.
# FastAPI
Source: https://docs.firecrawl.dev/quickstarts/fastapi
Use Firecrawl with FastAPI to build async web scraping and search APIs in Python.
## Prerequisites
* Python 3.8+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
pip install fastapi uvicorn firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Create the API
Create `main.py`:
```python theme={null}
import os
from fastapi import FastAPI
from pydantic import BaseModel
from firecrawl import Firecrawl
app = FastAPI()
firecrawl = Firecrawl(api_key=os.environ["FIRECRAWL_API_KEY"])
class SearchRequest(BaseModel):
query: str
limit: int = 5
class ScrapeRequest(BaseModel):
url: str
class InteractRequest(BaseModel):
scrape_id: str
prompt: str
@app.post("/search")
async def search(req: SearchRequest):
results = firecrawl.search(req.query, limit=req.limit)
return [{"title": r.title, "url": r.url} for r in results.web]
@app.post("/scrape")
async def scrape(req: ScrapeRequest):
result = firecrawl.scrape(req.url)
return {"markdown": result.markdown, "metadata": result.metadata}
@app.post("/interact/start")
async def interact_start(req: ScrapeRequest):
result = firecrawl.scrape(req.url, formats=["markdown"])
return {"scrape_id": result.metadata.scrape_id}
@app.post("/interact")
async def interact(req: InteractRequest):
response = firecrawl.interact(req.scrape_id, prompt=req.prompt)
return {"output": response.output}
@app.post("/interact/stop")
async def interact_stop(req: InteractRequest):
firecrawl.stop_interaction(req.scrape_id)
return {"status": "stopped"}
```
## Run it
```bash theme={null}
uvicorn main:app --reload
```
## Test it
```bash theme={null}
# Search the web
curl -X POST http://localhost:8000/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping", "limit": 5}'
# Scrape a page
curl -X POST http://localhost:8000/scrape \
-H "Content-Type: application/json" \
-d '{"url": "https://example.com"}'
# Start an interactive session, then send prompts
curl -X POST http://localhost:8000/interact/start \
-H "Content-Type: application/json" \
-d '{"url": "https://www.amazon.com"}'
```
FastAPI auto-generates interactive docs at `http://localhost:8000/docs`.
## Async variant
For better concurrency under load, use `AsyncFirecrawl`:
```python theme={null}
from firecrawl import AsyncFirecrawl
async_firecrawl = AsyncFirecrawl(api_key=os.environ["FIRECRAWL_API_KEY"])
@app.post("/scrape-async")
async def scrape_async(req: ScrapeRequest):
result = await async_firecrawl.scrape(req.url)
return {"markdown": result.markdown}
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Python SDK reference](/sdks/python)
>
> Full SDK reference with crawl, map, async, and more
# Fastify
Source: https://docs.firecrawl.dev/quickstarts/fastify
Use Firecrawl with Fastify to build high-performance APIs that search, scrape, and interact with the web.
## Prerequisites
* Node.js 18+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
npm install fastify firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
```javascript theme={null}
import Fastify from "fastify";
import { Firecrawl } from "firecrawl";
const fastify = Fastify({ logger: true });
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
fastify.post("/search", async (request) => {
const { query } = request.body;
return firecrawl.search(query, { limit: 5 });
});
fastify.listen({ port: 3000 });
```
## Scrape a page
```javascript theme={null}
fastify.post("/scrape", async (request) => {
const { url } = request.body;
return firecrawl.scrape(url);
});
```
## Interact with a page
Use interact to control a live browser session — click buttons, fill forms, and extract dynamic content.
```javascript theme={null}
fastify.post("/interact", async (request) => {
const { url } = request.body;
const result = await firecrawl.scrape(url, { formats: ['markdown'] });
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, { prompt: 'Search for iPhone 16 Pro Max' });
const response = await firecrawl.interact(scrapeId, { prompt: 'Click on the first result and tell me the price' });
await firecrawl.stopInteraction(scrapeId);
return { output: response.output };
});
```
## As a Fastify plugin
Encapsulate the client in a plugin for reuse across routes:
```javascript theme={null}
import fp from "fastify-plugin";
import { Firecrawl } from "firecrawl";
export default fp(async function firecrawlPlugin(fastify) {
const client = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
fastify.decorate("firecrawl", client);
});
```
Register the plugin, then use `fastify.firecrawl` in any route:
```javascript theme={null}
fastify.register(firecrawlPlugin);
fastify.post("/search", async function (request) {
const { query } = request.body;
return this.firecrawl.search(query, { limit: 5 });
});
```
## Test it
```bash theme={null}
curl -X POST http://localhost:3000/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Flask
Source: https://docs.firecrawl.dev/quickstarts/flask
Use Firecrawl with Flask to build web scraping and search APIs in Python.
## Prerequisites
* Python 3.8+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
pip install flask firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Create the app
Create `app.py`:
```python theme={null}
import os
from flask import Flask, request, jsonify
from firecrawl import Firecrawl
app = Flask(__name__)
firecrawl = Firecrawl(api_key=os.environ["FIRECRAWL_API_KEY"])
@app.post("/search")
def search():
data = request.get_json()
results = firecrawl.search(data["query"], limit=data.get("limit", 5))
return jsonify([{"title": r.title, "url": r.url} for r in results.web])
@app.post("/scrape")
def scrape():
data = request.get_json()
result = firecrawl.scrape(data["url"])
return jsonify(markdown=result.markdown, metadata=result.metadata)
@app.post("/interact/start")
def interact_start():
data = request.get_json()
result = firecrawl.scrape(data["url"], formats=["markdown"])
return jsonify(scrape_id=result.metadata.scrape_id)
@app.post("/interact")
def interact():
data = request.get_json()
response = firecrawl.interact(data["scrape_id"], prompt=data["prompt"])
return jsonify(output=response.output)
@app.post("/interact/stop")
def interact_stop():
data = request.get_json()
firecrawl.stop_interaction(data["scrape_id"])
return jsonify(status="stopped")
if __name__ == "__main__":
app.run(debug=True)
```
## Run it
```bash theme={null}
flask run
```
## Test it
```bash theme={null}
# Search the web
curl -X POST http://localhost:5000/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping", "limit": 5}'
# Scrape a page
curl -X POST http://localhost:5000/scrape \
-H "Content-Type: application/json" \
-d '{"url": "https://example.com"}'
# Start an interactive session
curl -X POST http://localhost:5000/interact/start \
-H "Content-Type: application/json" \
-d '{"url": "https://www.amazon.com"}'
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Python SDK reference](/sdks/python)
>
> Full SDK reference with crawl, map, async, and more
# Go
Source: https://docs.firecrawl.dev/quickstarts/go
Get started with Firecrawl in Go. Scrape, search, and interact with web data using the REST API.
## Prerequisites
* Go 1.21+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Search the web
Firecrawl works with Go through the REST API. Use `net/http` to make requests directly.
```go theme={null}
package main
import (
"bytes"
"encoding/json"
"fmt"
"io"
"net/http"
"os"
)
func main() {
apiKey := os.Getenv("FIRECRAWL_API_KEY")
body, _ := json.Marshal(map[string]interface{}{
"query": "firecrawl web scraping",
"limit": 5,
})
req, _ := http.NewRequest("POST", "https://api.firecrawl.dev/v2/search", bytes.NewReader(body))
req.Header.Set("Authorization", "Bearer "+apiKey)
req.Header.Set("Content-Type", "application/json")
resp, err := http.DefaultClient.Do(req)
if err != nil {
fmt.Fprintf(os.Stderr, "request failed: %v\n", err)
os.Exit(1)
}
defer resp.Body.Close()
result, _ := io.ReadAll(resp.Body)
fmt.Println(string(result))
}
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "success": true,
> "data": {
> "web": [
> {
> "url": "https://docs.firecrawl.dev",
> "title": "Firecrawl Documentation",
> "markdown": "# Firecrawl\n\nFirecrawl is the context API for AI agents..."
> }
> ]
> }
> }
> ```
## Scrape a page
```go theme={null}
body, _ := json.Marshal(map[string]string{
"url": "https://example.com",
})
req, _ := http.NewRequest("POST", "https://api.firecrawl.dev/v2/scrape", bytes.NewReader(body))
req.Header.Set("Authorization", "Bearer "+apiKey)
req.Header.Set("Content-Type", "application/json")
resp, err := http.DefaultClient.Do(req)
if err != nil {
fmt.Fprintf(os.Stderr, "request failed: %v\n", err)
os.Exit(1)
}
defer resp.Body.Close()
result, _ := io.ReadAll(resp.Body)
fmt.Println(string(result))
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "success": true,
> "data": {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "sourceURL": "https://example.com"
> }
> }
> }
> ```
## Interact with a page
Start a browser session, interact with the page using natural-language prompts, then close the session.
### Step 1 — Scrape to start a session
```go theme={null}
body, _ := json.Marshal(map[string]interface{}{
"url": "https://www.amazon.com",
"formats": []string{"markdown"},
})
req, _ := http.NewRequest("POST", "https://api.firecrawl.dev/v2/scrape", bytes.NewReader(body))
req.Header.Set("Authorization", "Bearer "+apiKey)
req.Header.Set("Content-Type", "application/json")
resp, err := http.DefaultClient.Do(req)
if err != nil {
fmt.Fprintf(os.Stderr, "request failed: %v\n", err)
os.Exit(1)
}
defer resp.Body.Close()
var scrapeResult map[string]interface{}
json.NewDecoder(resp.Body).Decode(&scrapeResult)
data := scrapeResult["data"].(map[string]interface{})
metadata := data["metadata"].(map[string]interface{})
scrapeId := metadata["scrapeId"].(string)
fmt.Println("scrapeId:", scrapeId)
```
### Step 2 — Send interactions
```go theme={null}
// Search for a product
interactBody, _ := json.Marshal(map[string]string{
"prompt": "Search for iPhone 16 Pro Max",
})
interactURL := fmt.Sprintf("https://api.firecrawl.dev/v2/scrape/%s/interact", scrapeId)
req, _ = http.NewRequest("POST", interactURL, bytes.NewReader(interactBody))
req.Header.Set("Authorization", "Bearer "+apiKey)
req.Header.Set("Content-Type", "application/json")
resp, err = http.DefaultClient.Do(req)
if err != nil {
fmt.Fprintf(os.Stderr, "interact failed: %v\n", err)
os.Exit(1)
}
defer resp.Body.Close()
result, _ := io.ReadAll(resp.Body)
fmt.Println(string(result))
// Click on the first result
interactBody, _ = json.Marshal(map[string]string{
"prompt": "Click on the first result and tell me the price",
})
req, _ = http.NewRequest("POST", interactURL, bytes.NewReader(interactBody))
req.Header.Set("Authorization", "Bearer "+apiKey)
req.Header.Set("Content-Type", "application/json")
resp, err = http.DefaultClient.Do(req)
if err != nil {
fmt.Fprintf(os.Stderr, "interact failed: %v\n", err)
os.Exit(1)
}
defer resp.Body.Close()
result, _ = io.ReadAll(resp.Body)
fmt.Println(string(result))
```
### Step 3 — Stop the session
```go theme={null}
req, _ = http.NewRequest("DELETE", interactURL, nil)
req.Header.Set("Authorization", "Bearer "+apiKey)
resp, err = http.DefaultClient.Do(req)
if err != nil {
fmt.Fprintf(os.Stderr, "delete failed: %v\n", err)
os.Exit(1)
}
defer resp.Body.Close()
fmt.Println("Session stopped")
```
## Reusable helper
For repeated use, wrap the API in a small helper:
```go theme={null}
type FirecrawlClient struct {
APIKey string
BaseURL string
Client *http.Client
}
func NewFirecrawlClient(apiKey string) *FirecrawlClient {
return &FirecrawlClient{
APIKey: apiKey,
BaseURL: "https://api.firecrawl.dev/v2",
Client: &http.Client{},
}
}
func (fc *FirecrawlClient) post(endpoint string, payload interface{}) ([]byte, error) {
body, err := json.Marshal(payload)
if err != nil {
return nil, err
}
req, err := http.NewRequest("POST", fc.BaseURL+endpoint, bytes.NewReader(body))
if err != nil {
return nil, err
}
req.Header.Set("Authorization", "Bearer "+fc.APIKey)
req.Header.Set("Content-Type", "application/json")
resp, err := fc.Client.Do(req)
if err != nil {
return nil, err
}
defer resp.Body.Close()
return io.ReadAll(resp.Body)
}
func (fc *FirecrawlClient) Scrape(url string) ([]byte, error) {
return fc.post("/scrape", map[string]string{"url": url})
}
func (fc *FirecrawlClient) Search(query string, limit int) ([]byte, error) {
return fc.post("/search", map[string]interface{}{"query": query, "limit": limit})
}
```
> [!NOTE]
>
> A [community Go SDK](https://github.com/firecrawl/firecrawl-go) is available for the v1 API. See the [Go SDK docs](/sdks/go) for details.
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [API Reference](/api-reference/v2-introduction)
>
> Complete REST API documentation
# Firecrawl in Grok Bot
Source: https://docs.firecrawl.dev/quickstarts/grok-bot
Add the Firecrawl plugin to Grok Bot to search the web, read pages, and work with live web data.
[Grok Bot](https://x.ai/bot) is xAI's agent app. Firecrawl is listed as a Grok Bot plugin, so your Bots can search the web, scrape pages, and interact with dynamic sites through Firecrawl after you sign in once.

Add to Grok Bot
[Open](https://x.ai/bot/plugin/789)
## Install Firecrawl
**1. Open the Firecrawl plugin**
Click **Add to Grok Bot** above to open Firecrawl's plugin listing, then select **Add to Grok Bot** there. The Grok Bot desktop app opens to finish the install. You can also open **Connect apps** from the Grok Bot sidebar and search for **Firecrawl**.
**2. Sign in to Firecrawl**
When Grok Bot asks you to authorize the plugin, finish the Firecrawl sign-in in your browser, choose a team, and approve access. Grok Bot shows the connection once sign-in completes.
**3. Start a task**
Confirm Firecrawl appears under **Installed** in **Connect apps**. In a chat, type `@` and choose Firecrawl to attach it to the task, or ask your Bot to use Firecrawl with the prompt below.
The plugin connects to Firecrawl's hosted MCP server with browser sign-in and includes Firecrawl skills. You do not need to configure an MCP server, copy an API key, or install skills separately. Connected apps are account-wide, so every Bot on your Grok Bot account can use Firecrawl.
## Try it in Grok Bot
```text theme={null}
Using Firecrawl, look up the latest AI news and scrape the top result.
```
```text theme={null}
Use Firecrawl to find the latest Next.js release notes.
Read the official sources and summarize what changed, with links.
```
## What you can do
> [card] [Search](/features/search)
>
> Find current information and read the content of relevant results.
> [card] [Scrape](/features/scrape)
>
> Turn URLs into clean markdown or structured data.
> [card] [Interact](/features/interact)
>
> Navigate, click, and fill forms to reach the data you need.
> [card] [Alexandria](/features/alexandria)
>
> Discover structured data tools, inspect inputs and pricing, then run them through Firecrawl.
## If Firecrawl does not appear
* **The plugin shows Needs auth or Disconnected:** open Firecrawl in **Connect apps** and choose **Authenticate**, or **Reconnect**, to bring the sign-in page back.
* **Sign-in did not finish:** start it again from the plugin and complete the Firecrawl sign-in in your browser.
* **The Bot says Firecrawl is missing:** check that Firecrawl is listed under **Installed** in **Connect apps**, then start a new message.
Review or revoke the connection under [Connected apps in Settings](https://www.firecrawl.dev/app/settings?tab=mcp). For other clients, see the [For Humans sign-in guide](/mcp-server/oauth). Using xAI's coding CLI instead? Follow the [Grok Build guide](/quickstarts/grok-build).
# Hono
Source: https://docs.firecrawl.dev/quickstarts/hono
Use Firecrawl with Hono to build lightweight APIs that search, scrape, and interact with the web and run anywhere.
## Prerequisites
* Node.js 18+, Bun, or Deno
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
npm install hono firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
```typescript theme={null}
import { Hono } from "hono";
import { Firecrawl } from "firecrawl";
const app = new Hono();
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
app.post("/search", async (c) => {
const { query } = await c.req.json();
const results = await firecrawl.search(query, { limit: 5 });
return c.json(results);
});
export default app;
```
## Scrape a page
```typescript theme={null}
app.post("/scrape", async (c) => {
const { url } = await c.req.json();
const result = await firecrawl.scrape(url);
return c.json(result);
});
```
## Interact with a page
Use interact to control a live browser session — click buttons, fill forms, and extract dynamic content.
```typescript theme={null}
app.post("/interact", async (c) => {
const { url } = await c.req.json();
const result = await firecrawl.scrape(url, { formats: ['markdown'] });
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, { prompt: 'Search for iPhone 16 Pro Max' });
const response = await firecrawl.interact(scrapeId, { prompt: 'Click on the first result and tell me the price' });
await firecrawl.stopInteraction(scrapeId);
return c.json({ output: response.output });
});
```
## Deploy anywhere
Hono runs on multiple runtimes. For Cloudflare Workers, pass the API key from the environment binding:
```typescript theme={null}
import { Hono } from "hono";
import { Firecrawl } from "firecrawl";
type Bindings = { FIRECRAWL_API_KEY: string };
const app = new Hono<{ Bindings: Bindings }>();
app.post("/search", async (c) => {
const firecrawl = new Firecrawl({ apiKey: c.env.FIRECRAWL_API_KEY });
const { query } = await c.req.json();
const results = await firecrawl.search(query, { limit: 5 });
return c.json(results);
});
export default app;
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Java
Source: https://docs.firecrawl.dev/quickstarts/java
Get started with Firecrawl in Java. Search, scrape, and interact with web data using the official SDK.
## Prerequisites
* Java 11+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
> [tab] Gradle (Kotlin DSL)
>
> ```kotlin theme={null}
> dependencies {
> implementation("com.firecrawl:firecrawl-java:1.18.7")
> }
> ```
> [tab] Maven
>
> ```xml theme={null}
>
> com.firecrawl
> firecrawl-java
> 1.18.7
>
> ```
## Search the web
```java theme={null}
import com.firecrawl.client.FirecrawlClient;
import com.firecrawl.models.SearchData;
import com.firecrawl.models.SearchOptions;
public class Main {
public static void main(String[] args) {
FirecrawlClient client = FirecrawlClient.builder()
.apiKey("fc-YOUR-API-KEY")
.build();
SearchData results = client.search(
"firecrawl web scraping",
SearchOptions.builder().limit(5).build()
);
if (results.getWeb() != null) {
for (var result : results.getWeb()) {
System.out.println(result.get("title") + " - " + result.get("url"));
}
}
}
}
```
## Scrape a page
```java theme={null}
import com.firecrawl.models.Document;
Document doc = client.scrape("https://example.com");
System.out.println(doc.getMarkdown());
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "sourceURL": "https://example.com"
> }
> }
> ```
## Interact with a page
Open a browser session, run Playwright code against it, and close it when done:
```java theme={null}
import com.firecrawl.models.ScrapeOptions;
import com.firecrawl.models.BrowserExecuteResponse;
import java.util.List;
Document doc = client.scrape("https://www.amazon.com",
ScrapeOptions.builder().formats(List.of((Object) "markdown")).build());
String scrapeId = (String) doc.getMetadata().get("scrapeId");
BrowserExecuteResponse run = client.interact(scrapeId,
"const title = await page.title(); console.log(title);");
System.out.println(run.getStdout());
client.stopInteractiveBrowser(scrapeId);
```
## Environment variable
Instead of passing `apiKey` directly, set the `FIRECRAWL_API_KEY` environment variable:
```bash theme={null}
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
```java theme={null}
FirecrawlClient client = FirecrawlClient.fromEnv();
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Java SDK reference](/sdks/java)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Laravel
Source: https://docs.firecrawl.dev/quickstarts/laravel
Use Firecrawl with Laravel to search, scrape, and interact with web data using the REST API.
## Prerequisites
* Laravel 10+ project
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Configuration
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
Add the config entry to `config/services.php`:
```php theme={null}
'firecrawl' => [
'api_key' => env('FIRECRAWL_API_KEY'),
'base_url' => env('FIRECRAWL_API_URL', 'https://api.firecrawl.dev/v2'),
],
```
## Create a service class
Create `app/Services/FirecrawlService.php`:
```php theme={null}
apiKey = config('services.firecrawl.api_key');
$this->baseUrl = config('services.firecrawl.base_url');
}
public function search(string $query, int $limit = 5): array
{
$response = Http::withToken($this->apiKey)
->post("{$this->baseUrl}/search", [
'query' => $query,
'limit' => $limit,
]);
return $response->json();
}
public function scrape(string $url, array $options = []): array
{
$response = Http::withToken($this->apiKey)
->post("{$this->baseUrl}/scrape", array_merge(['url' => $url], $options));
return $response->json();
}
public function interact(string $url, string $prompt, ?string $followUp = null): array
{
// 1. Scrape to open a browser session
$scrapeResult = $this->scrape($url, ['formats' => ['markdown']]);
$scrapeId = $scrapeResult['data']['metadata']['scrapeId'];
// 2. Send first prompt
Http::withToken($this->apiKey)
->post("{$this->baseUrl}/scrape/{$scrapeId}/interact", [
'prompt' => $prompt,
]);
// 3. Send follow-up prompt
$result = null;
if ($followUp) {
$result = Http::withToken($this->apiKey)
->post("{$this->baseUrl}/scrape/{$scrapeId}/interact", [
'prompt' => $followUp,
])->json();
}
// 4. Close the session
Http::withToken($this->apiKey)
->delete("{$this->baseUrl}/scrape/{$scrapeId}/interact");
return $result ?? $scrapeResult;
}
}
```
## Create a controller
Create `app/Http/Controllers/FirecrawlController.php`:
```php theme={null}
validate(['query' => 'required|string']);
return response()->json(
$this->firecrawl->search($validated['query'], $request->input('limit', 5))
);
}
public function scrape(Request $request)
{
$validated = $request->validate(['url' => 'required|url']);
return response()->json($this->firecrawl->scrape($validated['url']));
}
public function interact(Request $request)
{
$validated = $request->validate([
'url' => 'required|url',
'prompt' => 'required|string',
]);
return response()->json(
$this->firecrawl->interact(
$validated['url'],
$validated['prompt'],
$request->input('followUp')
)
);
}
}
```
## Register routes
In `routes/api.php`:
```php theme={null}
use App\Http\Controllers\FirecrawlController;
Route::post('/search', [FirecrawlController::class, 'search']);
Route::post('/scrape', [FirecrawlController::class, 'scrape']);
Route::post('/interact', [FirecrawlController::class, 'interact']);
```
## Test it
```bash theme={null}
php artisan serve
# Search the web
curl -X POST http://localhost:8000/api/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
# Scrape a page
curl -X POST http://localhost:8000/api/scrape \
-H "Content-Type: application/json" \
-d '{"url": "https://example.com"}'
# Interact with a page
curl -X POST http://localhost:8000/api/interact \
-H "Content-Type: application/json" \
-d '{"url": "https://www.amazon.com", "prompt": "Search for iPhone 16 Pro Max", "followUp": "Click on the first result and tell me the price"}'
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [API Reference](/api-reference/v2-introduction)
>
> Complete REST API documentation
# Mastra
Source: https://docs.firecrawl.dev/quickstarts/mastra
Wire Firecrawl into Mastra tools and agents so they can search, scrape, and interact with live web pages.
## Prerequisites
* Node.js 22.13+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
* An API key from a supported [Mastra model provider](https://mastra.ai/models)
* An existing Mastra project — follow the [Mastra quickstart](https://mastra.ai/guides/getting-started/quickstart) to set one up
## Install the SDK
```bash theme={null}
npm install firecrawl
```
## Set your API key
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Build the Firecrawl tools
Create `src/mastra/tools/firecrawl.ts` to expose search and scrape as Mastra tools:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
import { createTool } from "@mastra/core/tools";
import { z } from "zod";
const firecrawl = new Firecrawl();
export const firecrawlSearch = createTool({
id: "firecrawl-search",
description: "Search the web and return top results.",
inputSchema: z.object({ query: z.string().min(1) }),
outputSchema: z.object({
results: z.array(
z.object({
title: z.string().nullable(),
url: z.string(),
}),
),
}),
execute: async ({ query }) => {
const results = await firecrawl.search(query, { limit: 3 });
return {
results: (results.web ?? []).flatMap((item) =>
"url" in item ? [{ title: item.title ?? null, url: item.url }] : [],
),
};
},
});
export const firecrawlScrape = createTool({
id: "firecrawl-scrape",
description: "Scrape a URL and return markdown content.",
inputSchema: z.object({ url: z.string().url() }),
outputSchema: z.object({ markdown: z.string() }),
execute: async ({ url }) => {
const result = await firecrawl.scrape(url, {
formats: ["markdown"],
onlyMainContent: true,
});
return { markdown: result.markdown ?? "" };
},
});
```
## Create the agent
Create `src/mastra/agents/web-agent.ts` and give it the Firecrawl tools:
```typescript theme={null}
import { Agent } from "@mastra/core/agent";
import { firecrawlSearch, firecrawlScrape } from "../tools/firecrawl";
export const webAgent = new Agent({
id: "web-agent",
name: "Web Agent",
instructions:
"Use Firecrawl tools to search and scrape web pages, then summarize the results.",
model: "openai/gpt-5.4",
tools: { firecrawlSearch, firecrawlScrape },
});
```
## Register the agent
Register the agent on your Mastra instance in `src/mastra/index.ts`:
```typescript theme={null}
import { Mastra } from "@mastra/core";
import { webAgent } from "./agents/web-agent";
export const mastra = new Mastra({
agents: { webAgent },
});
```
## Test in Studio
Run the dev server and open [Mastra Studio](https://mastra.ai/docs/studio/overview) at `http://localhost:4111`:
```bash theme={null}
npm run dev
```
Open the **Web Agent** and try prompts like:
* "Find the latest Firecrawl changelog and summarize the last release."
* "Search for Firecrawl pricing and extract the plan tiers."
## Give the agent a hosted browser
For pages that need clicks, typing, or scrolling, Mastra's [`@mastra/browser-firecrawl`](https://mastra.ai/integrations/browsers/firecrawl) package runs the agent's browser tools in a Firecrawl browser session, so you don't need a local Chromium install.
```bash theme={null}
npm install @mastra/browser-firecrawl agent-browser@0.19.0
```
> [!NOTE]
>
> Pin `agent-browser` to 0.19.0. Later releases ship only the CLI, so `@mastra/browser-firecrawl` fails to import with `Cannot find package .../agent-browser/index.js`.
Create `src/mastra/agents/browser-agent.ts`, then register `browserAgent` on your Mastra instance the same way as `webAgent`:
```typescript theme={null}
import { Agent } from "@mastra/core/agent";
import { FirecrawlBrowser } from "@mastra/browser-firecrawl";
export const browserAgent = new Agent({
id: "browser-agent",
name: "Browser Agent",
instructions:
"Use the browser tools to open pages, click, and type. Take a snapshot after each action to check the result.",
model: "openai/gpt-5.4",
browser: new FirecrawlBrowser({ apiKey: process.env.FIRECRAWL_API_KEY }),
});
```
Each conversation thread gets its own browser session by default. See the [Mastra Firecrawl browser docs](https://mastra.ai/integrations/browsers/firecrawl) for shared sessions, session timeouts, and saved profiles.
## Self-hosted Firecrawl
If you run Firecrawl yourself, add `FIRECRAWL_API_URL` to `.env`. The SDK reads it from the environment, so the tools above need no changes:
```bash theme={null}
FIRECRAWL_API_URL=http://localhost:3002
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Agent docs](/features/agent)
>
> Let an agent drive Firecrawl end to end
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# NestJS
Source: https://docs.firecrawl.dev/quickstarts/nestjs
Use Firecrawl with NestJS to build services that search, scrape, and interact with the web.
## Prerequisites
* NestJS project (`@nestjs/cli`)
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
npm install firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Create a Firecrawl service
Create `src/firecrawl/firecrawl.service.ts`:
```typescript theme={null}
import { Injectable } from "@nestjs/common";
import { Firecrawl } from "firecrawl";
@Injectable()
export class FirecrawlService {
private readonly client: Firecrawl;
constructor() {
this.client = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
}
async search(query: string, limit = 5) {
return this.client.search(query, { limit });
}
async scrape(url: string) {
return this.client.scrape(url);
}
async interact(url: string, prompts: string[]) {
const result = await this.client.scrape(url, { formats: ['markdown'] });
const scrapeId = result.metadata?.scrapeId;
const responses = [];
for (const prompt of prompts) {
const response = await this.client.interact(scrapeId, { prompt });
responses.push(response);
}
await this.client.stopInteraction(scrapeId);
return responses;
}
}
```
## Create a controller
Create `src/firecrawl/firecrawl.controller.ts`:
```typescript theme={null}
import { Body, Controller, Post } from "@nestjs/common";
import { FirecrawlService } from "./firecrawl.service";
@Controller("firecrawl")
export class FirecrawlController {
constructor(private readonly firecrawlService: FirecrawlService) {}
@Post("search")
async search(@Body("query") query: string) {
return this.firecrawlService.search(query);
}
@Post("scrape")
async scrape(@Body("url") url: string) {
return this.firecrawlService.scrape(url);
}
@Post("interact")
async interact(@Body("url") url: string, @Body("prompts") prompts: string[]) {
return this.firecrawlService.interact(url, prompts);
}
}
```
## Register the module
Create `src/firecrawl/firecrawl.module.ts`:
```typescript theme={null}
import { Module } from "@nestjs/common";
import { FirecrawlService } from "./firecrawl.service";
import { FirecrawlController } from "./firecrawl.controller";
@Module({
providers: [FirecrawlService],
controllers: [FirecrawlController],
exports: [FirecrawlService],
})
export class FirecrawlModule {}
```
Import `FirecrawlModule` in your `AppModule`.
## Test it
```bash theme={null}
curl -X POST http://localhost:3000/firecrawl/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Next.js
Source: https://docs.firecrawl.dev/quickstarts/nextjs
Use Firecrawl with Next.js to scrape, search, and interact with web data in your React application.
## Prerequisites
* Next.js 14+ project (App Router)
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
npm install firecrawl
```
## Set your API key
Add your API key to `.env.local`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
The SDK should only run server-side since it requires your API key.
### Route Handler
Create `app/api/search/route.ts`:
```typescript theme={null}
import { NextResponse } from "next/server";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function POST(request: Request) {
const { query } = await request.json();
const results = await firecrawl.search(query, { limit: 5 });
return NextResponse.json(results);
}
```
### Server Action
Create `app/actions.ts` for use from Client Components:
```typescript theme={null}
"use server";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function searchWeb(query: string) {
const results = await firecrawl.search(query, { limit: 5 });
return (results.web || []).map((r) => ({ title: r.title, url: r.url }));
}
```
## Scrape a page
### Route Handler
Create `app/api/scrape/route.ts`:
```typescript theme={null}
import { NextResponse } from "next/server";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function POST(request: Request) {
const { url } = await request.json();
const result = await firecrawl.scrape(url);
return NextResponse.json(result);
}
```
### Server Component
Fetch data directly in a Server Component at `app/page.tsx`:
```tsx theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export default async function Page() {
const result = await firecrawl.scrape("https://example.com");
return (
Scraped Content
{result.markdown}
);
}
```
## Interact with a page
Use interact to control a live browser session — click buttons, fill forms, and extract dynamic content.
### Route Handler
Create `app/api/interact/route.ts`:
```typescript theme={null}
import { NextResponse } from "next/server";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function POST(request: Request) {
const { url, prompts } = await request.json();
const result = await firecrawl.scrape(url, { formats: ['markdown'] });
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, { prompt: 'Search for iPhone 16 Pro Max' });
const response = await firecrawl.interact(scrapeId, { prompt: 'Click on the first result and tell me the price' });
await firecrawl.stopInteraction(scrapeId);
return NextResponse.json({ output: response.output });
}
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Node.js
Source: https://docs.firecrawl.dev/quickstarts/nodejs
Get started with Firecrawl in Node.js. Scrape, search, and interact with web data using the official SDK.
## Prerequisites
* Node.js 22+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
npm install firecrawl
```
## Environment variable
Instead of passing `apiKey` directly, set the `FIRECRAWL_API_KEY` environment variable:
```bash theme={null}
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
```javascript theme={null}
const app = new Firecrawl();
```
## Search the web
```javascript theme={null}
import { Firecrawl } from 'firecrawl';
const app = new Firecrawl({ apiKey: "fc-YOUR-API-KEY" });
const results = await app.search("firecrawl web scraping", { limit: 5 });
for (const result of results.web) {
console.log(result.title, result.url);
}
```
## Scrape a page
```javascript theme={null}
const result = await app.scrape("https://example.com");
console.log(result.markdown);
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "sourceURL": "https://example.com"
> }
> }
> ```
## Interact with a page
Use interact to control a live browser session — click buttons, fill forms, and extract dynamic content.
```javascript theme={null}
const result = await app.scrape('https://www.amazon.com', { formats: ['markdown'] });
const scrapeId = result.metadata?.scrapeId;
await app.interact(scrapeId, { prompt: 'Search for iPhone 16 Pro Max' });
const response = await app.interact(scrapeId, { prompt: 'Click on the first result and tell me the price' });
console.log(response.output);
await app.stopInteraction(scrapeId);
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Nuxt
Source: https://docs.firecrawl.dev/quickstarts/nuxt
Use Firecrawl with Nuxt to scrape, search, and interact with web data in your Vue application.
## Prerequisites
* Nuxt 3+ project
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
npm install firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
Create `server/api/search.post.ts`:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: process.env.FIRECRAWL_API_KEY,
});
export default defineEventHandler(async (event) => {
const { query } = await readBody(event);
const results = await firecrawl.search(query, { limit: 5 });
return results;
});
```
Call it from a Vue component:
```vue theme={null}
```
## Scrape a page
Create `server/api/scrape.post.ts`:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: process.env.FIRECRAWL_API_KEY,
});
export default defineEventHandler(async (event) => {
const { url } = await readBody(event);
const result = await firecrawl.scrape(url);
return result;
});
```
Call it from a Vue component:
```vue theme={null}
{{ data.markdown }}
```
## Interact with a page
Create `server/api/interact.post.ts`:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: process.env.FIRECRAWL_API_KEY,
});
export default defineEventHandler(async (event) => {
const result = await firecrawl.scrape("https://www.amazon.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, {
prompt: "Search for iPhone 16 Pro Max",
});
const response = await firecrawl.interact(scrapeId, {
prompt: "Click on the first result and tell me the price",
});
await firecrawl.stopInteraction(scrapeId);
return { output: response.output };
});
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# PHP
Source: https://docs.firecrawl.dev/quickstarts/php
Get started with Firecrawl in PHP. Scrape, search, and interact with web data using the REST API.
## Prerequisites
* PHP 8.0+ with cURL extension
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Search the web
Firecrawl works with PHP through the REST API using cURL.
```php theme={null}
true,
CURLOPT_POST => true,
CURLOPT_HTTPHEADER => [
'Authorization: Bearer ' . $apiKey,
'Content-Type: application/json',
],
CURLOPT_POSTFIELDS => json_encode([
'query' => 'firecrawl web scraping',
'limit' => 5,
]),
]);
$response = curl_exec($ch);
curl_close($ch);
$results = json_decode($response, true);
foreach ($results['data']['web'] as $result) {
echo $result['title'] . ' - ' . $result['url'] . "\n";
}
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "success": true,
> "data": {
> "web": [
> {
> "url": "https://docs.firecrawl.dev",
> "title": "Firecrawl Documentation",
> "markdown": "# Firecrawl\n\nFirecrawl is the context API for AI agents..."
> }
> ]
> }
> }
> ```
## Scrape a page
```php theme={null}
true,
CURLOPT_POST => true,
CURLOPT_HTTPHEADER => [
'Authorization: Bearer ' . $apiKey,
'Content-Type: application/json',
],
CURLOPT_POSTFIELDS => json_encode([
'url' => 'https://example.com',
]),
]);
$response = curl_exec($ch);
curl_close($ch);
$data = json_decode($response, true);
echo $data['data']['markdown'];
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "success": true,
> "data": {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "sourceURL": "https://example.com"
> }
> }
> }
> ```
## Interact with a page
Start a browser session, interact with the page using natural-language prompts, then close the session.
### Step 1 — Scrape to start a session
```php theme={null}
true,
CURLOPT_POST => true,
CURLOPT_HTTPHEADER => [
'Authorization: Bearer ' . $apiKey,
'Content-Type: application/json',
],
CURLOPT_POSTFIELDS => json_encode([
'url' => 'https://www.amazon.com',
'formats' => ['markdown'],
]),
]);
$response = curl_exec($ch);
curl_close($ch);
$scrapeResult = json_decode($response, true);
$scrapeId = $scrapeResult['data']['metadata']['scrapeId'];
echo "scrapeId: $scrapeId\n";
```
### Step 2 — Send interactions
```php theme={null}
true,
CURLOPT_POST => true,
CURLOPT_HTTPHEADER => $headers,
CURLOPT_POSTFIELDS => json_encode([
'prompt' => 'Search for iPhone 16 Pro Max',
]),
]);
$response = curl_exec($ch);
curl_close($ch);
echo $response . "\n";
// Click on the first result
$ch = curl_init($interactUrl);
curl_setopt_array($ch, [
CURLOPT_RETURNTRANSFER => true,
CURLOPT_POST => true,
CURLOPT_HTTPHEADER => $headers,
CURLOPT_POSTFIELDS => json_encode([
'prompt' => 'Click on the first result and tell me the price',
]),
]);
$response = curl_exec($ch);
curl_close($ch);
echo $response . "\n";
```
### Step 3 — Stop the session
```php theme={null}
true,
CURLOPT_CUSTOMREQUEST => 'DELETE',
CURLOPT_HTTPHEADER => [
'Authorization: Bearer ' . $apiKey,
],
]);
curl_exec($ch);
curl_close($ch);
echo "Session stopped\n";
```
## Reusable helper class
For repeated use, wrap the API in a class:
```php theme={null}
apiKey = $apiKey;
}
private function post(string $endpoint, array $payload): array
{
$ch = curl_init($this->baseUrl . $endpoint);
curl_setopt_array($ch, [
CURLOPT_RETURNTRANSFER => true,
CURLOPT_POST => true,
CURLOPT_HTTPHEADER => [
'Authorization: Bearer ' . $this->apiKey,
'Content-Type: application/json',
],
CURLOPT_POSTFIELDS => json_encode($payload),
]);
$response = curl_exec($ch);
$httpCode = curl_getinfo($ch, CURLINFO_HTTP_CODE);
curl_close($ch);
if ($httpCode >= 400) {
throw new \RuntimeException("Firecrawl API error: HTTP $httpCode");
}
return json_decode($response, true);
}
public function scrape(string $url, array $options = []): array
{
return $this->post('/scrape', array_merge(['url' => $url], $options));
}
public function search(string $query, int $limit = 5): array
{
return $this->post('/search', ['query' => $query, 'limit' => $limit]);
}
}
// Usage
$app = new Firecrawl(getenv('FIRECRAWL_API_KEY'));
$result = $app->scrape('https://example.com');
echo $result['data']['markdown'];
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [API Reference](/api-reference/v2-introduction)
>
> Complete REST API documentation
# Python
Source: https://docs.firecrawl.dev/quickstarts/python
Get started with Firecrawl in Python. Scrape, search, and interact with web data using the official SDK.
## Prerequisites
* Python 3.8+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
pip install firecrawl
```
## Search the web
```python theme={null}
from firecrawl import Firecrawl
app = Firecrawl(api_key="fc-YOUR-API-KEY")
results = app.search("firecrawl web scraping", limit=5)
for result in results.web:
print(result.title, result.url)
```
## Scrape a page
```python theme={null}
result = app.scrape("https://example.com")
print(result.markdown)
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "source_url": "https://example.com"
> }
> }
> ```
## Interact with a page
Use Interact to control a live browser session — click buttons, fill forms, and extract dynamic content.
```python theme={null}
result = app.scrape("https://www.amazon.com", formats=["markdown"])
scrape_id = result.metadata.scrape_id
app.interact(scrape_id, prompt="Search for iPhone 16 Pro Max")
response = app.interact(scrape_id, prompt="Click on the first result and tell me the price")
print(response.output)
app.stop_interaction(scrape_id)
```
## Environment variable
Instead of passing `api_key` directly, set the `FIRECRAWL_API_KEY` environment variable:
```bash theme={null}
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
```python theme={null}
app = Firecrawl()
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Python SDK reference](/sdks/python)
>
> Full SDK reference with crawl, map, async, and more
# Rails
Source: https://docs.firecrawl.dev/quickstarts/rails
Use Firecrawl with Ruby on Rails to search, scrape, and interact with web data using the REST API.
## Prerequisites
* Ruby 3.0+ and Rails 7+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Configuration
Add your API key to your Rails credentials or environment:
```bash theme={null}
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Create a service
Create `app/services/firecrawl_service.rb`:
```ruby theme={null}
require "net/http"
require "json"
require "uri"
class FirecrawlService
BASE_URL = "https://api.firecrawl.dev/v2"
def initialize(api_key: ENV.fetch("FIRECRAWL_API_KEY"))
@api_key = api_key
end
def search(query, limit: 5)
post("/search", { query: query, limit: limit })
end
def scrape(url, **options)
post("/scrape", { url: url }.merge(options))
end
def interact(url, prompt, follow_up: nil)
# 1. Scrape to open a browser session
scrape_result = scrape(url, formats: ["markdown"])
scrape_id = scrape_result.dig("data", "metadata", "scrapeId")
# 2. Send first prompt
post("/scrape/#{scrape_id}/interact", { prompt: prompt })
# 3. Send follow-up prompt
result = nil
if follow_up
result = post("/scrape/#{scrape_id}/interact", { prompt: follow_up })
end
# 4. Close the session
delete("/scrape/#{scrape_id}/interact")
result || scrape_result
end
private
def post(endpoint, payload)
uri = URI("#{BASE_URL}#{endpoint}")
request = Net::HTTP::Post.new(uri)
request["Authorization"] = "Bearer #{@api_key}"
request["Content-Type"] = "application/json"
request.body = payload.to_json
response = Net::HTTP.start(uri.hostname, uri.port, use_ssl: true) do |http|
http.request(request)
end
JSON.parse(response.body)
end
def delete(endpoint)
uri = URI("#{BASE_URL}#{endpoint}")
request = Net::HTTP::Delete.new(uri)
request["Authorization"] = "Bearer #{@api_key}"
Net::HTTP.start(uri.hostname, uri.port, use_ssl: true) do |http|
http.request(request)
end
end
end
```
## Create a controller
Generate a controller:
```bash theme={null}
rails generate controller Firecrawl search scrape interact --skip-routes
```
Edit `app/controllers/firecrawl_controller.rb`:
```ruby theme={null}
class FirecrawlController < ApplicationController
skip_before_action :verify_authenticity_token
def search
service = FirecrawlService.new
result = service.search(params.require(:query), limit: params.fetch(:limit, 5).to_i)
render json: result
end
def scrape
service = FirecrawlService.new
result = service.scrape(params.require(:url))
render json: result
end
def interact
service = FirecrawlService.new
result = service.interact(
params.require(:url),
params.require(:prompt),
follow_up: params[:followUp]
)
render json: result
end
end
```
## Add routes
In `config/routes.rb`:
```ruby theme={null}
Rails.application.routes.draw do
post "api/search", to: "firecrawl#search"
post "api/scrape", to: "firecrawl#scrape"
post "api/interact", to: "firecrawl#interact"
end
```
## Test it
```bash theme={null}
rails server
# Search the web
curl -X POST http://localhost:3000/api/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
# Scrape a page
curl -X POST http://localhost:3000/api/scrape \
-H "Content-Type: application/json" \
-d '{"url": "https://example.com"}'
# Interact with a page
curl -X POST http://localhost:3000/api/interact \
-H "Content-Type: application/json" \
-d '{"url": "https://www.amazon.com", "prompt": "Search for iPhone 16 Pro Max", "followUp": "Click on the first result and tell me the price"}'
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [API Reference](/api-reference/v2-introduction)
>
> Complete REST API documentation
# Remix
Source: https://docs.firecrawl.dev/quickstarts/remix
Use Firecrawl with Remix to scrape, search, and interact with web data in your full-stack React app.
## Prerequisites
* Remix project
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
npm install firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
Use Firecrawl in an `action` to handle form submissions. Create `app/routes/search.tsx`:
```tsx theme={null}
import { json, type ActionFunctionArgs } from "@remix-run/node";
import { Form, useActionData } from "@remix-run/react";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function action({ request }: ActionFunctionArgs) {
const formData = await request.formData();
const query = formData.get("query") as string;
const results = await firecrawl.search(query, { limit: 5 });
return json({ results: (results.web || []).map((r) => ({ title: r.title, url: r.url })) });
}
export default function SearchPage() {
const data = useActionData();
return (
);
}
```
## Scrape a page
Use Firecrawl in a `loader` to fetch data at request time. Create `app/routes/scrape.tsx`:
```tsx theme={null}
import { json, type LoaderFunctionArgs } from "@remix-run/node";
import { useLoaderData } from "@remix-run/react";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function loader({ request }: LoaderFunctionArgs) {
const url = new URL(request.url);
const target = url.searchParams.get("url");
if (!target) return json({ markdown: null });
const result = await firecrawl.scrape(target);
return json({ markdown: result.markdown });
}
export default function ScrapePage() {
const { markdown } = useLoaderData();
return (
Scraped Content
{markdown ?
{markdown}
:
Pass ?url= to scrape a page
}
);
}
```
## Interact with a page
Use interact to control a live browser session — click buttons, fill forms, and extract dynamic content. Create `app/routes/interact.tsx`:
```tsx theme={null}
import { json, type ActionFunctionArgs } from "@remix-run/node";
import { Form, useActionData } from "@remix-run/react";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function action({ request }: ActionFunctionArgs) {
const formData = await request.formData();
const url = formData.get("url") as string;
const result = await firecrawl.scrape(url, { formats: ['markdown'] });
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, { prompt: 'Search for iPhone 16 Pro Max' });
const response = await firecrawl.interact(scrapeId, { prompt: 'Click on the first result and tell me the price' });
await firecrawl.stopInteraction(scrapeId);
return json({ output: response.output });
}
export default function InteractPage() {
const data = useActionData();
return (
{data?.output &&
{data.output}
}
);
}
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Ruby
Source: https://docs.firecrawl.dev/quickstarts/ruby
Get started with Firecrawl in Ruby. Search, scrape, and interact with web data using the REST API.
## Prerequisites
* Ruby 3.0+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Search the web
Firecrawl works with Ruby through the REST API using `net/http`.
```ruby theme={null}
require "net/http"
require "json"
require "uri"
api_key = ENV.fetch("FIRECRAWL_API_KEY")
uri = URI("https://api.firecrawl.dev/v2/search")
request = Net::HTTP::Post.new(uri)
request["Authorization"] = "Bearer #{api_key}"
request["Content-Type"] = "application/json"
request.body = { query: "firecrawl web scraping", limit: 5 }.to_json
response = Net::HTTP.start(uri.hostname, uri.port, use_ssl: true) { |http| http.request(request) }
results = JSON.parse(response.body)
results["data"]["web"].each do |result|
puts "#{result['title']} - #{result['url']}"
end
```
## Scrape a page
```ruby theme={null}
uri = URI("https://api.firecrawl.dev/v2/scrape")
request = Net::HTTP::Post.new(uri)
request["Authorization"] = "Bearer #{api_key}"
request["Content-Type"] = "application/json"
request.body = { url: "https://example.com" }.to_json
response = Net::HTTP.start(uri.hostname, uri.port, use_ssl: true) { |http| http.request(request) }
data = JSON.parse(response.body)
puts data.dig("data", "markdown")
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "success": true,
> "data": {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "sourceURL": "https://example.com"
> }
> }
> }
> ```
## Interact with a page
Scrape a page, then keep working with it using natural language prompts.
```ruby theme={null}
uri = URI("https://api.firecrawl.dev/v2/scrape")
request = Net::HTTP::Post.new(uri)
request["Authorization"] = "Bearer #{api_key}"
request["Content-Type"] = "application/json"
request.body = { url: "https://www.amazon.com", formats: ["markdown"] }.to_json
response = Net::HTTP.start(uri.hostname, uri.port, use_ssl: true) { |http| http.request(request) }
scrape_id = JSON.parse(response.body).dig("data", "metadata", "scrapeId")
interact_uri = URI("https://api.firecrawl.dev/v2/scrape/#{scrape_id}/interact")
interact_req = Net::HTTP::Post.new(interact_uri)
interact_req["Authorization"] = "Bearer #{api_key}"
interact_req["Content-Type"] = "application/json"
interact_req.body = { prompt: "Search for iPhone 16 Pro Max" }.to_json
interact_resp = Net::HTTP.start(interact_uri.hostname, interact_uri.port, use_ssl: true) { |http| http.request(interact_req) }
puts JSON.parse(interact_resp.body)
# Stop the session
delete_uri = URI("https://api.firecrawl.dev/v2/scrape/#{scrape_id}/interact")
delete_req = Net::HTTP::Delete.new(delete_uri)
delete_req["Authorization"] = "Bearer #{api_key}"
Net::HTTP.start(delete_uri.hostname, delete_uri.port, use_ssl: true) { |http| http.request(delete_req) }
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [API Reference](/api-reference/v2-introduction)
>
> Complete REST API documentation
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
# Rust
Source: https://docs.firecrawl.dev/quickstarts/rust
Get started with Firecrawl in Rust. Search, scrape, and interact with web data using the official SDK.
## Prerequisites
* Rust 1.70+ with Cargo
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the crate
Add `firecrawl` to your `Cargo.toml`:
```toml theme={null}
[dependencies]
firecrawl = "2"
tokio = { version = "1", features = ["full"] }
serde_json = "1"
```
## Search the web
```rust theme={null}
use firecrawl::{Client, SearchOptions};
#[tokio::main]
async fn main() -> Result<(), Box> {
let client = Client::new("fc-YOUR-API-KEY")?;
let results = client.search(
"firecrawl web scraping",
SearchOptions { limit: Some(5), ..Default::default() },
).await?;
if let Some(web) = results.data.web {
for item in web {
if let firecrawl::SearchResultOrDocument::WebResult(r) = item {
println!("{} - {}", r.url, r.title.unwrap_or_default());
}
}
}
Ok(())
}
```
## Scrape a page
```rust theme={null}
let doc = client.scrape("https://example.com", None).await?;
println!("{}", doc.markdown.unwrap_or_default());
```
> [accordion] Example response
>
> ```json theme={null}
> {
> "markdown": "# Example Domain\n\nThis domain is for use in illustrative examples...",
> "metadata": {
> "title": "Example Domain",
> "sourceURL": "https://example.com"
> }
> }
> ```
## Interact with a page
Scrape a page to get a `scrapeId`, then use the interact API to control the browser session:
```rust theme={null}
use firecrawl::{Client, ScrapeOptions, Format, ScrapeExecuteOptions};
let doc = client.scrape(
"https://www.amazon.com",
ScrapeOptions {
formats: Some(vec![Format::Markdown]),
..Default::default()
},
).await?;
let scrape_id = doc.metadata
.as_ref()
.and_then(|m| m.scrape_id.as_deref())
.expect("scrapeId not found");
// Send a prompt to interact with the page
let run = client.interact(
scrape_id,
ScrapeExecuteOptions {
prompt: Some("Search for iPhone 16 Pro Max".to_string()),
..Default::default()
},
).await?;
let run = client.interact(
scrape_id,
ScrapeExecuteOptions {
prompt: Some("Click on the first result and tell me the price".to_string()),
..Default::default()
},
).await?;
println!("{:?}", run.output);
// Close the session
client.stop_interaction(scrape_id).await?;
```
## Environment variable
Set `FIRECRAWL_API_KEY` instead of passing the key directly:
```bash theme={null}
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
```rust theme={null}
let api_key = std::env::var("FIRECRAWL_API_KEY")?;
let client = Client::new(api_key)?;
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Rust SDK reference](/sdks/rust)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Spring Boot
Source: https://docs.firecrawl.dev/quickstarts/spring-boot
Use Firecrawl with Spring Boot to search, scrape, and interact with web data using the official Java SDK.
## Prerequisites
* Java 17+ and Spring Boot 3+
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Add the dependency
> [tab] Gradle (Kotlin DSL)
>
> ```kotlin theme={null}
> dependencies {
> implementation("com.firecrawl:firecrawl-java:1.18.7")
> }
> ```
> [tab] Maven
>
> ```xml theme={null}
>
> com.firecrawl
> firecrawl-java
> 1.18.7
>
> ```
## Configuration
Add your API key to `application.properties`:
```properties theme={null}
firecrawl.api-key=${FIRECRAWL_API_KEY}
```
Or set it as an environment variable:
```bash theme={null}
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Create a configuration bean
Create `FirecrawlConfig.java`:
```java theme={null}
import com.firecrawl.client.FirecrawlClient;
import org.springframework.beans.factory.annotation.Value;
import org.springframework.context.annotation.Bean;
import org.springframework.context.annotation.Configuration;
@Configuration
public class FirecrawlConfig {
@Bean
public FirecrawlClient firecrawlClient(
@Value("${firecrawl.api-key}") String apiKey) {
return FirecrawlClient.builder()
.apiKey(apiKey)
.build();
}
}
```
## Create a REST controller
Create `FirecrawlController.java`:
```java theme={null}
import com.firecrawl.client.FirecrawlClient;
import com.firecrawl.models.Document;
import com.firecrawl.models.SearchData;
import com.firecrawl.models.SearchOptions;
import com.firecrawl.models.ScrapeOptions;
import com.firecrawl.models.BrowserExecuteResponse;
import org.springframework.web.bind.annotation.*;
import java.util.List;
import java.util.Map;
@RestController
@RequestMapping("/api")
public class FirecrawlController {
private final FirecrawlClient firecrawl;
public FirecrawlController(FirecrawlClient firecrawl) {
this.firecrawl = firecrawl;
}
@PostMapping("/search")
public SearchData search(@RequestBody Map body) {
return firecrawl.search(
(String) body.get("query"),
SearchOptions.builder()
.limit((int) body.getOrDefault("limit", 5))
.build()
);
}
@PostMapping("/scrape")
public Map scrape(@RequestBody Map body) {
Document doc = firecrawl.scrape(body.get("url"));
return Map.of(
"markdown", doc.getMarkdown(),
"metadata", doc.getMetadata()
);
}
@PostMapping("/interact")
public Map interact(@RequestBody Map body) {
Document doc = firecrawl.scrape(body.get("url"),
ScrapeOptions.builder().formats(List.of((Object) "markdown")).build());
String scrapeId = (String) doc.getMetadata().get("scrapeId");
BrowserExecuteResponse response = firecrawl.interact(scrapeId,
body.getOrDefault("code", "const title = await page.title(); console.log(title);"));
firecrawl.stopInteractiveBrowser(scrapeId);
return Map.of("result", response.getStdout());
}
}
```
## Run it
```bash theme={null}
./gradlew bootRun
```
## Test it
```bash theme={null}
# Search the web
curl -X POST http://localhost:8080/api/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
# Scrape a page
curl -X POST http://localhost:8080/api/scrape \
-H "Content-Type: application/json" \
-d '{"url": "https://example.com"}'
# Interact with a page
curl -X POST http://localhost:8080/api/interact \
-H "Content-Type: application/json" \
-d '{"url": "https://www.amazon.com", "code": "const title = await page.title(); console.log(title);"}'
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Java SDK reference](/sdks/java)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Supabase Edge Functions
Source: https://docs.firecrawl.dev/quickstarts/supabase-edge-functions
Use Firecrawl with Supabase Edge Functions to search, scrape, and interact with web data at the edge.
## Prerequisites
* Supabase project with CLI (`supabase init`)
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
supabase functions new firecrawl-search
supabase functions new firecrawl-scrape
supabase functions new firecrawl-interact
```
Set the secret:
```bash theme={null}
supabase secrets set FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
Edit `supabase/functions/firecrawl-search/index.ts`:
```typescript theme={null}
import Firecrawl from "npm:firecrawl";
const firecrawl = new Firecrawl({
apiKey: Deno.env.get("FIRECRAWL_API_KEY"),
});
Deno.serve(async (req) => {
const { query } = await req.json();
const results = await firecrawl.search(query, { limit: 5 });
return new Response(JSON.stringify(results), {
headers: { "Content-Type": "application/json" },
});
});
```
## Scrape a page
Edit `supabase/functions/firecrawl-scrape/index.ts`:
```typescript theme={null}
import Firecrawl from "npm:firecrawl";
const firecrawl = new Firecrawl({
apiKey: Deno.env.get("FIRECRAWL_API_KEY"),
});
Deno.serve(async (req) => {
const { url } = await req.json();
const result = await firecrawl.scrape(url);
return new Response(JSON.stringify(result), {
headers: { "Content-Type": "application/json" },
});
});
```
## Interact with a page
Edit `supabase/functions/firecrawl-interact/index.ts`:
```typescript theme={null}
import Firecrawl from "npm:firecrawl";
const firecrawl = new Firecrawl({
apiKey: Deno.env.get("FIRECRAWL_API_KEY"),
});
Deno.serve(async (_req) => {
const result = await firecrawl.scrape("https://www.amazon.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, {
prompt: "Search for iPhone 16 Pro Max",
});
const response = await firecrawl.interact(scrapeId, {
prompt: "Click on the first result and tell me the price",
});
console.log(response.output);
await firecrawl.stopInteraction(scrapeId);
return new Response(JSON.stringify({ output: response.output }), {
headers: { "Content-Type": "application/json" },
});
});
```
## Deploy
```bash theme={null}
supabase functions deploy firecrawl-search
supabase functions deploy firecrawl-scrape
supabase functions deploy firecrawl-interact
```
## Test it
```bash theme={null}
curl -X POST https://.supabase.co/functions/v1/firecrawl-search \
-H "Authorization: Bearer " \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
```
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# SvelteKit
Source: https://docs.firecrawl.dev/quickstarts/sveltekit
Use Firecrawl with SvelteKit to scrape, search, and interact with web data in your Svelte application.
## Prerequisites
* SvelteKit project
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Install the SDK
```bash theme={null}
npm install firecrawl
```
Add your API key to `.env`:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
Create a form action in `src/routes/search/+page.server.ts`:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
import { FIRECRAWL_API_KEY } from "$env/static/private";
const firecrawl = new Firecrawl({ apiKey: FIRECRAWL_API_KEY });
export const actions = {
default: async ({ request }) => {
const data = await request.formData();
const query = data.get("query") as string;
const results = await firecrawl.search(query, { limit: 5 });
return { results: (results.web || []).map((r) => ({ title: r.title, url: r.url })) };
},
};
```
Wire it up in `src/routes/search/+page.svelte`:
```svelte theme={null}
{#if form?.results}
{#each form.results as result}
{/each}
{/if}
```
## Scrape a page
Fetch data in a load function at `src/routes/scrape/+page.server.ts`:
```typescript theme={null}
import { Firecrawl } from "firecrawl";
import { FIRECRAWL_API_KEY } from "$env/static/private";
const firecrawl = new Firecrawl({ apiKey: FIRECRAWL_API_KEY });
export async function load({ url }) {
const target = url.searchParams.get("url");
if (!target) return { markdown: null };
const result = await firecrawl.scrape(target);
return { markdown: result.markdown };
}
```
Display it in `src/routes/scrape/+page.svelte`:
```svelte theme={null}
{#if data.markdown}
{data.markdown}
{:else}
Pass ?url= to scrape a page
{/if}
```
## Interact with a page
Create a server endpoint at `src/routes/api/interact/+server.ts`:
```typescript theme={null}
import { json } from "@sveltejs/kit";
import { Firecrawl } from "firecrawl";
import { FIRECRAWL_API_KEY } from "$env/static/private";
const firecrawl = new Firecrawl({ apiKey: FIRECRAWL_API_KEY });
export async function POST() {
const result = await firecrawl.scrape("https://www.amazon.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, {
prompt: "Search for iPhone 16 Pro Max",
});
const response = await firecrawl.interact(scrapeId, {
prompt: "Click on the first result and tell me the price",
});
await firecrawl.stopInteraction(scrapeId);
return json({ output: response.output });
}
```
## Next steps
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Vercel Functions
Source: https://docs.firecrawl.dev/quickstarts/vercel-functions
Use Firecrawl with Vercel Functions to search, scrape, and interact with web data in serverless deployments.
## Prerequisites
* Vercel project (Next.js, SvelteKit, Nuxt, or standalone)
* A Firecrawl API key — [get one free](https://www.firecrawl.dev/app/api-keys)
## Setup
```bash theme={null}
npm install firecrawl
```
Add `FIRECRAWL_API_KEY` as an environment variable in your Vercel project settings, or in `.env.local` for local development:
```bash theme={null}
FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
## Search the web
Create `api/search.ts` (or `app/api/search/route.ts` for Next.js):
```typescript theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function POST(request: Request) {
const { query } = await request.json();
const results = await firecrawl.search(query, { limit: 5 });
return new Response(JSON.stringify(results), {
headers: { "Content-Type": "application/json" },
});
}
```
## Scrape a page
Create `api/scrape.ts` (or `app/api/scrape/route.ts` for Next.js):
```typescript theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function POST(request: Request) {
const { url } = await request.json();
const result = await firecrawl.scrape(url);
return new Response(JSON.stringify(result), {
headers: { "Content-Type": "application/json" },
});
}
```
## Interact with a page
Create `api/interact.ts` (or `app/api/interact/route.ts` for Next.js):
```typescript theme={null}
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({ apiKey: process.env.FIRECRAWL_API_KEY });
export async function POST(request: Request) {
const result = await firecrawl.scrape("https://www.amazon.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
await firecrawl.interact(scrapeId, {
prompt: "Search for iPhone 16 Pro Max",
});
const response = await firecrawl.interact(scrapeId, {
prompt: "Click on the first result and tell me the price",
});
await firecrawl.stopInteraction(scrapeId);
return new Response(JSON.stringify({ output: response.output }), {
headers: { "Content-Type": "application/json" },
});
}
```
## Deploy
```bash theme={null}
vercel deploy
```
## Test it
```bash theme={null}
curl -X POST https://your-project.vercel.app/api/search \
-H "Content-Type: application/json" \
-d '{"query": "firecrawl web scraping"}'
```
> [!NOTE]
>
> Vercel Functions have a default timeout of 10 seconds on the Hobby plan and 60 seconds on Pro. For large crawl jobs, use the Firecrawl async API with webhooks instead.
## Next steps
> [card] [Search docs](/features/search)
>
> Search the web and get full page content
> [card] [Scrape docs](/features/scrape)
>
> All scrape options including formats, actions, and proxies
> [card] [Interact docs](/features/interact)
>
> Click, fill forms, and extract dynamic content
> [card] [Node SDK reference](/sdks/node)
>
> Full SDK reference with crawl, map, batch scrape, and more
# Vercel Marketplace
Source: https://docs.firecrawl.dev/quickstarts/vercel-marketplace
Install Firecrawl from the Vercel Marketplace, attach it to a project, and use the injected FIRECRAWL_API_KEY in your Vercel app.
Firecrawl, the context API for AI agents, is available as a native [Vercel Marketplace integration](https://vercel.com/marketplace/firecrawl). Installing it provisions Firecrawl for your Vercel project and adds `FIRECRAWL_API_KEY` to the project's environment variables automatically.
Use this guide to search, scrape, and interact with the web from Vercel, with billing and setup handled through Vercel.
## What the integration does
When you install Firecrawl from the Vercel Marketplace, Vercel connects Firecrawl to a selected project and makes the API key available as an environment variable.
* Provisions a Firecrawl account and API key through the Marketplace flow
* Adds `FIRECRAWL_API_KEY` to your Vercel project environment
* Keeps Firecrawl billing on your Vercel invoice
* Lets you open Firecrawl from Vercel after the integration is connected
> [!NOTE]
>
> If you already have a Firecrawl API key and want to configure Vercel manually, use the [Vercel Functions quickstart](/quickstarts/vercel-functions) instead.
## Install from Vercel
1. Open the [Firecrawl listing on the Vercel Marketplace](https://vercel.com/marketplace/firecrawl).
2. Click **Install**.
3. Choose the Firecrawl plan you want to use.
4. Select the Vercel project that should receive the environment variable.
5. Finish the installation flow.
After installation, redeploy your project so Vercel Functions and framework server code can read the new environment variable.
## Install the SDK
In your Vercel project, install the Firecrawl Node SDK:
```bash theme={null}
npm install firecrawl
```
You do not need to paste an API key into your code. Read `process.env.FIRECRAWL_API_KEY` server-side.
## Scrape a page
Create a route handler at `app/api/scrape/route.ts`:
```typescript theme={null}
import { NextResponse } from "next/server";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: process.env.FIRECRAWL_API_KEY,
});
export async function POST(request: Request) {
const { url } = await request.json();
const result = await firecrawl.scrape(url, {
formats: ["markdown"],
});
return NextResponse.json(result);
}
```
Test the route after deployment:
```bash theme={null}
curl -X POST https://your-project.vercel.app/api/scrape \
-H "Content-Type: application/json" \
-d '{"url": "https://www.firecrawl.dev"}'
```
## Search the web
Use `search` when your app needs current web results plus page content:
```typescript theme={null}
import { NextResponse } from "next/server";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: process.env.FIRECRAWL_API_KEY,
});
export async function POST(request: Request) {
const { query } = await request.json();
const results = await firecrawl.search(query, {
limit: 5,
scrapeOptions: {
formats: ["markdown"],
},
});
return NextResponse.json(results);
}
```
## Interact with dynamic pages
Use `interact` when your app needs to click, scroll, or fill forms before extracting content.
```typescript theme={null}
import { NextResponse } from "next/server";
import { Firecrawl } from "firecrawl";
const firecrawl = new Firecrawl({
apiKey: process.env.FIRECRAWL_API_KEY,
});
export async function POST() {
const result = await firecrawl.scrape("https://news.ycombinator.com", {
formats: ["markdown"],
});
const scrapeId = result.metadata?.scrapeId;
if (!scrapeId) {
return NextResponse.json(
{ error: "No interactive scrape session was created" },
{ status: 500 }
);
}
const response = await firecrawl.interact(scrapeId, {
prompt: "Open the first story and summarize the page.",
});
await firecrawl.stopInteraction(scrapeId);
return NextResponse.json({ output: response.output });
}
```
> [!NOTE]
>
> Longer interactions can exceed short serverless timeouts. For production workflows that may take longer, run the work in a background job or use Firecrawl's async APIs with webhooks.
## Use Firecrawl with the Vercel AI SDK
If you are building an agent with the [Vercel AI SDK](/developer-guides/llm-sdks-and-frameworks/vercel-ai-sdk), install the Firecrawl AI SDK tools:
```bash theme={null}
npm install firecrawl-aisdk ai
```
Then pass Firecrawl tools to your model. The Marketplace-installed `FIRECRAWL_API_KEY` is read from the environment.
> [!NOTE]
>
> The example below uses the Vercel AI Gateway model string format. Configure your AI SDK model provider or AI Gateway credentials separately.
```typescript theme={null}
import { generateText, stepCountIs } from "ai";
import { FirecrawlTools } from "firecrawl-aisdk";
const { systemPrompt, ...tools } = FirecrawlTools();
const { text } = await generateText({
model: "anthropic/claude-sonnet-5.5",
system: systemPrompt,
tools,
stopWhen: stepCountIs(20),
prompt: "Search for recent Vercel AI SDK examples, scrape the best sources, and summarize them.",
});
console.log(text);
```
## Next steps
> [card] [Vercel Functions quickstart](/quickstarts/vercel-functions)
>
> Use Firecrawl in Vercel Functions with manual environment setup
> [card] [Vercel AI SDK guide](/developer-guides/llm-sdks-and-frameworks/vercel-ai-sdk)
>
> Add Firecrawl tools to Vercel AI SDK agents
> [card] [Scrape docs](/features/scrape)
>
> Convert webpages into Markdown, JSON, screenshots, and more
> [card] [Search docs](/features/search)
>
> Search the web and get page content from results
# Rate Limits
Source: https://docs.firecrawl.dev/rate-limits
Rate limits for different pricing plans and API requests
Rate limits cap how many requests your team can make per minute, while concurrency limits cap how many jobs can run in parallel. Both are set by your plan; exceeding either returns a `429` response. See [Errors](/api-reference/errors) for the full error catalog and a retry-with-backoff snippet.
## Concurrent Browser Limits
Concurrent browsers control how many pages Firecrawl can process for you in parallel. Your plan sets the ceiling; any jobs beyond it wait in a queue until a browser frees up.
Time spent in the queue counts against the request's [`timeout`](/advanced-scraping-guide#timing-and-cache) parameter, so you can set a lower timeout to fail fast instead of waiting. To see current availability before sending work, call the [Queue Status](/api-reference/endpoint/queue-status) endpoint. Jobs that are waiting in your concurrency queue will time out after a maximum of 48 hours.
### Current Plans
Plan
Concurrent Browsers
Max Queued Jobs
Free
2
50,000
Hobby
5
50,000
Standard
25
50,000
Growth
50
100,000
Scale / Enterprise
100+
200,000+
Each team has a maximum number of jobs that can be waiting in the concurrency queue. If you exceed this limit, new jobs will be rejected with a `429` status code until existing jobs complete. For larger plans with custom concurrency limits, the max queued jobs is 2,000 times your concurrency limit, capped at 2,000,000.
If you require higher concurrency limits, [contact us about enterprise plans](https://firecrawl.dev/enterprise).
## API Rate Limits
Rate limits are measured in requests per minute and are primarily in place to prevent abuse. When configured correctly, your real bottleneck will be concurrent browsers. Rate limits are applied per team, so all API keys on the same team share the same rate limit counters.
### Keyless (no API key)
The hosted Firecrawl MCP keyless endpoint exposes exactly **Search, Scrape, and Parse** without an API key. Other hosted MCP tools require an account connection or an API key.
For official Firecrawl clients, the CLI, SDKs, and REST API, keyless access also includes **Interact**. On Firecrawl Cloud, research, developer, and government search endpoints can also be used without an API key. No other endpoints (crawl, extract, map, batch scrape, etc.) are available without a key.
Keyless usage is free and capped per IP address per day by **two limits**, and exceeding either returns a `429`:
* A maximum number of **requests** per day.
* A maximum number of **credits** per day. Operations cost different amounts of credits (for example, Interact and JSON extraction cost more than a basic scrape), so heavier usage reaches the credit cap sooner.
[Sign up for a free API key](https://firecrawl.dev) to get 1,000 credits and higher rate limits at no cost — official clients automatically use your key once it's configured.
### Current Plans
Plan
/scrape
/map
/crawl
/search
/agent
/crawl/status
/agent/status
Free
10
10
2
10
2
500
500
Hobby
100
100
20
100
20
5000
5000
Standard
500
500
100
500
100
25000
25000
Growth
5000
5000
1000
5000
1000
250000
250000
Scale
10000
10000
2000
10000
2000
500000
500000
These rate limits are enforced to ensure fair usage and availability of the API for all users. If you require higher limits, please contact us at [help@firecrawl.com](mailto:help@firecrawl.com) to discuss custom plans.
### Extract Endpoints
The extract endpoints share limits with the corresponding /agent rate limits.
### Batch Scrape Endpoints
The batch scrape endpoints share limits with the corresponding /crawl rate limits.
### Government and Research Indexes
Calls to the [Government Index](/features/gov) and the [Research Index](/features/research) are free. Each index has a per-minute limit per team that is the same on every plan:
| Index | Calls per minute |
| - | - |
| Government Index | 300 |
| Research Index | 100 |
Each index also has a daily call limit per team:
Plan
Calls per index per day
Free / Hobby / Standard
1,000
Growth
2,000
Scale / Enterprise
Unlimited
Requests without an API key get the Free limit, counted per IP address. Counts reset at 00:00 UTC. After you upgrade, the new limit applies within about 10 minutes.
#### What counts
Each index has its own counts. Every call to that index counts once toward both its per-minute and its daily limit, whichever way you reach it:
* **Government Index:** `/search/gov`, `/search` with the `gov` category, and the Government Index tool in [Alexandria](/features/alexandria).
* **Research Index:** every `/search/research/papers` endpoint (search, inspect, read and related papers), `/search/research/proteins`, and the Research Index tool in Alexandria.
A `gov` search on `/search` also counts toward your plan's `/search` rate limit.
An Alexandria request that carries several calls to an index counts each one. If the request would go over either limit, none of its calls run. The request also counts toward the rate limit of the endpoint it is sent to.
A request Firecrawl rejects as invalid (`400`) before it reaches the index is not counted toward the daily limit, and an Alexandria request replayed with the same `x-request-id` is not counted toward either limit. The replay returns the saved result, except under zero data retention: no result is kept, so the replay returns `409` with code `response_not_retained`. A call that reaches the index counts even if the index returns an error.
#### When you reach the limit
Over the per-minute limit, the request returns `429` with a `Retry-After` header giving the seconds until the minute's count resets. The per-minute limits are the same on every plan, so upgrading does not raise them. Over the daily limit, it returns `429` with a `Retry-After` header giving the seconds until 00:00 UTC. Until then, calls to that index are refused unless they fit in what is left of the daily limit or you upgrade. The daily-limit body explains the limit and how to raise it:
```json theme={null}
{
"success": false,
"code": "INDEX_DAILY_LIMIT",
"error": "Daily Research Index limit reached: your team has used 1,000 of its 1,000 calls today. The limit resets at 00:00 UTC, in 3h 12m. Upgrade to Scale or Enterprise for unlimited Research Index calls: https://firecrawl.dev/pricing",
"limit": 1000,
"used": 1000,
"resetsAt": "2026-10-16T00:00:00.000Z",
"upgradeUrl": "https://firecrawl.dev/pricing"
}
```
| Field | Meaning |
| - | - |
| `code` | `INDEX_DAILY_LIMIT` from the search endpoints, `index_daily_limit` from Alexandria. A per-minute rate limit `429` has no `code`, except when an Alexandria request goes over an index's per-minute limit, which returns `index_rate_limit`. Use this field to tell them apart. |
| `limit` | Your plan's daily limit for this index. |
| `used` | Calls already counted today. |
| `resetsAt` | When the count resets, in UTC. |
| `upgradeUrl` | Where to change your plan. |
Alexandria's `index_rate_limit` and `index_daily_limit` responses also include `retryAfterSeconds`, the same value as the `Retry-After` header. A `429` from the rate limit of the endpoint an Alexandria request is sent to has no `code`; honor its `Retry-After` header.
### Browser Sandbox
The browser sandbox endpoints have per-plan rate limits that scale with your subscription:
Plan
/interact
/interact/\{id}/execute
Free
2
10
Hobby
20
100
Standard
100
500
Growth
1,000
5,000
Scale
1,500
7,500
In addition, each team's plan determines how many browser sessions can be active simultaneously (see Concurrent Browser Limits above). If you exceed this limit, new session requests will return a `429` status code until existing sessions are destroyed.
# CLI
Source: https://docs.firecrawl.dev/sdks/cli
Firecrawl skills are an easy way for AI agents such as Codex, Claude Code, Cursor, and OpenCode to use Firecrawl through the CLI.
Search, scrape, parse, crawl, map, interact, run agent jobs, and monitor changes directly from the terminal. The Firecrawl CLI is the context API for AI agents on the command line: it works standalone, or with skills that AI coding agents like Codex, Claude Code, Cursor, Hermes Agent, and OpenCode can discover and use automatically.
## Installation
If you are using an AI agent like Codex, Claude Code, Cursor, or OpenCode, you can install the Firecrawl skills below and the agent will set them up for you.
```bash theme={null}
npx -y firecrawl-cli@latest init --all --browser
```
* `--all` skips agent selection and initializes every detected agent
* `--browser` opens the browser for Firecrawl authentication automatically
> [!NOTE]
>
> After installing the skills, restart your agent for it to discover them.
You can also manually install the Firecrawl CLI globally using npm:
```bash CLI theme={null}
# Install globally with npm
npm install -g firecrawl-cli
```
## Authentication
Before using the CLI, you need to authenticate with your Firecrawl API key.
> [!NOTE]
>
> **Some CLI commands work without logging in.** With no API key configured, supported commands fall back to the keyless free tier — free, but rate-limited per IP. See [Rate Limits](/rate-limits#keyless-no-api-key) for the current keyless command list and caveats. [Sign up for a free key](https://firecrawl.dev) for 1,000 credits and higher limits; the CLI uses it automatically once configured.
### Login
```bash CLI theme={null}
# Interactive login (opens browser or prompts for API key)
firecrawl login
# Login with browser authentication (recommended for agents)
firecrawl login --browser
# Login with API key directly
firecrawl login --api-key fc-YOUR-API-KEY
# Or set via environment variable
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
### View Configuration
```bash CLI theme={null}
# View current configuration and authentication status
firecrawl view-config
```
### Logout
```bash CLI theme={null}
# Clear stored credentials
firecrawl logout
```
### Connect the CLI to self-hosted Firecrawl
First, get one scrape working with the [self-hosting guide](/contributing/self-host). Then point the CLI at that API with `--api-url` or `FIRECRAWL_API_URL`:
```bash CLI theme={null}
# Use a local Firecrawl instance (no API key required)
firecrawl --api-url http://localhost:3002 scrape https://example.com
# Or set via environment variable
export FIRECRAWL_API_URL=http://localhost:3002
firecrawl scrape https://example.com
# Configure and persist the custom API URL
firecrawl config --api-url http://localhost:3002
```
When you use a custom API URL instead of `https://api.firecrawl.dev`, the CLI skips Firecrawl Cloud API-key authentication. That matches the trusted-network quickstart, where `USE_DB_AUTHENTICATION=false`.
> [!WARNING]
>
> Keep an unauthenticated API on a trusted network. If you add an authentication
> proxy or another access-control layer, verify that the CLI can send the
> credentials that layer requires before depending on this path.
The CLI can call only the capabilities enabled in your deployment. Check [self-hosted feature support](/contributing/self-host#self-hosted-feature-support) before using Cloud-only or provider-dependent commands.
### Check Status
Verify installation, authentication, and view rate limits:
```bash CLI theme={null}
firecrawl --status
```
Output when ready:
```
🔥 firecrawl cli v1.16.2
● Authenticated via FIRECRAWL_API_KEY
Concurrency: 0/100 jobs (parallel scrape limit)
Credits: 500,000 remaining
```
* **Concurrency**: Maximum parallel jobs. Run parallel operations close to this limit but not above.
* **Credits**: Remaining API credits. Each scrape/crawl consumes credits.
## Commands
> [!NOTE]
>
> The hidden `firecrawl browser` command is deprecated for agent workflows. Use `firecrawl scrape ` first, then `firecrawl interact ...` with the resulting scrape session.
### Scrape
Scrape a single URL and extract its content in various formats.
> [!TIP]
>
> Use `--only-main-content` to get clean output without navigation, footers, and
> ads. This is recommended for most use cases where you want just the article or
> main page content.
```bash CLI theme={null}
# Scrape a URL (default: markdown output)
firecrawl https://example.com
# Or use the explicit scrape command
firecrawl scrape https://example.com
# Recommended: use --only-main-content for clean output without nav/footer
firecrawl https://example.com --only-main-content
```
#### Output Formats
```bash CLI theme={null}
# Get HTML output
firecrawl https://example.com --html
# Multiple formats (returns JSON)
firecrawl https://example.com --format markdown,links
# Get images from a page
firecrawl https://example.com --format images
# Get a summary of the page content
firecrawl https://example.com --format summary
# Track changes on a page
firecrawl https://example.com --format changeTracking
# Available formats: markdown, html, rawHtml, links, screenshot, json, images, summary, changeTracking, attributes, branding, product
```
#### Scrape Options
```bash CLI theme={null}
# Extract only main content (removes navs, footers)
firecrawl https://example.com --only-main-content
# Wait for JavaScript rendering
firecrawl https://example.com --wait-for 3000
# Take a screenshot
firecrawl https://example.com --screenshot
# Extract structured JSON with a schema
firecrawl https://example.com --format json --schema '{"type":"object","properties":{"title":{"type":"string"}}}'
# Run lightweight scrape actions before extraction
firecrawl https://example.com --actions '[{"type":"wait","milliseconds":1000}]'
# Select proxy mode
firecrawl https://example.com --proxy basic
# Redact personally identifiable information
firecrawl https://example.com --redact-pii
# Include/exclude specific HTML tags
firecrawl https://example.com --include-tags article,main
firecrawl https://example.com --exclude-tags nav,footer
# Save output to file
firecrawl https://example.com -o output.md
# Pretty print JSON output
firecrawl https://example.com --format markdown,links --pretty
# Force JSON output even with single format
firecrawl https://example.com --json
# Show request timing information
firecrawl https://example.com --timing
```
**Available Options:**
| Option | Short | Description |
| - | - | - |
| `--url ` | `-u` | URL to scrape (alternative to positional argument) |
| `--format ` | `-f` | Output formats (comma-separated): `markdown`, `html`, `rawHtml`, `links`, `screenshot`, `json`, `images`, `summary`, `changeTracking`, `attributes`, `branding` |
| `--html` | `-H` | Shortcut for `--format html` |
| `--only-main-content` | | Extract only main content |
| `--wait-for ` | | Wait time in milliseconds for JS rendering |
| `--screenshot` | | Take a screenshot |
| `--full-page-screenshot` | | Take a full page screenshot |
| `--include-tags ` | | HTML tags to include (comma-separated) |
| `--exclude-tags ` | | HTML tags to exclude (comma-separated) |
| `--schema ` | | JSON schema for structured extraction |
| `--schema-file ` | | Path to JSON schema file |
| `--actions ` | | JSON actions array to run during scrape |
| `--actions-file ` | | Path to JSON actions file |
| `--proxy ` | | Proxy mode for scraping (for example, `auto` or `basic`) |
| `--redact-pii` | | Redact personally identifiable information from returned content |
| `--output ` | `-o` | Save output to file |
| `--json` | | Force JSON output even with single format |
| `--pretty` | | Pretty print JSON output |
| `--timing` | | Show request timing and other useful information |
| `--alexandria ` | | Run an [Alexandria](/features/alexandria) tool, given as `provider/capability`, instead of scraping a URL. Repeat to run more than one tool |
| `--options ` | | JSON input for each Alexandria tool, in the same order |
| `--request-id ` | | Request ID for an Alexandria run. Use the same ID to recover the same run |
| `--domain-tools` | | Also return Alexandria tools that match the scraped URL. The tools do not run |
***
### Search
Search the web and optionally scrape the results.
```bash CLI theme={null}
# Search the web
firecrawl search "web scraping tutorials"
# Limit results
firecrawl search "AI news" --limit 10
# Pretty print results
firecrawl search "machine learning" --pretty
```
#### Search Options
```bash CLI theme={null}
# Search specific sources
firecrawl search "AI" --sources web,news,images
# Search with category filters
firecrawl search "react hooks" --categories developer
firecrawl search "machine learning" --categories research,pdf
# Time-based filtering
firecrawl search "tech news" --tbs qdr:h # Last hour
firecrawl search "tech news" --tbs qdr:d # Last day
firecrawl search "tech news" --tbs qdr:w # Last week
firecrawl search "tech news" --tbs qdr:m # Last month
firecrawl search "tech news" --tbs qdr:y # Last year
# Location-based search
firecrawl search "restaurants" --location "Berlin,Germany" --country DE
# Search and scrape results
firecrawl search "documentation" --scrape --scrape-formats markdown
# Save to file
firecrawl search "firecrawl" --pretty -o results.json
```
**Available Options:**
| Option | Description |
| - | - |
| `--limit ` | Maximum results (default: 5, max: 100) |
| `--sources ` | Sources to search: `web`, `images`, `news`, `alexandria` (comma-separated, default: `web,alexandria`). Use `web` to omit Alexandria tools |
| `--domain-tools` | Include Alexandria tools for the domains in web results (on by default with `alexandria`) |
| `--no-domain-tools` | Turn off domain matching for Alexandria tools |
| `--tool-detail ` | Alexandria tool detail: `compact` (default), `summary`, or `full` (includes contracts) |
| `--categories ` | Filter by category: `research`, `pdf`, `developer`, `gov` (comma-separated) |
| `--tbs ` | Time filter: `qdr:h` (hour), `qdr:d` (day), `qdr:w` (week), `qdr:m` (month), `qdr:y` (year) |
| `--location ` | Geo-targeting (e.g., "Berlin,Germany") |
| `--country ` | ISO country code (default: US) |
| `--timeout ` | Timeout in milliseconds (default: 60000) |
| `--ignore-invalid-urls` | Exclude URLs invalid for other Firecrawl endpoints |
| `--scrape` | Scrape search results |
| `--scrape-formats ` | Formats for scraped content (default: markdown) |
| `--only-main-content` | Include only main content when scraping (default: true) |
| `--json` | Output as JSON |
| `--output ` | Save output to file |
| `--pretty` | Pretty print JSON output |
***
### Alexandria
Find and run data tools from [Alexandria](/features/alexandria), the Firecrawl catalogue of third-party data providers. Discovery is free. A tool run costs the price listed on the tool.
```bash CLI theme={null}
# Find tools for a task (tools only, no web results)
firecrawl search alexandria "podcast conversations about AI agents"
# Browse categories, then providers and their tools
firecrawl alexandria list
firecrawl list particle
# Read the inputs and response of one tool
firecrawl find-tools --options '{"providers":["particle"],"capabilities":["podcasts/episodes/search"],"level":"tools","expand":["options","response"]}' --json
# Run the tool
firecrawl scrape particle/podcasts/episodes/search --options '{"semantic_search":"AI agents","limit":2}'
```
`firecrawl scrape provider/capability` is a short form of `firecrawl scrape --alexandria provider/capability`. Tool addresses go directly to Alexandria. They never fall back to a URL scrape.
#### Provider terms
When a provider returns `THIRD_PARTY_DATA_TERMS_REQUIRED`, read its terms first:
```bash CLI theme={null}
firecrawl alexandria terms show particle --pretty
```
An org admin accepts terms at the link in the error or at [Data sources settings](https://www.firecrawl.dev/app/settings?tab=data-sources). The CLI cannot accept terms. After acceptance, run the original command again.
Use `firecrawl alexandria feedback` to report issues or request capabilities, within 20 minutes of your last Alexandria search, discovery, or execution. Each submission refunds 1 credit, up to 10 credits per website and 100 credits per team each UTC day. Run `firecrawl alexandria feedback --help` for options.
***
### Developer
Search the [Developer Index](/features/developer) — issues, merged pull requests, and READMEs from public code repositories, alongside curated documentation sites.
```bash CLI theme={null}
firecrawl developer "how do I configure retries" --limit 10
```
**Available Options:**
| Option | Description |
| - | - |
| `--limit ` | Number of results to return (default: 10, max: 100) |
| `--skills-only` | Search only indexed agent-skill files (default: false) |
| `--json` | Output as compact JSON |
| `--output ` | Save output to file |
| `--pretty` | Pretty print JSON output |
***
### Government
Search the [Firecrawl Government Index](/features/gov) — statutes, regulations, codes, court opinions, and other government publications from US federal, state, and local government sources.
```bash CLI theme={null}
firecrawl gov "food labeling requirements for allergens" --limit 10
```
**Available Options:**
| Option | Description |
| - | - |
| `--limit ` | Number of results to return (default: 10, max: 100) |
| `--json` | Output as compact JSON |
| `--pretty` | Pretty print JSON output |
| `--output ` | Save output to file |
| `--jurisdiction ` | Keep one jurisdiction: `us` or `us-` plus a state or territory code, such as `us-ca` |
| `--court ` | Keep one court, by CourtListener court id, such as `scotus` |
| `--court-type ` | Keep one type of court, such as `federal-appellate` or `state-supreme` |
| `--cites ` | Keep pages that cite one law or case, such as `"42 U.S.C. § 1983"` |
| `--domain ` | Keep pages from one site, such as `irs.gov` |
Filters keep only pages the index has labeled, so a filtered search can leave out relevant pages, and no results does not mean none exist.
***
### Map
Discover all URLs on a website quickly.
```bash CLI theme={null}
# Discover all URLs on a website
firecrawl map https://example.com
# Output as JSON
firecrawl map https://example.com --json
# Limit number of URLs
firecrawl map https://example.com --limit 500
```
#### Map Options
```bash CLI theme={null}
# Filter URLs by search query
firecrawl map https://example.com --search "blog"
# Include subdomains
firecrawl map https://example.com --include-subdomains
# Control sitemap usage
firecrawl map https://example.com --sitemap include # Use sitemap
firecrawl map https://example.com --sitemap skip # Skip sitemap
firecrawl map https://example.com --sitemap only # Only use sitemap
# Ignore query parameters (dedupe URLs)
firecrawl map https://example.com --ignore-query-parameters
# Wait for map to complete with timeout
firecrawl map https://example.com --wait --timeout 60
# Save to file
firecrawl map https://example.com -o urls.txt
firecrawl map https://example.com --json --pretty -o urls.json
```
**Available Options:**
| Option | Description |
| - | - |
| `--url ` | URL to map (alternative to positional argument) |
| `--limit ` | Maximum URLs to discover |
| `--search ` | Filter URLs by search query |
| `--sitemap ` | Sitemap handling: `include`, `skip`, `only` |
| `--include-subdomains` | Include subdomains |
| `--ignore-query-parameters` | Treat URLs with different params as same |
| `--wait` | Wait for map to complete |
| `--timeout ` | Timeout in seconds |
| `--json` | Output as JSON |
| `--output ` | Save output to file |
| `--pretty` | Pretty print JSON output |
***
### Interact
Scrape a page, then interact with it using natural language or code. Interact uses the most recent scrape by default, or you can pass a specific scrape ID.
```bash CLI theme={null}
# 1. Scrape Amazon's homepage (scrape ID is saved automatically)
firecrawl scrape https://www.amazon.com
# 2. Interact — search for a product and get its price
firecrawl interact "Search for iPhone 16 Pro Max"
firecrawl interact "Click on the first result and tell me the price"
# 3. Stop the session
firecrawl interact stop
```
**Available Options:**
| Option | Description |
| - | - |
| `-p, --prompt ` | AI prompt (alternative to positional argument) |
| `-c, --code ` | Code to execute in the live page session |
| `-s, --scrape-id ` | Scrape job ID (default: last scrape) |
| `--python` | Execute code as Python/Playwright |
| `--node` | Execute code as Node.js/Playwright (default) |
| `--bash` | Execute code as Bash |
| `--timeout ` | Timeout in seconds (1-300, default: 30) |
| `--output ` | Save output to file |
| `--json` | Output as JSON format |
***
### Crawl
Crawl an entire website starting from a URL.
```bash CLI theme={null}
# Start a crawl (returns job ID immediately)
firecrawl crawl https://example.com
# Wait for crawl to complete
firecrawl crawl https://example.com --wait
# Wait with progress indicator
firecrawl crawl https://example.com --wait --progress
```
#### Check Crawl Status
```bash CLI theme={null}
# Check crawl status using job ID
firecrawl crawl
# Example with a real job ID
firecrawl crawl 550e8400-e29b-41d4-a716-446655440000
```
#### Crawl Options
```bash CLI theme={null}
# Limit crawl depth and pages
firecrawl crawl https://example.com --limit 100 --max-depth 3 --wait
# Include only specific paths
firecrawl crawl https://example.com --include-paths /blog,/docs --wait
# Exclude specific paths
firecrawl crawl https://example.com --exclude-paths /admin,/login --wait
# Include subdomains
firecrawl crawl https://example.com --allow-subdomains --wait
# Crawl entire domain
firecrawl crawl https://example.com --crawl-entire-domain --wait
# Rate limiting
firecrawl crawl https://example.com --delay 1000 --max-concurrency 2 --wait
# Pass scrape options to each crawled page
firecrawl crawl https://example.com --scrape-options '{"formats":["markdown"],"onlyMainContent":true}'
# Send crawl completion events to a webhook
firecrawl crawl https://example.com --webhook '{"url":"https://example.com/webhook","events":["completed"]}'
# Cancel an active crawl
firecrawl crawl --cancel
# Custom polling interval and timeout
firecrawl crawl https://example.com --wait --poll-interval 10 --timeout 300
# Save results to file
firecrawl crawl https://example.com --wait --pretty -o results.json
```
**Available Options:**
| Option | Description |
| - | - |
| `--url ` | URL to crawl (alternative to positional argument) |
| `--wait` | Wait for crawl to complete |
| `--progress` | Show progress indicator while waiting |
| `--poll-interval ` | Polling interval (default: 5) |
| `--timeout ` | Timeout when waiting |
| `--status` | Check status of existing crawl job |
| `--limit ` | Maximum pages to crawl |
| `--max-depth ` | Maximum crawl depth |
| `--include-paths ` | Paths to include (comma-separated) |
| `--exclude-paths ` | Paths to exclude (comma-separated) |
| `--sitemap ` | Sitemap handling: `include`, `skip`, `only` |
| `--allow-subdomains` | Include subdomains |
| `--allow-external-links` | Follow external links |
| `--crawl-entire-domain` | Crawl entire domain |
| `--ignore-query-parameters` | Treat URLs with different params as same |
| `--delay ` | Delay between requests |
| `--max-concurrency ` | Maximum concurrent requests |
| `--scrape-options ` | JSON scrape options passed to each page |
| `--scrape-options-file ` | Path to scrape options JSON file |
| `--webhook ` | Webhook URL or configuration |
| `--cancel` | Cancel an active crawl job by job ID |
| `--output ` | Save output to file |
| `--pretty` | Pretty print JSON output |
***
### Monitor
Create recurring scrapes or crawls that diff each run against the previous snapshot. Add a goal when you want Firecrawl to judge which changed pages are meaningful for your use case.
```bash CLI theme={null}
firecrawl monitor create --name "Hacker News AI" \
--schedule "every 30 minutes" \
--goal "Alert when a new Hacker News story related to AI enters the top 10. Ignore changes to stories that are not about AI. Do not alert on changes outside the top 10." \
--page https://news.ycombinator.com
firecrawl monitor run
firecrawl monitor checks --limit 10
firecrawl monitor check --page-status changed
firecrawl monitor update \
--goal "Alert when a new Hacker News story related to AI enters the top 10. Do not alert on changes outside the top 10."
firecrawl monitor delete
```
Monitor goals should stay short and faithful to the user's intent: say what should trigger an alert, restate any stated scope, and include exclusions only when they are obvious or explicitly requested. If the user asks for "any change", keep the goal broad.
**Available Options:**
| Option | Description |
| - | - |
| `--name ` | Monitor name |
| `--goal ` | Goal for meaningful-change judging |
| `--cron ` | Cron schedule, for example `*/30 * * * *` |
| `--schedule ` | Natural-language schedule, for example `hourly` |
| `--timezone ` | Schedule timezone, default `UTC` |
| `--page ` | Single page URL to scrape on each check |
| `--scrape-urls ` | Comma-separated page URLs to scrape on each check |
| `--crawl-url ` | Root URL for a crawl target |
| `--webhook-url ` | Webhook destination |
| `--webhook-events ` | Comma-separated monitor events |
| `--email ` | Comma-separated email recipients |
| `--retention-days ` | Snapshot retention window |
| `--page-status ` | Filter pages on `monitor check` |
| `--state ` | Set monitor state on `monitor update`: active/paused |
***
### Agent
Search and gather data from the web using natural language prompts.
```bash CLI theme={null}
# Basic usage - URLs are optional
firecrawl agent "Find the top 5 AI startups and their funding amounts" --wait
# Focus on specific URLs
firecrawl agent "Compare pricing plans" --urls https://slack.com/pricing,https://teams.microsoft.com/pricing --wait
# Use a schema for structured output
firecrawl agent "Get company information" --urls https://example.com --schema '{"type":"object","properties":{"name":{"type":"string"},"founded":{"type":"number"}}}' --wait
# Use schema from a file
firecrawl agent "Get product details" --urls https://example.com --schema-file schema.json --wait
```
#### Agent Options
```bash CLI theme={null}
# Spark 2 is the default — every run executes on it
firecrawl agent "Competitive analysis across multiple domains" --model spark-2 --wait
# Deprecated: Spark 1 model names are still accepted, but route to spark-2.
# Set max credits to limit costs
firecrawl agent "Gather contact information from company websites" --max-credits 100 --wait
# Check status of an existing job
firecrawl agent --status
# Send agent events to a webhook
firecrawl agent "Extract product details" --urls https://example.com --webhook '{"url":"https://example.com/webhook","events":["completed","failed"]}'
# Cancel an active agent job
firecrawl agent --cancel
# Custom polling interval and timeout
firecrawl agent "Summarize recent blog posts" --wait --poll-interval 10 --timeout 300
# Save output to file
firecrawl agent "Find pricing information" --urls https://example.com --wait -o pricing.json --pretty
```
**Available Options:**
| Option | Description |
| - | - |
| `--urls ` | Optional list of URLs to focus the agent on (comma-separated) |
| `--model ` | Model to use. Defaults to `spark-2`, the model every run executes on. Spark 1 models are deprecated and route to `spark-2` |
| `--schema ` | JSON schema for structured output (inline JSON string) |
| `--schema-file ` | Path to JSON schema file for structured output |
| `--max-credits ` | Maximum credits to spend (job fails if limit reached) |
| `--webhook ` | Webhook URL or configuration |
| `--status` | Check status of existing agent job |
| `--cancel` | Cancel an active agent job by job ID |
| `--wait` | Wait for agent to complete before returning results |
| `--poll-interval ` | Polling interval when waiting (default: 5) |
| `--timeout ` | Timeout when waiting (default: no timeout) |
| `--output ` | Save output to file |
| `--json` | Output as JSON format |
***
### Credit Usage
Check your team's credit balance and usage.
```bash CLI theme={null}
# View credit usage
firecrawl credit-usage
# Output as JSON
firecrawl credit-usage --json --pretty
```
***
### Version
Display the CLI version.
```bash CLI theme={null}
firecrawl version
# or
firecrawl --version
```
## Global Options
These options are available for all commands:
| Option | Short | Description |
| - | - | - |
| `--status` | | Show version, auth, concurrency, and credits |
| `--api-key ` | `-k` | Override stored API key for this command |
| `--api-url ` | | Use custom API URL (for self-hosted/local development) |
| `--help` | `-h` | Show help for a command |
| `--version` | `-V` | Show CLI version |
`init` also accepts `--skip-auth`, `--skip-install`, `--skip-skills`, and `--agent `. See `firecrawl init --help`.
## Output Handling
The CLI outputs to stdout by default, making it easy to pipe or redirect:
```bash CLI theme={null}
# Pipe markdown to another command
firecrawl https://example.com | head -50
# Redirect to a file
firecrawl https://example.com > output.md
# Save JSON with pretty formatting
firecrawl https://example.com --format markdown,links --pretty -o data.json
```
### Format Behavior
* **Single format**: Outputs raw content (markdown text, HTML, etc.)
* **Multiple formats**: Outputs JSON with all requested data
```bash CLI theme={null}
# Raw markdown output
firecrawl https://example.com --format markdown
# JSON output with multiple formats
firecrawl https://example.com --format markdown,links
```
## Examples
### Quick Scrape
```bash CLI theme={null}
# Get markdown content from a URL (use --only-main-content for clean output)
firecrawl https://docs.firecrawl.dev --only-main-content
# Get HTML content
firecrawl https://example.com --html -o page.html
```
### Full Site Crawl
```bash CLI theme={null}
# Crawl a docs site with limits
firecrawl crawl https://docs.example.com --limit 50 --max-depth 2 --wait --progress -o docs.json
```
### Site Discovery
```bash CLI theme={null}
# Find all blog posts
firecrawl map https://example.com --search "blog" -o blog-urls.txt
```
### Research Workflow
```bash CLI theme={null}
# Search and scrape results for research
firecrawl search "machine learning best practices 2024" --scrape --scrape-formats markdown --pretty
```
### Agent
```bash CLI theme={null}
# URLs are optional
firecrawl agent "Find the top 5 AI startups and their funding amounts" --wait
# Focus on specific URLs
firecrawl agent "Compare pricing plans" --urls https://slack.com/pricing,https://teams.microsoft.com/pricing --wait
```
### Combine with Other Tools
```bash CLI theme={null}
# Extract URLs from search results
jq -r '.data.web[].url' search-results.json
# Get titles from search results
jq -r '.data.web[] | "\(.title): \(.url)"' search-results.json
# Extract links as JSON and print one URL per line
firecrawl https://example.com --format links --json | jq -r '.links[]'
# Count URLs from map
firecrawl map https://example.com | wc -l
```
## Telemetry
The CLI collects anonymous usage data during authentication to help improve the product:
* CLI version, OS, and Node.js version
* Development tool detection (e.g., Cursor, VS Code, Claude Code)
**No command data, URLs, or file contents are collected via the CLI.**
To disable telemetry, set the environment variable:
```bash CLI theme={null}
export FIRECRAWL_NO_TELEMETRY=1
```
## Open Source
The Firecrawl CLI and all three skill segments are open source on GitHub:
* [`firecrawl/cli`](https://github.com/firecrawl/cli) — the CLI and CLI skills (live web work)
* [`firecrawl/skills`](https://github.com/firecrawl/skills) — build skills (integrate Firecrawl into application code)
* [`firecrawl/firecrawl-workflows`](https://github.com/firecrawl/firecrawl-workflows) — workflow skills (repeatable deliverables such as research briefs, SEO audits, lead lists, and design clones)
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Security overview
Source: https://docs.firecrawl.dev/security
How Firecrawl protects your data: SOC 2 Type II, zero data retention, DPA, SSO, access controls, and data residency, in one place for your security review.
This page answers the questions a security or procurement team asks before approving Firecrawl. To explore them, reach out to our team on the [Enterprise page](https://www.firecrawl.dev/enterprise).
## Compliance and reports
* **SOC 2 Type II**: Firecrawl is SOC 2 Type II compliant (renewal in progress).
* **Trust Center**: the [Firecrawl Trust Center](https://trust.firecrawl.dev) lists our compliance status and controls. You can request the latest penetration test and our Access Control, Data Management, Information Security (AUP), and Third-Party Management policies there.
* **Continuous monitoring**: the Trust Center monitors controls covering data encryption, penetration testing, continuity and disaster recovery plans, data retention procedures, and deletion of customer data when an account is closed.
## Data handling and zero data retention
Zero Data Retention (ZDR) means Firecrawl does not persist page content or extracted data beyond the lifetime of the request or session. It is available on Enterprise plans and must be enabled for your team.
| Product | How to enable | What is not retained | Notes |
| - | - | - | - |
| [Scrape](/features/scrape#zero-data-retention-zdr) | `zeroDataRetention: true` | Page content and extracted data | Screenshots are not available in ZDR mode. Adds 1 credit per page. |
| [Interact](/features/interact#zero-data-retention-zdr) | `zeroDataRetention: true` on the first interact call | Page content and execution output | Session recordings and persistent profiles are not available in ZDR mode. |
| [Search, end-to-end ZDR](/features/search#end-to-end-zdr) | `enterprise: ["zdr"]` | Query and result data, at Firecrawl and at our upstream search provider | 10 credits per 10 results. |
| [Search, anonymized ZDR](/features/search#anonymized-zdr) | `enterprise: ["anon"]` | Query and result data at Firecrawl; the search provider may cache the anonymized query | 2 credits per 10 results. |
[PII redaction](/features/scrape#pii-redaction) can also remove personally identifiable information from scrape and parse output before it reaches you.
## Contracts, DPA, and subprocessors
* **DPA and custom contracts**: Enterprise customers can sign a Data Processing Agreement and custom MSAs, and we support vendor security reviews and questionnaires.
* **Subprocessors**: the current list is published in the [Trust Center](https://trust.firecrawl.dev/subprocessors). Subscribe there to get advance notice before a new subprocessor processes customer personal data.
* **Privacy**: see the [Privacy Policy](https://www.firecrawl.dev/privacy-policy).
## Identity and access control
* **[SSO and SCIM](/features/sso)**: SAML and OIDC single sign-on (Okta, Entra ID, Google Workspace, and more) and SCIM directory sync, so access follows your identity provider.
* **Static IP allowlisting**: route your traffic through dedicated IP addresses that you can allowlist on your systems.
* **[IP restrictions](/features/ip-restrictions)**: limit your team's API keys to an allowlist of IP addresses or CIDR ranges.
* **[Key restrictions](/features/key-restrictions)**: lock individual API keys to specific output formats and endpoints, enforced server-side.
* **Spend limits**: cap spending per API key or per team.
## Network protections
Firecrawl only fetches public web addresses on your behalf. These protections run server side on Firecrawl Cloud for every plan, including Free, on every request Firecrawl makes to fetch a URL. They are on by default, and no request option turns them off.
* **Private and reserved addresses**: Firecrawl's HTTP fetcher refuses private (RFC 1918 and IPv6 unique local), loopback, link-local, and other reserved IP addresses, including the cloud metadata address `169.254.169.254` and `localhost` names, before anything is sent. Alternate encodings such as decimal, hex, or IPv4-mapped IPv6 forms are normalized first, so they are refused too.
* **Every redirect hop**: the same check runs on the first request and again on each redirect, so a public URL can't redirect a fetch into a private address.
* **Egress outside our network**: page fetches and browser sessions, including the page's own subrequests, connect out through egress outside Firecrawl's internal network. A hostname that resolves to a private address, including through DNS rebinding, is resolved and connected outside our infrastructure, so it can't reach Firecrawl's internal services or cloud metadata.
* **Self-hosted Playwright service**: when it connects directly, the open-source Playwright service resolves each hostname once, checks the answer, and connects only to the address it checked. This DNS rebinding fix (GHSA-xmmq-vp8j-m5qf, CVE-2026-116066) was merged on October 21, 2026 and ships in v2.11.586 and later. With an upstream proxy configured, that proxy must enforce its own egress policy. Firecrawl Cloud does not route requests through this service. If you self-host, run v2.11.586 or later and leave `ALLOW_LOCAL_WEBHOOKS` unset, since setting it disables the private-address checks.
To block specific public sites or domains for your organization, use [Threat Protection](/features/threat-protection).
## Monitoring and threat controls
* **[Threat Protection](/features/threat-protection)**: block Firecrawl from fetching risky URLs, using a policy your organization controls and can lock.
* **[SIEM Audit Logging](/features/siem)**: stream a structured audit event for every scrape to your SIEM, starting with Microsoft Sentinel.
## Data residency
Firecrawl processes all data in the United States and does not offer EU data residency. With zero data retention, the content you scrape or search is not stored after the request completes.
## For AI agent and MCP users
The same controls apply when Firecrawl is called from an AI agent, the [MCP server](/mcp-server), the CLI, or an SDK. IP and key restrictions, Threat Protection, and SIEM audit logging are enforced server-side for your organization, so a key restricted to certain endpoints or formats stays restricted whichever client uses it. Zero data retention applies to any request that enables it.
## FAQ
> [accordion] Is Firecrawl ready for an enterprise security review?
>
> Yes. Firecrawl is SOC 2 Type II compliant (renewal in progress), offers zero data retention for scrape and interact plus two ZDR modes for search, signs DPAs, and supports SAML or OIDC SSO with SCIM. Server-side controls like IP and key restrictions, Threat Protection, and SIEM audit logging let your security team set and audit policy.
> [accordion] Is Firecrawl SOC 2 compliant?
>
> Yes. Firecrawl is SOC 2 Type II compliant, and our annual renewal audit is in progress. The [Trust Center](https://trust.firecrawl.dev) lists our current controls and policies.
> [accordion] Does Firecrawl offer zero data retention for search?
>
> Yes. End-to-end search ZDR (`enterprise: ["zdr"]`) has both Firecrawl and our upstream search provider enforce zero data retention, so no query or result data is stored anywhere in the pipeline. See [Search ZDR](/features/search#end-to-end-zdr).
> [accordion] Does Firecrawl block requests to private IP addresses and cloud metadata endpoints?
>
> Yes, on every plan and by default. Firecrawl's fetcher refuses private, loopback, link-local, and reserved addresses, including `169.254.169.254`, on the first request and every redirect hop, and all fetches connect out through egress outside Firecrawl's internal network, so a DNS rebinding answer can't reach our infrastructure. See [Network protections](#network-protections).
> [accordion] Will Firecrawl sign a DPA?
>
> Yes. Enterprise customers can sign a Data Processing Agreement and custom MSAs. Processing happens in the US. Contact [help@firecrawl.dev](mailto:help@firecrawl.dev).
> [accordion] Where is data processed?
>
> In the United States. Firecrawl offers US data residency and does not offer EU data residency.
> [accordion] Who are Firecrawl's subprocessors?
>
> The current list is in the [Trust Center](https://trust.firecrawl.dev/subprocessors), with advance notice to subscribers before a new subprocessor processes customer personal data.
> [accordion] How do we start a security review?
>
> Request the latest penetration test and policies from the [Trust Center](https://trust.firecrawl.dev), and email [help@firecrawl.dev](mailto:help@firecrawl.dev) or use the [Enterprise page](https://www.firecrawl.dev/enterprise) for questionnaires and contracts.
# Activity
Source: https://docs.firecrawl.dev/api-reference/endpoint/activity
api-reference/v2-openapi.json GET /team/activity
Lists your team's recent API activity from the last 24 hours. Returns metadata about each job including the job ID, which can be used with the corresponding GET endpoint (e.g. GET /crawl/{id}) to retrieve full results. Supports cursor-based pagination and filtering by endpoint.
Lists your recent API activity from the last 24 hours. Use this to discover job IDs, then retrieve results with the corresponding GET endpoint.
| Endpoint | Retrieval Endpoint |
| - | - |
| `scrape` | `GET /v2/scrape/{id}` |
| `crawl` | `GET /v2/crawl/{id}` |
| `batch_scrape` | `GET /v2/batch/scrape/{id}` |
| `agent` | `GET /v2/agent/{jobId}` |
## Team Management Endpoints
| Operation | API path | Docs page |
| - | - | - |
| Team activity | `GET /v2/team/activity` | [`activity`](/api-reference/endpoint/activity) |
| Credit usage | `GET /v2/team/credit-usage` | [`credit-usage`](/api-reference/endpoint/credit-usage) |
| Credit usage (historical) | `GET /v2/team/credit-usage/historical` | [`credit-usage-historical`](/api-reference/endpoint/credit-usage-historical) |
| Queue status | `GET /v2/team/queue-status` | [`queue-status`](/api-reference/endpoint/queue-status) |
# Agent
Source: https://docs.firecrawl.dev/api-reference/endpoint/agent
api-reference/v2-openapi.json POST /agent
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Cancel Agent
Source: https://docs.firecrawl.dev/api-reference/endpoint/agent-delete
api-reference/v2-openapi.json DELETE /agent/{jobId}
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Agent Status
Source: https://docs.firecrawl.dev/api-reference/endpoint/agent-get
api-reference/v2-openapi.json GET /agent/{jobId}
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# List Agent Runs
Source: https://docs.firecrawl.dev/api-reference/endpoint/agent-list
api-reference/v2-openapi.json GET /agent
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Agent Snapshot
Source: https://docs.firecrawl.dev/api-reference/endpoint/agent-snapshot
api-reference/v2-openapi.json GET /agent/{jobId}/snapshots/{snapshotId}
While an agent runs, it version-controls its output artifacts — the structured JSON result as it takes shape, plus any markdown, HTML, text, or screenshot artifacts it produces. Every change emits an `artifact.updated` [trace event](/api-reference/endpoint/agent-trace) referencing the new version by `snapshotId`. This endpoint fetches the full content of one such snapshot.
## What it's for
* **Partial results** — preview the agent's structured output before the run finishes. The JSON result artifact (`artifactId: "result"`) is snapshotted as it grows, so each `snapshotId` is a point-in-time view of the final `data`.
* **Rendered artifacts** — fetch the content of non-JSON artifacts the agent produced, such as a markdown report or a screenshot of a page it visited.
* **Run inspection** — pair with the trace to reconstruct exactly how the output evolved over the run.
## How it works
The `artifact.updated` event's `change` field tells you how the snapshot relates to the previous one: `init` (first version), `partial`, `append`, `modify`, or `update`. Each change gets a new `snapshotId` — fetch the latest one for the current state, or walk the history to diff versions.
The `snapshot` field in the response is the artifact content as a string. For `json` artifacts it is JSON-encoded — parse it before use.
> [!NOTE]
>
> Snapshots are recorded on Spark 2 runs — which is every new run. Jobs started on Spark 1 models before their retirement have no snapshots and return `400`.
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Agent Trace
Source: https://docs.firecrawl.dev/api-reference/endpoint/agent-trace
api-reference/v2-openapi.json GET /agent/{jobId}/trace
Every agent run records a canonical **execution trace**: an ordered stream of events describing everything the run did — which tools it called and what they returned, reasoning summaries, progress updates, browser sessions, and changes to its output artifacts. This is the same event stream that powers the live Activity view in the [Agent playground](https://www.firecrawl.dev/app/agent).
## What it's for
* **Debugging runs** — see the exact searches, scrapes, and extractions the agent performed, each tool's input (`tool_call.started`) and result (`tool_call.finished`), and where a run went wrong (`error.occurred`, and the terminal `run.finished` event's `outcome` and structured `error`).
* **Live progress UIs** — poll the trace while a job is `processing` to show what the agent is doing in real time. `progress.reported` events carry the run's phase (`planning`, `working`, `finalizing`) with a human-readable message, and `reasoning.summary` events narrate the agent's thinking.
* **Live browser view** — pass `?liveView=true` while a run is in flight to get `activeBrowserSessions`: the run's active browser sessions, each with a `liveViewUrl` you can embed to watch (or demo) the agent browsing.
* **Cost tracking** — `creditsUsed` reports credits consumed so far, capped at the run's `maxCredits` if one was set.
## How it works
Events are emitted by the run's agents — the `orchestrator` and its `subagent`s — and each event identifies its emitter in the `agent` field. Browser work happens inside an agent's own browser session and is reported through `browser.session.*` events, not by separate browser agents. Order events by `producerSequence` (per emitting agent). The `type` field discriminates the 13 event variants; see the response schema below for the full list and each variant's fields.
`artifact.updated` events don't carry the artifact content itself — they reference it by `snapshotId`, which you fetch with the [snapshot endpoint](/api-reference/endpoint/agent-snapshot).
Events can continue to land for a moment after `run.finished` arrives, so if you're polling a live run, keep a short tail window open before rendering the final state.
> [!NOTE]
>
> Traces are recorded on Spark 2 runs — which is every new run. Jobs started on Spark 1 models before their retirement have no trace and return `400`.
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Ask
Source: https://docs.firecrawl.dev/api-reference/endpoint/ask
api-reference/v2-openapi.json POST /support/ask
Diagnose Firecrawl job, account, and API usage issues with an AI support agent.
The `/support/ask` endpoint is an AI support agent that diagnoses issues with your Firecrawl jobs, account, and API usage. Send a question and receive a verified answer with actionable fix parameters — typically in 15–30 seconds.
## Designed for AI agents
`/support/ask` is built for **agent-to-agent** communication. If you're building an AI agent that uses Firecrawl, wire this endpoint into your error-handling flow so your agent can self-diagnose scraping failures, crawl issues, and configuration problems without human intervention.
Pass a `rationale` field to give the support agent context about what your end user is trying to accomplish. This helps prioritize the evidence gathering.
## How it works
1. **You describe the problem** — a natural-language question describing the issue.
2. **The agent investigates** — it inspects job logs, account state, documentation, and source code.
3. **The agent validates** — when possible, the agent tests a fix against the live Firecrawl API (e.g., retrying a scrape with adjusted parameters).
4. **You get a verified answer** — the response includes a prose `answer`, machine-readable `fixParameters` you can apply directly, and `validation` results showing whether the fix was tested.
## Authentication
Uses your Firecrawl API key as the bearer token. The request is automatically scoped to your team — you can only query your own jobs and account data.
```bash theme={null}
curl -X POST https://api.firecrawl.dev/v2/support/ask \
-H "Authorization: Bearer fc-YOUR_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"question": "my crawl returned 3 pages but I expected 50",
"rationale": "user is on their third failed crawl attempt today"
}'
```
## Response fields
| Field | Type | Description |
| - | - | - |
| `answer` | string | 2-4 sentence prose covering the diagnosis and fix |
| `confidence` | string | `high`, `medium`, or `low` |
| `fixParameters` | object \| null | API parameters to apply the fix (e.g., `{"waitFor": 5000}`) |
| `validation` | object \| null | Whether the fix was tested: `tested`, `result` (success/failure/skipped), `evidence` |
| `feedback` | object \| null | Present when the agent gets stuck; `{ blockedBy, attempted }`. Null on success. |
| `durationMs` | integer | Total execution time in milliseconds |
## Status codes
| Code | Meaning |
| - | - |
| `200` | Answered or stuck (envelope always returned) |
| `400` | Invalid JSON or schema violation |
| `401` | Missing or invalid bearer token |
| `504` | Hit 60s hard budget — partial envelope returned |
For the feature guide with integration examples, see the [Ask feature documentation](/features/ask).
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Batch Scrape
Source: https://docs.firecrawl.dev/api-reference/endpoint/batch-scrape
api-reference/v2-openapi.json POST /batch/scrape
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Cancel Batch Scrape
Source: https://docs.firecrawl.dev/api-reference/endpoint/batch-scrape-delete
api-reference/v2-openapi.json DELETE /batch/scrape/{id}
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Batch Scrape Status
Source: https://docs.firecrawl.dev/api-reference/endpoint/batch-scrape-get
api-reference/v2-openapi.json GET /batch/scrape/{id}
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Batch Scrape Errors
Source: https://docs.firecrawl.dev/api-reference/endpoint/batch-scrape-get-errors
api-reference/v2-openapi.json GET /batch/scrape/{id}/errors
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Create Interact Session
Source: https://docs.firecrawl.dev/api-reference/endpoint/browser-create
api-reference/v2-openapi.json POST /interact
Start a standalone Interact browser session you drive with code (no prior scrape required).
## Headers
| Header | Value |
| - | - |
| `Authorization` | `Bearer ` |
| `Content-Type` | `application/json` |
## Request Body
| Parameter | Type | Required | Default | Description |
| - | - | - | - | - |
| `ttl` | number | No | 600 | Total session lifetime in seconds (30-3600) |
| `activityTtl` | number | No | 300 | Seconds of inactivity before session is destroyed (10-3600) |
| `blockAds` | boolean | No | true | Block ads, trackers, and cookie popups, as in scrape |
| `profile` | object | No | — | Enable persistent storage across sessions. See below. |
| `profile.name` | string | Yes\* | — | Name for the profile (1-128 chars). Sessions with the same name share storage. |
| `profile.saveChanges` | boolean | No | `true` | When `true`, browser state is saved back to the profile on close. Set to `false` to load existing data without writing. Only one saver is allowed at a time. |
| `location` | object | No | — | Country the session browses from. Without it, sessions browse from the US. |
| `location.country` | string | Yes\* | — | ISO 3166-1 alpha-2 country code, such as `GB` or `DE`. Other values, such as `us-generic`, are rejected with a `400`. |
| `zeroDataRetention` | boolean | No | `false` | Run the session with [Zero Data Retention](/features/interact#zero-data-retention-zdr). Requires ZDR to be enabled for your team (`403` otherwise). Cannot be combined with `profile` (`400`). |
## Response
| Field | Type | Description |
| - | - | - |
| `success` | boolean | Whether the session was created |
| `id` | string | Unique session identifier |
| `cdpUrl` | string | WebSocket URL for CDP connections |
| `liveViewUrl` | string | URL to watch the session in real time |
| `interactiveLiveViewUrl` | string | URL to interact with the session in real time (click, type, scroll) |
| `expiresAt` | string | When the session will expire based on TTL |
### Example Request
```bash theme={null}
curl -X POST "https://api.firecrawl.dev/v2/interact" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"ttl": 120,
"location": { "country": "GB" }
}'
```
### Example Response
```json theme={null}
{
"success": true,
"id": "550e8400-e29b-41d4-a716-446655440000",
"cdpUrl": "wss://cdp-proxy.firecrawl.dev/cdp/550e8400-e29b-41d4-a716-446655440000",
"liveViewUrl": "https://liveview.firecrawl.dev/550e8400-e29b-41d4-a716-446655440000",
"interactiveLiveViewUrl": "https://liveview.firecrawl.dev/550e8400-e29b-41d4-a716-446655440000?interactive=true"
}
```
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Delete Interact Session
Source: https://docs.firecrawl.dev/api-reference/endpoint/browser-delete
api-reference/v2-openapi.json DELETE /interact/{sessionId}
Destroy a standalone Interact session and release its resources.
## Headers
| Header | Value |
| - | - |
| `Authorization` | `Bearer ` |
## Path Parameters
| Parameter | Type | Required | Description |
| - | - | - | - |
| `sessionId` | string | Yes | The Interact session ID to destroy |
## Response
| Field | Type | Description |
| - | - | - |
| `success` | boolean | Whether the session was successfully destroyed |
### Example Request
```bash theme={null}
curl -X DELETE "https://api.firecrawl.dev/v2/interact/550e8400-e29b-41d4-a716-446655440000" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY"
```
### Example Response
```json theme={null}
{
"success": true
}
```
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Execute Code in a Session
Source: https://docs.firecrawl.dev/api-reference/endpoint/browser-execute
api-reference/v2-openapi.json POST /interact/{sessionId}/execute
Run Playwright or agent-browser code in a standalone Interact session.
## Headers
| Header | Value |
| - | - |
| `Authorization` | `Bearer ` |
| `Content-Type` | `application/json` |
## Request Body
| Parameter | Type | Required | Default | Description |
| - | - | - | - | - |
| `code` | string | Yes | - | Code to execute (1-100,000 characters) |
| `language` | string | No | `"node"` | Language of the code: `"python"`, `"node"`, or `"bash"` (for agent-browser CLI commands) |
| `timeout` | number | No | - | Execution timeout in seconds (1-300) |
## Response
| Field | Type | Description |
| - | - | - |
| `success` | boolean | Whether the code executed successfully |
| `stdout` | string | Standard output from the code execution |
| `result` | string | Standard output from the code execution |
| `stderr` | string | Standard error output from the code execution |
| `exitCode` | number | Exit code of the executed process |
| `killed` | boolean | Whether the process was killed due to timeout |
| `error` | string | Error message if execution failed (only present on failure) |
### Example Request
```bash theme={null}
curl -X POST "https://api.firecrawl.dev/v2/interact/550e8400-e29b-41d4-a716-446655440000/execute" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"code": "await page.goto(\"https://example.com\")\ntitle = await page.title()\nprint(title)",
"language": "python"
}'
```
### Example Response (Success)
```json theme={null}
{
"success": true,
"result": "Example Domain"
}
```
### Example Response (Error)
```json theme={null}
{
"success": true,
"error": "TimeoutError: page.goto: Timeout 30000ms exceeded."
}
```
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# List Interact Sessions
Source: https://docs.firecrawl.dev/api-reference/endpoint/browser-list
api-reference/v2-openapi.json GET /interact
Retrieve your standalone Interact sessions, optionally filtered by status.
## Headers
| Header | Value |
| - | - |
| `Authorization` | `Bearer ` |
## Query Parameters
| Parameter | Type | Required | Description |
| - | - | - | - |
| `status` | string | No | Filter by session status: `"active"` or `"destroyed"` |
## Response
| Field | Type | Description |
| - | - | - |
| `success` | boolean | Whether the request succeeded |
| `sessions` | array | List of session objects |
### Session Object
| Field | Type | Description |
| - | - | - |
| `id` | string | Unique session identifier |
| `status` | string | Current session status (`"active"` or `"destroyed"`) |
| `cdpUrl` | string | WebSocket URL for CDP connections |
| `liveViewUrl` | string | URL to watch the session in real time |
| `interactiveLiveViewUrl` | string | URL to interact with the session in real time (click, type, scroll) |
| `createdAt` | string | ISO 8601 timestamp of session creation |
| `lastActivity` | string | ISO 8601 timestamp of last activity |
### Example Request
```bash theme={null}
curl -X GET "https://api.firecrawl.dev/v2/interact?status=active" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY"
```
### Example Response
```json theme={null}
{
"success": true,
"sessions": [
{
"id": "550e8400-e29b-41d4-a716-446655440000",
"status": "active",
"cdpUrl": "wss://cdp-proxy.firecrawl.dev/cdp/550e8400-e29b-41d4-a716-446655440000",
"liveViewUrl": "https://liveview.firecrawl.dev/550e8400-e29b-41d4-a716-446655440000",
"interactiveLiveViewUrl": "https://liveview.firecrawl.dev/550e8400-e29b-41d4-a716-446655440000?interactive=true",
"createdAt": "2025-06-01T12:00:00Z",
"lastActivity": "2025-06-01T12:05:30Z"
}
]
}
```
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Active Crawls
Source: https://docs.firecrawl.dev/api-reference/endpoint/crawl-active
api-reference/v2-openapi.json GET /crawl/active
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Cancel Crawl
Source: https://docs.firecrawl.dev/api-reference/endpoint/crawl-delete
api-reference/v2-openapi.json DELETE /crawl/{id}
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Crawl Status
Source: https://docs.firecrawl.dev/api-reference/endpoint/crawl-get
api-reference/v2-openapi.json GET /crawl/{id}
> [!NOTE]
>
> `total` counts completed, active, queued, and backlogged pages and excludes failed ones, so `completed == total` on a finished crawl does not mean every discovered page succeeded. Pair the counters with [Get Crawl Errors](/api-reference/endpoint/crawl-get-errors) to see pages that were attempted but not returned, and see [Execution and result accounting](/features/crawl#execution-and-result-accounting) for how to read them together and when to stop paging with `next`.
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Crawl Errors
Source: https://docs.firecrawl.dev/api-reference/endpoint/crawl-get-errors
api-reference/v2-openapi.json GET /crawl/{id}/errors
> [!NOTE]
>
> This endpoint records pages that did not make it into the crawl's `data` array: `errors` for scrapes Firecrawl failed, and `robotsBlocked` for URLs blocked by robots.txt. Failed pages appear nowhere in the [crawl status](/api-reference/endpoint/crawl-get) counters, so this is the only place to find them — but the list is not guaranteed complete, because some internal failure classes are filtered out before the response is built. See [Execution and result accounting](/features/crawl#execution-and-result-accounting) for how to read it alongside the status counters.
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Crawl Params Preview
Source: https://docs.firecrawl.dev/api-reference/endpoint/crawl-params-preview
api-reference/v2-openapi.json POST /crawl/params-preview
# Crawl
Source: https://docs.firecrawl.dev/api-reference/endpoint/crawl-post
api-reference/v2-openapi.json POST /crawl
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Search the Developer Index
Source: https://docs.firecrawl.dev/api-reference/endpoint/developer-search
api-reference/v2-openapi.json GET /search/developer
Search issues, merged pull requests, and READMEs from public code repositories, alongside curated documentation sites. Results are ranked and carry the matched passages in markdown.
`POST` is available on the same path when you want to pass array filters as JSON.
Repeatable filters accept either form on `GET`: a repeated query parameter such as `types=issue&types=pull_request`, or one comma separated value such as `types=issue,pull_request`.
## How `repos` and `sources` scope a search
The index has two halves, and these two filters scope them independently:
* `repos` scopes the repository half, meaning the `issue`, `pull_request`, and `readme` types
* `sources` scopes the documentation half, meaning the `doc` type
* Passing both combines the two halves rather than intersecting them, so you get matching results from either
Because each filter only applies to one half, a filter that cannot match any requested type is rejected rather than silently returning nothing:
* `repos` with no repository type in `types` returns `400`, reporting that `repos` cannot match any requested type and that you should add repository types or drop `repos`
* `sources` with no `doc` in `types` returns `400` with `sources cannot match any requested type; add doc or drop sources`
## How the repository filters scope a search
The seven repository filters — `language` (such as `Rust`), `topic` (such as `async`), `license` (such as `MIT`), `min_stars`, `max_stars`, `archived`, and `fork` — describe a code repository. Most documentation pages in the index come from a crawled website with no repository behind it, and no repository fact can admit or exclude such a page.
A request that sends one of these filters and no `sources` scope therefore gets no `doc` results. Its response holds repository evidence only: the `issue`, `pull_request`, and `readme` types, because the documentation half of the index never ran. This is the design, not an index fault.
To keep documentation results, drop the repository filters. You can also scope the documentation half with `sources`, then read the `sources` echo in the response to confirm the id is indexed.
```bash cURL theme={null}
# No API key needed to get started; add -H "Authorization: Bearer $FIRECRAWL_API_KEY" for higher rate limits:
curl -s "https://api.firecrawl.dev/v2/search/developer?query=how%20do%20I%20configure%20retries&k=10&language=Rust&license=MIT"
```
```bash cURL (POST) theme={null}
curl -X POST https://api.firecrawl.dev/v2/search/developer \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"query": "how do I configure retries",
"k": 10,
"types": ["issue", "pull_request"],
"language": "Rust",
"license": "MIT"
}'
```
## Which values `sources` accepts
`sources` is not a fixed enum. It takes documentation source ids, each a nonempty string of at most 512 characters, and at most 20 per request. The ids reflect the documentation sites in the index, and the set grows over time.
To confirm an id resolves, pass it and read the `sources` array the response adds. It appears only when you sent `sources`, and reports each id exactly as you requested it along with whether it is indexed:
```json theme={null}
{
"success": true,
"results": [],
"sources": [
{ "source": "some-docs-site", "indexed": true },
{ "source": "unknown-docs-site", "indexed": false }
]
}
```
`indexed: true` means the source has a published generation, so documentation evidence from it may appear. `indexed: false` means nothing from that id can match, which distinguishes an id that is not in the index from a query that simply found nothing.
`repos` echoes back the same way, as a `repos` array reporting `indexed` plus a per type breakdown under `types`:
```json theme={null}
{
"success": true,
"results": [],
"repos": [
{
"repo": "firecrawl/firecrawl",
"indexed": true,
"types": { "issue": true, "pullRequest": true, "readme": true }
}
]
}
```
For a workflow overview, see the [Developer Index guide](/features/developer).
# Endpoint Feedback
Source: https://docs.firecrawl.dev/api-reference/endpoint/feedback
api-reference/v2-openapi.json POST /feedback
Submit feedback for a completed v2 endpoint job.
Use endpoint feedback to tell Firecrawl whether a completed job result was useful, partial, or bad. This is for endpoint-level output quality on jobs such as `scrape`, `parse`, `map`, and `search`.
The generic feedback schema can carry search-style fields too, but [Search Feedback](/api-reference/endpoint/search-feedback) is the preferred search-specific entry point because it is scoped to a search job ID and highlights valuable sources, missing content, query suggestions, and refund behavior.
### Example Request
```bash theme={null}
curl -X POST "https://api.firecrawl.dev/v2/feedback" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"endpoint": "scrape",
"jobId": "550e8400-e29b-41d4-a716-446655440000",
"rating": "partial",
"issues": ["missing_markdown"],
"note": "The pricing table was missing from the markdown output.",
"url": "https://example.com/pricing"
}'
```
# Search the Government Index
Source: https://docs.firecrawl.dev/api-reference/endpoint/gov-search
api-reference/v2-openapi.json GET /search/gov
Search primary law and regulatory material from US federal, state, and local government sources: statutes, regulations, codes, court opinions, and other government publications. Results come back in the standard `web` group, the same shape as a web result from [`/search`](/api-reference/endpoint/search). Send `sources: ["gov"]` to get the same results in a `gov` group with the index's labels: `jurisdiction`, `court`, `courtType`, `cites`, `citedAs`, `lang`, and `updatedAt`. See [Index labels](/features/gov#index-labels).
`POST` is available on the same path with the same fields as a JSON body. Unknown fields and invalid filter values are rejected with `400`, and the error says which value to fix.
`query` is required. Include the jurisdiction, agency or citation, and relevant date when known. `k` is the result count, from 1 to 100, defaulting to 10; general `/search` uses `limit` instead.
Calls count toward the Government Index limit of 300 a minute and your plan's daily Government Index limit. This endpoint shares both with the `gov` category on `/search` and the Government Index tool in Alexandria. Over either limit, this endpoint returns `429` with a `Retry-After` header. See [rate limits](/rate-limits#government-and-research-indexes).
Results are matched excerpts and may include historical versions, bill text, guidance, or third-party reproductions. Verify the issuer, jurisdiction, enacted/effective status, and version before citing current governing law. Read the source behind a match when the snippet is insufficient. The index focuses on US material; no hits does not establish that no applicable law exists.
## Filters
All filters are optional and combine with AND semantics.
| Field | Keeps only pages that |
| - | - |
| `jurisdiction` | belong to one jurisdiction: `us` for federal, or `us-` plus a two-letter state or territory code, such as `us-ca` or `us-dc`. |
| `court` | are labeled for one court, by CourtListener court id, such as `scotus`, `ca9` or `nysd`. |
| `courtType` | come from one type of court: `federal-supreme`, `federal-appellate`, `federal-district`, `federal-bankruptcy`, `federal-special`, `military`, `state-supreme`, `state-appellate`, `state-trial`, `state-special`, or `state-attorney-general`. |
| `cites` | cite a law or case, as a printed citation such as `42 U.S.C. § 1983` or `5 U.S. 137`, or a citation id such as `us:usc:42:1983`. Pass up to 32 to keep pages citing any of them: repeat the parameter on `GET`, or send a list in a `POST` body. |
| `domain` | come from one site, such as `irs.gov`. |
Filters keep only pages the index has labeled, so a filtered search can leave out relevant pages, and no results does not mean none exist. Court labels are most complete for federal courts and case-law collections.
```bash cURL theme={null}
# No API key needed to get started; add -H "Authorization: Bearer $FIRECRAWL_API_KEY" for higher rate limits:
curl -s "https://api.firecrawl.dev/v2/search/gov?query=food%20labeling%20requirements%20for%20allergens&k=10"
```
```bash cURL (POST) theme={null}
curl -X POST https://api.firecrawl.dev/v2/search/gov \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"query": "food labeling requirements for allergens",
"k": 10
}'
```
For a workflow overview, see the [Government Index guide](/features/gov).
# Map
Source: https://docs.firecrawl.dev/api-reference/endpoint/map
api-reference/v2-openapi.json POST /map
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Get Monitor Check
Source: https://docs.firecrawl.dev/api-reference/endpoint/monitor-check-get
api-reference/v2-openapi.json GET /monitor/{monitorId}/checks/{checkId}
# List Monitor Checks
Source: https://docs.firecrawl.dev/api-reference/endpoint/monitor-checks-list
api-reference/v2-openapi.json GET /monitor/{monitorId}/checks
# Create Monitor
Source: https://docs.firecrawl.dev/api-reference/endpoint/monitor-create
api-reference/v2-openapi.json POST /monitor
# Delete Monitor
Source: https://docs.firecrawl.dev/api-reference/endpoint/monitor-delete
api-reference/v2-openapi.json DELETE /monitor/{monitorId}
# Get Monitor
Source: https://docs.firecrawl.dev/api-reference/endpoint/monitor-get
api-reference/v2-openapi.json GET /monitor/{monitorId}
# List Monitors
Source: https://docs.firecrawl.dev/api-reference/endpoint/monitor-list
api-reference/v2-openapi.json GET /monitor
# Run Monitor
Source: https://docs.firecrawl.dev/api-reference/endpoint/monitor-run
api-reference/v2-openapi.json POST /monitor/{monitorId}/run
# Update Monitor
Source: https://docs.firecrawl.dev/api-reference/endpoint/monitor-update
api-reference/v2-openapi.json PATCH /monitor/{monitorId}
# Parse
Source: https://docs.firecrawl.dev/api-reference/endpoint/parse
api-reference/v2-openapi.json POST /parse
Upload a local or non-public document and convert it into clean, LLM-ready context. `/parse` accepts file bytes via `multipart/form-data` and returns Markdown, JSON, HTML, links, images, or a summary — with reading order and tables preserved.
* Turn PDF, Word, Excel, PowerPoint, OpenDocument, EPUB, CSV, HTML, and more into Markdown or structured JSON
* Up to **5x faster** parsing via a Rust-based engine
* Files up to **50 MB** per request
* Zero Data Retention support
## When to use `/parse`
Use `/parse` when the source document is **a local file** or **not publicly accessible by URL**. If you have a public URL that points to a document, prefer [`/scrape`](/api-reference/endpoint/scrape) — it auto-detects the file type from the extension or content type and parses it the same way.
| Source | Endpoint |
| - | - |
| Public URL to a document (e.g. `https://example.com/report.pdf`) | [`POST /scrape`](/api-reference/endpoint/scrape) |
| Local file or non-public bytes (PDF, DOCX, XLSX, HTML, …) | `POST /parse` (this endpoint) |
> [!TIP]
>
> **Using Firecrawl through MCP?** Use `firecrawl_parse` for local files. Local MCP can read the file directly when configured with `FIRECRAWL_API_URL`. Remote hosted MCP returns a short-lived upload command first, then parses the returned `uploadRef`. Public document URLs should still use `/scrape`.
# Parse Formats
Source: https://docs.firecrawl.dev/api-reference/endpoint/parse-formats
api-reference/v2-openapi.json GET /parse/formats
Lists every file format [`/parse`](/api-reference/endpoint/parse) accepts, with its file extensions and MIME types. The list is built from the same rules `/parse` uses to validate uploads, so you can check a file before sending it instead of keeping your own copy of the supported types.
Each entry has a `kind` of `document` or `image`. Image formats are OCR'd and carry `available: false` where image OCR is not enabled; uploads of those formats are rejected with `UNSUPPORTED_FILE_TYPE` until it is.
The list changes rarely. Responses carry `Cache-Control: private, max-age=3600`, so caching them for up to an hour is safe.
# Inspect or Read Paper
Source: https://docs.firecrawl.dev/api-reference/endpoint/research-paper
api-reference/v2-openapi.json GET /search/research/papers/{id}
Inspect paper metadata by id, or add a `query` parameter to read the most relevant full-text passages for a question.
Accepted ids include canonical `paperId` values and source-specific `primaryId` values (e.g. `arxiv:1706.03762`).
For a workflow overview, see the [Research Index guide](/features/research).
# Look Up Protein
Source: https://docs.firecrawl.dev/api-reference/endpoint/research-protein
api-reference/v2-openapi.json GET /search/research/proteins
Look up one protein by UniProt accession, entry name, gene symbol, or exact protein name. The response gives its curated subcellular location, function, and GO cellular-component terms from UniProtKB/Swiss-Prot, the reviewed section of UniProtKB. Each statement carries its evidence kind and, where UniProt cites one, a `pmid:` paper id in the form [`GET /search/research/papers/{id}`](/api-reference/endpoint/research-paper) accepts. A GO term's `paperIds` can be empty, and only GO terms of human entries have paper ids.
`match` says how the lookup resolved:
* `found`: one entry matched, and `protein` holds its annotation.
* `ambiguous`: the identifier names more than one entry, or matched only outside the requested organism. `candidates` lists up to 10 entries. Call again with one candidate's `accession`.
* `not_found`: no entry matches. This is a `200`, not a `404`.
Protein data from UniProtKB/Swiss-Prot. Copyright [UniProt Consortium](https://www.uniprot.org). Licensed under [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/). No warranty, see the [UniProt license](https://www.uniprot.org/help/license). Selected fields, reformatted. Every `200` response repeats this in `notice` and names the UniProt release in `release`.
For the resolution rules and the evidence kinds, see the [Research Index guide](/features/research#look-up-a-protein).
# Find Related Papers
Source: https://docs.firecrawl.dev/api-reference/endpoint/research-related-papers
api-reference/v2-openapi.json GET /search/research/papers/{id}/similar
Expand from a seed paper through structural expansion and rank candidate papers against a natural-language `intent`. Use `mode` to choose similar papers, citers, or references.
For a workflow overview, see the [Research Index guide](/features/research).
# Search Papers
Source: https://docs.firecrawl.dev/api-reference/endpoint/research-search-papers
api-reference/v2-openapi.json GET /search/research/papers
Search papers by topic, method, benchmark, author, or category. Results include canonical `paperId`, preferred `primaryId`, source ids, title, abstract, authors, creation and update dates, score, and optional ranking signals. Pass `sort=date_desc` to return the newest of the most relevant matches, newest first by created date. It does not list every paper in a date range; add `from` and `to` for that.
For a workflow overview, see the [Research Index guide](/features/research).
# Scrape
Source: https://docs.firecrawl.dev/api-reference/endpoint/scrape
api-reference/v2-openapi.json POST /scrape
## Capabilities
[Capabilities](/capabilities) is the single page listing what a scrape can do to a page, which of those capabilities run in a self-hosted deployment, and which endpoints accept a request with no API key.
## Interactions
For browser interactions (clicking, typing, navigating, extracting dynamic content), use the [Interact endpoint](/features/interact). Scrape a page first, then call `POST /v2/scrape/{scrapeId}/interact` with a natural-language prompt or Playwright code to take actions on the page.
See the [Interact documentation](/features/interact) for full details and examples.
Optionally you can also use the `actions` parameter, although it's not recommended to use it for complex interactions.
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Stop Interacting
Source: https://docs.firecrawl.dev/api-reference/endpoint/scrape-browser-delete
api-reference/v2-openapi.json DELETE /scrape/{jobId}/interact
Stop the interactive browser session associated with a scrape job.
Use this endpoint to stop the interactive browser session for a scrape job. Stopping the session releases browser resources and finalizes billing.
Credits are billed based on session duration: **7 credits per browser minute** if the session used a `prompt`, or **2 credits per browser minute** if it did not. Duration is prorated by the second, with a minimum charge of one browser minute.
## Path Parameters
| Parameter | Type | Required | Description |
| - | - | - | - |
| `jobId` | string (UUID) | Yes | The scrape job ID associated with the browser session |
## Response
| Field | Type | Description |
| - | - | - |
| `success` | boolean | Whether the session was successfully destroyed |
| `sessionDurationMs` | number | Total session duration in milliseconds |
| `creditsBilled` | number | Number of credits billed for the session |
| `error` | string | Error message (only present on failure) |
### Example Request
```bash theme={null}
curl -X DELETE "https://api.firecrawl.dev/v2/scrape/550e8400-e29b-41d4-a716-446655440000/interact" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY"
```
### Example Response
```json theme={null}
{
"success": true
}
```
### Error Codes
| Status | Description |
| - | - |
| `403` | Session belongs to a different team |
| `404` | No browser session found for this scrape job |
For detailed usage with examples, see the [Interact feature guide](/features/interact).
# Interact with a Scraped Page
Source: https://docs.firecrawl.dev/api-reference/endpoint/scrape-execute
api-reference/v2-openapi.json POST /scrape/{jobId}/interact
Execute code or an AI prompt in the browser session bound to a scrape job.
Use this endpoint to continue interacting with the same browser state initialized from a previous scrape. Either `code` or `prompt` must be provided — not both.
`POST /v2/scrape/{jobId}/interact` handles the full lifecycle:
1. If no browser session exists for this scrape job yet, Firecrawl creates one at the same page state as the original scrape, browsing from the scrape's `location.country` (the US if the scrape set none).
2. When `code` is provided, Firecrawl runs it in the browser sandbox. When `prompt` is provided, an AI agent automates the task using natural language.
3. Later `POST /interact` calls on the same `jobId` reuse the same live browser state.
When you are done, call `DELETE /v2/scrape/{jobId}/interact` to stop the session.
## Path Parameters
| Parameter | Type | Required | Description |
| - | - | - | - |
| `jobId` | string (UUID) | Yes | The scrape job ID from `data.metadata.scrapeId` in the scrape response |
## Request Body
| Parameter | Type | Required | Default | Description |
| - | - | - | - | - |
| `code` | string | No | — | Code to execute in the browser sandbox (1–100,000 chars). Required if `prompt` is not set. |
| `prompt` | string | No | — | Natural language task for the AI agent (1–10,000 chars). Required if `code` is not set. |
| `language` | string | No | `"node"` | One of `"python"`, `"node"`, or `"bash"`. Only used with `code`. |
| `timeout` | number | No | `30` | Execution timeout in seconds (1–300). |
| `origin` | string | No | — | Optional origin label used for telemetry. |
| `zeroDataRetention` | boolean | No | `false` | Run the session with [Zero Data Retention](/features/interact#zero-data-retention-zdr). Requires ZDR to be enabled for your team. Applied automatically when the scrape itself used ZDR. |
| `url` | string | No | — | Page to open in a new session when the original scrape's context is unavailable, such as after a ZDR scrape. The scrape's actions are not replayed. |
## Response
| Field | Type | Description |
| - | - | - |
| `success` | boolean | Whether the execution completed without errors |
| `cdpUrl` | string | Raw Chrome DevTools Protocol (CDP) WebSocket URL for the browser session. Connect directly with Playwright, Puppeteer, or any CDP client |
| `liveViewUrl` | string | Read-only live view URL for the browser session |
| `interactiveLiveViewUrl` | string | Interactive live view URL (viewers can control the browser) |
| `output` | string | AI agent's final response (only present when using `prompt`) |
| `stdout` | string | Standard output from the code execution |
| `result` | string | Return value — last expression value for Node.js, final page snapshot for `prompt` |
| `stderr` | string | Standard error output |
| `exitCode` | number | Exit code of the execution (`0` = success) |
| `killed` | boolean | Whether the execution was terminated due to timeout |
| `error` | string | Error message (only present on failure) |
### Example Request (Code)
```bash theme={null}
curl -X POST "https://api.firecrawl.dev/v2/scrape/550e8400-e29b-41d4-a716-446655440000/interact" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"code": "const title = await page.title(); JSON.stringify({ title });",
"language": "node",
"timeout": 30
}'
```
### Example Response (Code)
```json theme={null}
{
"success": true,
"cdpUrl": "wss://browser.firecrawl.dev/...",
"liveViewUrl": "https://liveview.firecrawl.dev/...",
"interactiveLiveViewUrl": "https://liveview.firecrawl.dev/...",
"stdout": "",
"result": "{\"title\":\"Example Domain\"}",
"stderr": "",
"exitCode": 0,
"killed": false
}
```
### Example Request (Prompt)
```bash theme={null}
curl -X POST "https://api.firecrawl.dev/v2/scrape/550e8400-e29b-41d4-a716-446655440000/interact" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"prompt": "Find the pricing section and tell me the price of the Pro plan",
"timeout": 60
}'
```
### Example Response (Prompt)
```json theme={null}
{
"success": true,
"cdpUrl": "wss://browser.firecrawl.dev/...",
"liveViewUrl": "https://liveview.firecrawl.dev/...",
"interactiveLiveViewUrl": "https://liveview.firecrawl.dev/...",
"output": "The Pro plan costs $49/month and includes unlimited scrapes, priority support, and custom integrations.",
"stdout": "...",
"result": "...",
"stderr": "",
"exitCode": 0,
"killed": false
}
```
### Error Codes
| Status | Description |
| - | - |
| `402` | Insufficient credits for a browser session |
| `403` | Scrape job belongs to a different team, or `zeroDataRetention` was requested but ZDR is not enabled for your team |
| `404` | Scrape job not found |
| `409` | Replay context unavailable — rerun the scrape and try again, or pass `url`. Also returned when `zeroDataRetention` is requested on an existing session that was started without ZDR |
| `410` | Browser session has already been destroyed |
| `429` | Maximum concurrent browser sessions reached |
| `502` | Browser service or AI agent execution failed |
| `503` | Browser feature not configured (self-hosted only) |
For detailed usage with examples, see the [Interact feature guide](/features/interact).
# Search
Source: https://docs.firecrawl.dev/api-reference/endpoint/search
api-reference/v2-openapi.json POST /search
The search endpoint combines web search with Firecrawl's scraping capabilities to return full page content for any query.
Include `scrapeOptions` with `formats: [{"type": "markdown"}]` to get complete markdown content for each search result otherwise you will default to getting the results (url, title, description). You can also use other formats like `{"type": "summary"}` for condensed content.
## Supported query operators
We support a variety of query operators that allow you to filter your searches better.
| Operator | Functionality | Examples |
| - | - | - |
| `""` | Non-fuzzy matches a string of text | `"Firecrawl"` |
| `-` | Excludes certain keywords or negates other operators | `-bad`, `-site:firecrawl.dev` |
| `site:` | Only returns results from a specified website | `site:firecrawl.dev` |
| `filetype:` | Only returns results with a specific file extension | `filetype:pdf`, `-filetype:pdf` |
| `inurl:` | Only returns results that include a word in the URL | `inurl:firecrawl` |
| `allinurl:` | Only returns results that include multiple words in the URL | `allinurl:git firecrawl` |
| `intitle:` | Only returns results that include a word in the title of the page | `intitle:Firecrawl` |
| `allintitle:` | Only returns results that include multiple words in the title of the page | `allintitle:firecrawl playground` |
| `related:` | Only returns results that are related to a specific domain | `related:firecrawl.dev` |
| `imagesize:` | Only returns images with exact dimensions | `imagesize:1920x1080` |
| `larger:` | Only returns images larger than specified dimensions | `larger:1920x1080` |
## Location Parameter
Use the `location` parameter to get geo-targeted search results. Format: `"string"`. Examples: `"Germany"`, `"San Francisco,California,United States"`.
See the [complete list of supported locations](https://firecrawl.dev/search_locations.json) for all available countries and languages.
## Country Parameter
Use the `country` parameter to specify the country for search results using ISO country codes. Default: `"US"`.
Examples: `"US"`, `"DE"`, `"FR"`, `"JP"`, `"UK"`, `"CA"`.
```json theme={null}
{
"query": "restaurants",
"country": "DE"
}
```
## Categories Parameter
Filter search results by specific categories using the `categories` parameter:
* **`research`**: Restrict web search to academic and research websites (arxiv.org, nature.com, pubmed.ncbi.nlm.nih.gov, and similar). Results are web pages, returned in `data.web`. For paper records, use [`GET /search/research/papers`](/api-reference/endpoint/research-search-papers)
* **`pdf`**: Search for PDFs
* **`developer`**: Search the [Developer Index](/features/developer) — issues, merged pull requests, and READMEs from public code repositories, alongside curated documentation sites
* **`gov`**: Search the [Firecrawl Government Index](/features/gov) — statutes, regulations, codes, court opinions, and other government publications. Cannot be combined with other categories and takes no filters; use [`/search/gov`](/api-reference/endpoint/gov-search#filters) to filter
> [!NOTE]
>
> **The `github` category was removed.** Requests that include it return a `400` error. Use `developer` to search GitHub issues, pull requests, and READMEs, or `includeDomains: ["github.com"]` to keep web results from github.com.
### Example Usage
```json theme={null}
{
"query": "machine learning",
"categories": ["research", "pdf"],
"limit": 10
}
```
## Domain Filters
Use `includeDomains` to restrict results to specific domains, or `excludeDomains` to remove specific domains from the search. Domains should be hostnames only, without protocol or path.
`includeDomains` and `excludeDomains` are mutually exclusive.
### Include Domains Example
```json theme={null}
{
"query": "web scraping",
"includeDomains": ["firecrawl.dev", "docs.firecrawl.dev"],
"limit": 10
}
```
### Exclude Domains Example
```json theme={null}
{
"query": "web scraping tools",
"excludeDomains": ["example.com"],
"limit": 10
}
```
### Category Response
Each result includes a `category` field indicating its source:
```json theme={null}
{
"success": true,
"data": {
"web": [
{
"url": "https://arxiv.org/abs/2024.12345",
"title": "ML Research Paper",
"description": "Latest advances in machine learning",
"category": "research"
},
{
"url": "https://example.com/ml-survey.pdf",
"title": "ML Survey",
"description": "A survey of machine learning methods",
"category": "pdf"
}
]
}
}
```
## Time-Based Search
Use the `tbs` parameter to filter results by time periods, including custom date ranges. See the [Search Feature documentation](https://docs.firecrawl.dev/features/search#time-based-search) for detailed examples and supported formats.
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Search Feedback
Source: https://docs.firecrawl.dev/api-reference/endpoint/search-feedback
api-reference/v2-openapi.json POST /search/{jobId}/feedback
Submit quality feedback for a search job and help improve Firecrawl search results.
Use search feedback after a `search` result is used or fails to help. Feedback improves result quality and can refund 1 credit for the first feedback submission on a search job, subject to team limits.
Use `valuableResults` to mark useful results by where they appeared in the response. Each entry names the `source` group (`web`, `images`, or `news`) and the result's 1-indexed `position` within that group, because each group is numbered from 1 independently. List every useful result: unlisted results are treated as not useful, and positions beyond what a group returned are ignored. This works for news and image results that have no `url`. Use `valuableSources` for useful URLs, including ones that were not among the returned results.
### Example Request
```bash theme={null}
curl -X POST "https://api.firecrawl.dev/v2/search/550e8400-e29b-41d4-a716-446655440000/feedback" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"rating": "good",
"valuableSources": [
{
"url": "https://docs.firecrawl.dev/features/search",
"reason": "Most up-to-date description of /search."
}
],
"valuableResults": [
{
"source": "web",
"position": 1,
"reason": "Answered the question directly."
},
{
"source": "news",
"position": 2
}
],
"missingContent": [
{
"topic": "Pricing for the search endpoint",
"description": "No pricing tier table for /search specifically."
}
],
"querySuggestions": "Boost docs.firecrawl.dev for queries that mention Firecrawl"
}'
```
# Errors
Source: https://docs.firecrawl.dev/api-reference/errors
Every API error code, what causes it, how to remedy it, and whether to retry.
Every Firecrawl error response uses the same JSON shape. Look up the `error` value (or HTTP status) in the table below to find the cause, remedy, and whether the request is safe to retry.
> [!NOTE]
>
> This catalog covers the errors most agents and clients will encounter. It is non-exhaustive — if you receive an error not listed here, please [open an issue](https://github.com/firecrawl/firecrawl/issues) so we can document it.
## Error response shape
All non-2xx responses return JSON with a top-level `success: false` and a string `error`. Some endpoints include additional fields (`details`, `code`) when more context is available.
```json theme={null}
{
"success": false,
"error": "Unauthorized: Invalid token",
"details": "Optional structured details (only present on some errors)"
}
```
| Field | Type | Description |
| - | - | - |
| `success` | `boolean` | Always `false` on errors. |
| `error` | `string` | Human-readable error message. Use this to look up the row below. |
| `details` | `any` | Optional. Structured per-field validation errors when applicable. |
## Errors
| HTTP | `error` (typical message) | Cause | Remedy | Retryable |
| - | - | - | - | - |
| 400 | `Bad Request` / validation message | Request body failed schema validation (missing or invalid fields). | Fix the request payload using the endpoint reference. Check `details` for fields. | No |
| 400 | `Invalid URL` | The `url` field is missing, malformed, or uses an unsupported scheme. | Pass an absolute `http(s)://` URL. | No |
| 400 | `THIRD_PARTY_DATA_UNSUPPORTED_URL` | The URL belongs to a site that a third-party data provider serves, but the provider only serves a record's own page (such as a profile page), not the sub-pages under it. The response has this value in `code`. | Scrape the record's own page instead of a sub-page or listing under it. | No |
| 400 | `THIRD_PARTY_DATA_UNSUPPORTED_OPTION` | Only a third-party data provider may serve this URL (such as a LinkedIn profile), and the request sets an option the provider can't honor: `actions`, `profile`, `minAge`, `zeroDataRetention`, `lockdown`, `redactPII`, or an unsupported format such as `screenshot` or `branding`. `error` names the option. The response has this value in `code`. | Send the request without that option. If your team's policy enforces zero data retention, these URLs can't be served. See [Provider-routed URLs](/features/scrape#provider-routed-urls). | No |
| 401 | `Unauthorized: Invalid token` | API key is missing, malformed, or revoked. | Send `Authorization: Bearer fc-...` with a valid key from the [dashboard](https://www.firecrawl.dev/app/api-keys). | No |
| 402 | `Payment Required: Insufficient credits` | Plan credits are exhausted or billing is not configured. | Turn on pay-as-you-go, or upgrade your plan. | No |
| 403 | `Forbidden` | Key lacks permission for this endpoint or feature. | Use a key with the required scope, or upgrade the plan that gates this feature. | No |
| 403 | `SCRAPE_PROMPT_INJECTION_DETECTED` | The `checkPromptInjection` option detected a prompt injection attempt in the scraped page content, so the scrape was aborted. | Inspect the page content manually. If it is a false positive, retry without `checkPromptInjection`. See [Prompt injection detection](/features/llm-extract#prompt-injection-detection). | No |
| 403 | `THIRD_PARTY_DATA_NOT_ENABLED` | The third-party data provider for this URL is not enabled for your organization, for example because an org admin turned it off. The response has this value in `code`. | Ask an org admin to turn the provider on from its [Alexandria](/features/alexandria) page, or remove it from your enrichment providers. | After it is enabled |
| 403 | `THIRD_PARTY_DATA_ENRICHMENT_NOT_ENABLED` | The URL is a LinkedIn profile or company page, but enrichment is off for that kind of profile, or none of your saved enrichment providers can serve it. The response has this value in `code`, and `error` links to the enrichment settings. | Ask an org admin to turn on enrichment and choose providers in the enrichment settings. See [Provider-routed URLs](/features/scrape#provider-routed-urls). | After setup |
| 403 | `We apologize for the inconvenience but we do not support this site...` / `UNSUPPORTED_SITE` | Firecrawl does not scrape this site, and no third-party data provider serves the URL. Some responses also have `UNSUPPORTED_SITE` in `code`. | Use a different source for this data. Enterprise customers can contact sales about the site. | No |
| 403 | `THIRD_PARTY_DATA_TERMS_REQUIRED` | An [Alexandria](/features/alexandria) provider needs your organization to accept its terms before the request can run. The provider did not run. The response has this value in `code`, and includes `requiresAction.url`. | Send `requiresAction.url` to an org admin, who reviews and accepts the terms there. Agents must not accept terms on their own. After acceptance, send the same request again. | After acceptance |
| 404 | `Not Found` | The job ID, resource, or endpoint path does not exist. | Verify the resource ID and endpoint URL. | No |
| 404 | `THIRD_PARTY_DATA_NOT_FOUND` | The URL is served by third-party data providers, and none of them has a record for it. With several enrichment providers, every one was tried. A provider with no record charges nothing. The response has this value in `code`. | Check the URL points to an existing profile or company page. Adding more enrichment providers can raise coverage. | No |
| 408 | `Request Timeout` | The page took longer than the request `timeout` to load. | Increase `timeout`, simplify actions, or use `fastMode`. | Yes, with backoff |
| 409 | `Conflict` | Resource is in a state that prevents the operation (e.g. already deleted). | Re-fetch state and reconcile before retrying. | No |
| 413 | `Payload Too Large` | Request body exceeded the maximum allowed size. | Reduce the payload (e.g. shorter schema, fewer URLs per batch). | No |
| 422 | `Unprocessable Entity` / extraction schema error | Schema is invalid JSON Schema, or the model could not produce a conforming result. | Validate the schema; loosen required fields; try a different `model`. | Sometimes |
| 429 | `Rate limit exceeded` | Too many requests for your plan's per-minute limit. | Back off and retry after `Retry-After` seconds. See [Rate Limits](/rate-limits). | Yes, with backoff |
| 429 | `Concurrency limit reached` | Concurrent browser limit for your plan reached. | Wait for in-flight jobs to finish, lower concurrency, or upgrade your plan. | Yes, with backoff |
| 500 | `Internal Server Error` | Unhandled server-side failure. | Retry with exponential backoff. If it persists, contact support with the request ID. | Yes, with backoff |
| 502 | `Bad Gateway` | Upstream proxy or worker returned an invalid response. | Retry with backoff. | Yes, with backoff |
| 503 | `Service Unavailable` | Service temporarily unable to handle the request. | Retry with backoff. | Yes, with backoff |
| 504 | `Gateway Timeout` | Request exceeded the gateway's timeout (typically long crawls). | Use the async crawl/batch endpoints and poll status instead. | Yes, with backoff |
For 429 responses, Firecrawl includes a `Retry-After` header (in seconds) when available — wait at least that long before retrying.
## Agent
Errors specific to [`/agent`](/features/agent) and its status, trace, snapshot, and cancel endpoints. The trace and snapshot endpoints relay their upstream error body unchanged, so those two can answer with a body that omits the `success` field described above; match on the HTTP status and the `error` string.
| HTTP | `error` (typical message) | Cause | Remedy | Retryable |
| - | - | - | - | - |
| 400 | `Invalid job ID format. Job ID must be a valid UUID.` | The `jobId` path segment is not a UUID. | Pass the `id` returned by `POST /v2/agent`. | No |
| 400 | `Invalid snapshot ID` | The `snapshotId` path segment is malformed. | Use a `snapshotId` taken from an `artifact.updated` [trace event](/api-reference/endpoint/agent-trace). | No |
| 400 | `Trace is only available for Spark 2 extracts` | The job predates Spark 2, which is what records traces. | Nothing to do for that job. Every new run executes on `spark-2` and has a trace. | No |
| 400 | `Snapshots are only available for Spark 2 extracts` | The job predates Spark 2, which is what records snapshots. | Nothing to do for that job. Every new run executes on `spark-2` and has snapshots. | No |
| 400 | `Zero Data Retention (ZDR) for agent runs requires both scrape ZDR and search ZDR to be enabled for your team.` (`code: "zdr_not_enabled"`) | The request sets `zeroDataRetention: true`, or the team has ZDR forced on, but the team does not have both Scrape ZDR and Search ZDR enabled. | Contact [support@firecrawl.com](mailto:support@firecrawl.com) to enable it. See [Agent ZDR](/features/agent#zero-data-retention-zdr). | No |
| 400 | `Agent threads are not supported with zero data retention.` (`code: "zdr_threads_unsupported"`) | A ZDR run sets `threadId`. | Remove `threadId` to start a new run. | No |
| 404 | `Agent job not found` | The job ID does not exist, or belongs to another team. | Check the job ID, and use a key from the team that started the run. | No |
| 404 | `Snapshot not found` | No snapshot with that ID belongs to this job. | Re-fetch the trace and use a current `snapshotId` from an `artifact.updated` [trace event](/api-reference/endpoint/agent-trace). | No |
| 409 | `Agent already finished` | Cancel was called on a run that had already reached a terminal state. | Poll `GET /v2/agent/{jobId}` for the outcome instead. | No |
| 409 | `Agent is already cancelled` | Cancel was called on a run that was already cancelling. | Poll `GET /v2/agent/{jobId}`. A cancelled run reports `failed` with a cancellation message. | No |
| 410 | `code: "zdr_expired"` | The run used Zero Data Retention and its result was deleted after the 24-hour retrieval window. | Nothing to do for that run. Retrieve ZDR results within 24 hours. | No |
| 500 | `Failed to passthrough agent request.` | The agent service rejected the job at submission. | Retry with backoff. If it persists, contact support with the request ID. | Yes, with backoff |
A run that hits its `maxCredits` limit does not return an HTTP error. It finishes as a failed job. Poll the status endpoint and you get `status: "failed"` with `stopReason: "credit_limit_reached"`, a credit-limit error message, no `data`, and `creditsUsed: 0`, since failed runs are not billed. The response may also include a best-effort `partial`. Check `stopReason` rather than matching the error text, and see [Handling credit-limit stops](/features/agent#handling-credit-limit-stops) for how to use a partial and continue the run. In the trace, the same outcome appears as a `run.finished` event with `outcome: "credit_limit_reached"`.
### Trace error codes
Terminal and `error.occurred` trace events carry a structured `error` object whose `code` is one of five values. Each also carries a `retryable` boolean, which you should treat the same way as the **Retryable** column above.
| `code` | Meaning and remedy |
| - | - |
| `cancelled` | You cancelled the run. Start a new one when you want the work redone. |
| `credit_limit_reached` | The run hit its `maxCredits` ceiling. Raise `maxCredits`, or narrow the prompt so the run needs less work. |
| `parent_finished` | A subagent stopped because the agent that spawned it finished first. Read the parent agent's own terminal event for the real cause. |
| `refused` | The agent declined the task. Rephrase the prompt, or scope it to URLs you're authorized to collect from. |
| `internal` | An unexpected failure inside the run. Retry the run; if it persists, contact support with the job ID. |
## Retry guidance
Treat the **Retryable** column as authoritative; do not infer from the HTTP status alone. The pattern below uses exponential backoff with jitter and respects `Retry-After` on 429.
```python Python theme={null}
import time
import random
import requests
RETRYABLE_STATUSES = {408, 429, 500, 502, 503, 504}
def request_with_retry(method, url, headers=None, json=None, max_attempts=5):
for attempt in range(max_attempts):
resp = requests.request(method, url, headers=headers, json=json)
if resp.status_code < 400 or resp.status_code not in RETRYABLE_STATUSES:
return resp
# Honor Retry-After when present, otherwise exponential backoff with jitter.
retry_after = resp.headers.get("Retry-After")
delay = float(retry_after) if retry_after else min(2 ** attempt, 30) + random.random()
time.sleep(delay)
return resp
```
```js Node theme={null}
const RETRYABLE_STATUSES = new Set([408, 429, 500, 502, 503, 504]);
async function requestWithRetry(url, init = {}, maxAttempts = 5) {
for (let attempt = 0; attempt < maxAttempts; attempt++) {
const resp = await fetch(url, init);
if (resp.ok || !RETRYABLE_STATUSES.has(resp.status)) return resp;
// Honor Retry-After when present, otherwise exponential backoff with jitter.
const retryAfter = resp.headers.get('Retry-After');
const delayMs = retryAfter
? Number(retryAfter) * 1000
: Math.min(2 ** attempt, 30) * 1000 + Math.random() * 1000;
await new Promise((r) => setTimeout(r, delayMs));
}
}
```
```bash cURL theme={null}
# Simple shell loop with exponential backoff for retryable statuses.
attempt=0
max=5
until response=$(curl -sS -w "\n%{http_code}" -X POST "https://api.firecrawl.dev/v2/scrape" \
-H "Authorization: Bearer $FIRECRAWL_API_KEY" \
-H "Content-Type: application/json" \
-d '{"url":"https://example.com"}'); do
status=$(printf '%s' "$response" | tail -n1)
case "$status" in
408|429|500|502|503|504)
attempt=$((attempt+1))
[ "$attempt" -ge "$max" ] && break
sleep $((2 ** attempt))
;;
*) break ;;
esac
done
echo "$response"
```
## 429 responses
429 responses are the most common retryable error. Per-plan rate limits and concurrency limits are documented in [Rate Limits](/rate-limits). Always honor the `Retry-After` header when present rather than retrying immediately.
# Introduction
Source: https://docs.firecrawl.dev/api-reference/v2-introduction
Firecrawl API Reference (v2)
> [!NOTE]
>
> **For AI agents:** Use [llms.txt](/llms.txt) for a full index of all documentation.
The Firecrawl API gives you programmatic access to web data. All endpoints share a common base URL, authentication scheme, and response format described on this page.
## Features
> [card] [Search](/api-reference/endpoint/search)
>
> Search the web and get full page content in any format.
> [card] [Scrape](/api-reference/endpoint/scrape)
>
> Extract content from any webpage in markdown or json format.
> [card] [Interact](/api-reference/endpoint/browser-create)
>
> Create an Interact session to click, fill forms, and navigate pages.
> [card] [Parse](/api-reference/endpoint/parse)
>
> Upload files and parse them into markdown or other formats.
> [card] [Monitor](/api-reference/endpoint/monitor-create)
>
> Schedule recurring checks and get notified when content changes.
> [card] [Crawl](/api-reference/endpoint/crawl-post)
>
> Crawl entire websites and get content from all pages.
> [card] [Map](/api-reference/endpoint/map)
>
> Get a complete list of URLs from any website quickly and reliably.
> [card] [Agent](/api-reference/endpoint/agent)
>
> Autonomous web data gathering powered by AI.
> [card] [Alexandria](/features/alexandria)
>
> Find and run structured data tools from third-party providers.
## Base URL
All requests use the following base URL:
```bash theme={null}
https://api.firecrawl.dev
```
## Authentication
Requests need an `Authorization` header with your API key, except on the keyless endpoints described below:
```bash theme={null}
Authorization: Bearer fc-YOUR-API-KEY
```
You can find your API key in the [Firecrawl dashboard](https://www.firecrawl.dev/app/api-keys).
A few endpoints, including `/v2/scrape`, `/v2/search` and `/v2/parse`, also work without a key, with limits. To call them keyless, leave the `Authorization` header out entirely, because a header with an empty token returns `401`. See [No API key (keyless)](/authentication#no-api-key-keyless) for the full list.
To let users connect their own Firecrawl account to your app instead, use [OAuth for apps](/oauth). [Authentication](/authentication) compares every option.
If you are an agent without an API key, start with [Get credentials](/ai-onboarding#get-credentials). If your platform supports WorkOS ID-JAG, use [`auth.md`](https://www.firecrawl.dev/auth.md) for registration instructions.
```bash cURL theme={null}
curl -X POST "https://api.firecrawl.dev/v2/scrape" \
-H "Authorization: Bearer fc-YOUR-API-KEY" \
-H "Content-Type: application/json" \
-d '{"url": "https://example.com"}'
```
```python Python theme={null}
from firecrawl import Firecrawl
firecrawl = Firecrawl(api_key="fc-YOUR-API-KEY")
result = firecrawl.scrape("https://example.com")
```
```js Node theme={null}
import { Firecrawl } from 'firecrawl';
const firecrawl = new Firecrawl({ apiKey: "fc-YOUR-API-KEY" });
const result = await firecrawl.scrape('https://example.com');
```
## Response codes
Firecrawl uses conventional HTTP status codes to indicate the outcome of your requests. Codes in the `2xx` range indicate success, `4xx` codes indicate client errors, and `5xx` codes indicate server errors.
See [Errors](/api-reference/errors) for the full reference, including the `error` string returned for each failure mode, retry guidance, and a copy-pasteable backoff snippet.
## 429 responses
When you exceed your plan's rate or concurrency limits, the API returns a `429` status code. See [Rate Limits](/rate-limits) for per-plan limits and [Errors](/api-reference/errors) for retry guidance.
# Contributor setup for Firecrawl
Source: https://docs.firecrawl.dev/contributing/guide
Set up the Firecrawl API development environment, verify a local scrape, and run the source-owned test harness before contributing.
Run Firecrawl locally when you are changing the API, workers, or tests. This path installs development dependencies and starts source-owned services with the API harness.
> [!WARNING]
>
> This is a contributor development environment, not a deployment guide. If
> you want to run Firecrawl on infrastructure you control without changing the
> product, use [Self-hosting Firecrawl](/contributing/self-host).
## Choose local development or self-hosting
* **Develop locally** when you need fast code-test-debug loops against the current source revision.
* **Self-host a pinned release** when you want a stable Docker Compose baseline on your own infrastructure.
* **Use Firecrawl Cloud** when you want the fastest managed path without operating either environment.
Keep these environments separate. The API development file at `apps/api/.env` and the root Compose `.env` serve different processes and are not interchangeable.
## Start the Firecrawl development environment
### Install the prerequisites
Install:
* [Git](https://git-scm.com/downloads)
* Node.js 22
* pnpm `11.4.0`
* [Redis](https://redis.io/docs/latest/operate/oss_and_stack/install/install-redis/)
* Docker or Podman for the PostgreSQL and RabbitMQ containers managed by the API harness
* [Go](https://go.dev/dl/) 1.23 or newer, rebuilt by the API harness on every start
* [Rust](https://www.rust-lang.org/tools/install), built during `pnpm install` for the `@mendable/firecrawl-rs` native package
Enable the package manager version used by the API:
```bash theme={null}
corepack enable
corepack prepare pnpm@11.4.0 --activate
```
### Clone Firecrawl and install dependencies
```bash theme={null}
git clone https://github.com/firecrawl/firecrawl.git
cd firecrawl/apps/api
pnpm install
```
Create `apps/api/.env` with the smallest unauthenticated development configuration:
```bash theme={null}
cat > .env <<'EOF'
PORT=3002
HOST=0.0.0.0
REDIS_URL=redis://localhost:6379
REDIS_RATE_LIMIT_URL=redis://localhost:6379
USE_DB_AUTHENTICATION=false
PLAYWRIGHT_MICROSERVICE_URL=
EOF
```
Leave `NUQ_DATABASE_URL` and `NUQ_RABBITMQ_URL` unset when you want the harness to create local PostgreSQL and RabbitMQ containers. Set them only when you intentionally operate those dependencies yourself.
### Start Redis and Firecrawl
Start Redis in one terminal:
```bash theme={null}
redis-server
```
Then start Firecrawl from `apps/api` in another terminal:
```bash theme={null}
pnpm start
```
The start command builds the API, launches the API and worker processes, and manages the local queue containers. Keep that terminal open while you develop.
### Verify one local scrape
Check that the API process responds:
```bash theme={null}
curl \
--fail \
--silent \
--show-error \
http://localhost:3002/v0/health/readiness
```
Expected response:
```json theme={null}
{"status":"ok"}
```
Then exercise the scraping path:
```bash theme={null}
curl \
--fail-with-body \
--silent \
--show-error \
--max-time 75 \
-X POST \
http://localhost:3002/v2/scrape \
-H 'Content-Type: application/json' \
-d '{
"url": "https://example.com",
"formats": ["markdown"],
"timeout": 60000
}'
```
A successful response includes `success: true`, Markdown in `data.markdown`, and an HTTP status in `data.metadata.statusCode`.
## Change and test Firecrawl
Keep each change focused, add a successful path and relevant failure coverage, and run the narrowest source-owned test command that proves the behavior.
From `apps/api`, run the API snippet suite with its dependencies:
```bash theme={null}
pnpm harness pnpm test:snips
```
The harness starts the API, workers, PostgreSQL, and RabbitMQ for the test command, then cleans up the processes it started. Use a more targeted Vitest path when the full snippet suite is unnecessary.
For the contribution workflow, review the repository's [`CONTRIBUTING.md`](https://github.com/firecrawl/firecrawl/blob/main/CONTRIBUTING.md) before opening a pull request.
## Troubleshoot the development environment
### Redis does not connect
Confirm Redis is listening on `localhost:6379` and that both Redis URLs in `apps/api/.env` use that address.
### The harness cannot start PostgreSQL or RabbitMQ
Start Docker or Podman, then rerun `pnpm start`. If you manage the services yourself, set their connection URLs explicitly instead of relying on harness-managed containers.
### Port 3002 is already in use
Stop the other process or change `PORT` in `apps/api/.env`, then use the same port in your verification requests.
### Basic fetch works but browser rendering does not
An empty `PLAYWRIGHT_MICROSERVICE_URL` leaves the separate Playwright service disabled. Start and configure that service only when the change you are testing requires it.
## Where to go next
* **Deploying instead of developing?** Follow [Self-hosting Firecrawl](/contributing/self-host).
* **Still choosing a path?** Compare [Open source or Firecrawl Cloud](/contributing/open-source-or-cloud).
* **Ready to contribute?** Use the source-owned [contribution guide](https://github.com/firecrawl/firecrawl/blob/main/CONTRIBUTING.md).
# Open source or Firecrawl Cloud
Source: https://docs.firecrawl.dev/contributing/open-source-or-cloud
Choose between self-hosting Firecrawl for infrastructure control and Firecrawl Cloud for the fastest managed path to production.
Choose open source when you need source or infrastructure control. Choose Firecrawl Cloud when you want to start scraping without operating the stack. Both paths expose Firecrawl's core APIs; the difference is who configures, secures, and runs the supporting services.
> [!NOTE]
>
> Running Firecrawl for product development and operating a self-hosted
> deployment are different jobs. Use [Contributor Setup](/contributing/guide)
> when you are changing Firecrawl code. Use the [self-hosting
> guide](/contributing/self-host) when you want an API running on infrastructure
> you control.
## Choose your Firecrawl deployment
### Use open source when
* **You need control over source or infrastructure.** You can inspect the code, choose where the stack runs, and connect your own providers.
* **You are prepared to operate it.** Your team owns authentication, TLS, persistence, monitoring, capacity, upgrades, and recovery.
* **You can add capabilities deliberately.** Core scraping works in the default stack; LLM-backed formats, advanced scraping services, and specialized extraction paths need additional configuration.
### Use Firecrawl Cloud when
* **You want the fastest supported path to production.** Firecrawl operates the infrastructure and managed services.
* **You need Cloud-only product surfaces.** Agent, Browser, managed dashboards, enhanced proxy paths, and enterprise controls are delivered through Cloud.
* **You want one account for usage and support.** API keys, credits, limits, and operational support stay in the managed service.
**Our recommendation:** start with Firecrawl Cloud unless source access or infrastructure control is worth the operational work. If you self-host, prove one scrape first and add services only when your use case requires them.
## Compare the operating model
| Decision | Open source | Firecrawl Cloud |
| - | - | - |
| Core scrape, crawl, map, and search APIs | Included | Included and managed |
| Fetch and Playwright processing | Included in the default stack | Managed |
| LLM-backed extraction and formats | Connect an OpenAI-compatible provider or Ollama | Managed provider path |
| Advanced anti-bot or specialized extraction services | Run and configure the required service separately | Managed where the Cloud product supports it |
| Agent, Browser, Interact, dashboard, and enterprise controls | Not included in the default stack | Included by product and plan availability |
| Security, persistence, availability, and upgrades | You own them | Firecrawl operates them |
| Usage, limits, and billing | Your infrastructure and provider costs | Firecrawl plan and credit model |

## Start with the path you chose
* **Self-host Firecrawl:** follow the [Docker Compose self-hosting guide](/contributing/self-host) from a pinned release to one verified scrape.
* **Change Firecrawl code:** use [Contributor Setup](/contributing/guide) for the development environment.
* **Use Firecrawl Cloud:** [create an account](https://firecrawl.dev) and follow the [quickstart](/quickstart).
Open source keeps the core engine inspectable and adaptable. Firecrawl Cloud funds that work while giving builders a managed path with additional product and infrastructure capabilities.
# Self-hosting Firecrawl
Source: https://docs.firecrawl.dev/contributing/self-host
Self-host Firecrawl with Docker Compose, verify a local scrape, understand open-source limits, and prepare the stack for production.
Self-host Firecrawl with Docker Compose when you need source or infrastructure control. This guide pins release `v2.11.162`, starts the API at `http://localhost:3002`, and verifies a successful `POST /v2/scrape` response with Markdown.
> [!WARNING]
>
> This trusted-network quickstart disables API authentication and is not a
> production architecture. It starts without durable storage, TLS, high
> availability, or every Firecrawl Cloud capability.
## Choose self-hosting or Firecrawl Cloud
### Self-host Firecrawl when
* **You want control over the source or infrastructure.** This guide gets the API and its supporting services running on your machine.
* **You are comfortable operating the stack.** You will own upgrades, security, storage, monitoring, and recovery.
* **You want to validate Firecrawl against your environment.** Get the baseline working here, then design the controls in [Before production](#before-production).
Choose [Firecrawl Cloud](https://firecrawl.dev) when you want to start scraping without running infrastructure. See [Open Source vs Cloud](/contributing/open-source-or-cloud) for the capability differences.
**Our recommendation:** self-host when source access or infrastructure control is worth the operational work. If you want the fastest supported path to production, start with Firecrawl Cloud.
### What self-hosting requires
* You own upgrades, secrets, storage, monitoring, recovery, and incident response.
* Scraping still sends outbound requests to target websites. Optional proxy, parsing, or AI providers add more data flows.
* This guide keeps the first run intentionally simple. Get one scrape working, then change one decision at a time.
* The commands are pinned to `v2.11.162`. A different release may use a different Compose contract.
## Self-host Firecrawl with Docker Compose
### Start with these defaults
* **Release: Firecrawl `v2.11.162`.** Pin the code and configuration first. Upgrade after reviewing the target release's `docker-compose.yaml` and self-hosting notes.
* **API authentication: off for this local run.** Add it only with a complete supported identity and database design; one environment variable is not enough.
* **Queue: PostgreSQL.** Keep it unless you intentionally want to operate the optional FoundationDB backend.
* **Queue admin UI: off.** Enable it only with a strong `BULL_AUTH_KEY` and network controls.
* **AI and advanced scraping providers: not configured.** Add a provider when a capability you need requires it.
Keep the first run boring: get one scrape working, then add what your use case needs.
### Prerequisites
Before you start, install:
* [Git](https://git-scm.com/downloads)
* [Docker Engine](https://docs.docker.com/engine/install/) or Docker Desktop
* Docker Compose v2, invoked as `docker compose`
* `curl` for the verification requests
Make sure port `3002` is available and Docker has enough capacity to build and run several services. Firecrawl does not publish a verified minimum host size for this stack.
### Clone the verified release
This guide was verified against Firecrawl `v2.11.162`. Check out that exact release to keep the code, commands, and configuration in sync:
```bash theme={null}
git clone https://github.com/firecrawl/firecrawl.git
cd firecrawl
git checkout v2.11.162
```
Want to use another release? Review its `docker-compose.yaml` and self-hosting notes before reusing these values.
### Configure the evaluation deployment
Create the smallest working `.env` in the repository root:
```bash theme={null}
cat > .env <<'EOF'
USE_DB_AUTHENTICATION=false
POSTGRES_USER=postgres
POSTGRES_PASSWORD=replace-with-at-least-32-random-characters
POSTGRES_DB=postgres
EOF
```
Replace the PostgreSQL password before starting the stack, and do not commit `.env`. Keep `POSTGRES_DB=postgres` for `v2.11.162` because the bundled `pg_cron` configuration targets that database. Compose passes these values to both the API and PostgreSQL service.
> [!NOTE]
>
> `apps/api/.env.example` is for API development, not a drop-in Compose file.
> This first run disables database authentication, so requests do not need an
> API key or `Authorization` header.
Leave `NUQ_BACKEND` and `BULL_AUTH_KEY` unset. You will use the PostgreSQL queue without running the queue administration UI—fewer moving parts for the first scrape.
### Build and start Firecrawl
Build the checked-out source and start everything in the background:
```bash theme={null}
docker compose up --build -d
docker compose ps --all
```
Warnings about unset optional variables are expected for this baseline. `docker compose ps --all` should show the API and supporting services running, with one-shot initialization services completed. Give the stack a little time if services are still starting.
### Check API reachability
First, make sure the API can answer an HTTP request:
```bash theme={null}
curl \
--fail \
--silent \
--show-error \
--max-time 5 \
http://localhost:3002/v0/health/readiness
```
Expected response:
```json theme={null}
{"status":"ok"}
```
> [!WARNING]
>
> This is a heartbeat, not an end-to-end test. It does not check Redis,
> PostgreSQL, RabbitMQ, Playwright, workers, or outbound network access. Run the
> scrape below before treating the deployment as usable.
### Run a functional smoke test
Now test the path that matters: one real scrape. The request timeout is in milliseconds; curl's client timeout is in seconds and is slightly longer:
```bash theme={null}
curl \
--fail-with-body \
--silent \
--show-error \
--max-time 75 \
-X POST \
http://localhost:3002/v2/scrape \
-H 'Content-Type: application/json' \
-d '{
"url": "https://example.com",
"formats": ["markdown"],
"timeout": 60000
}'
```
A successful response has this shape:
```json theme={null}
{
"success": true,
"data": {
"markdown": "...",
"metadata": {
"statusCode": 200
}
}
}
```
This checks the API, scraping pipeline, one scraping-engine path, and outbound access together. Exact metadata can vary with the target response.
If you get these success fields, Firecrawl is working end to end on your infrastructure. Keep this baseline, then choose what to add next.
## Self-hosted feature support
Your first scrape works. Add the next capability because you need it, not because it exists:
| If you need | Decision |
| - | - |
| Core scrape, crawl, map, and search routes | Keep the default stack. Fetch and Playwright processing are included. |
| LLM-backed extraction or formats | Connect an OpenAI-compatible provider or Ollama, then test that path separately. |
| Fire-engine or its advanced anti-bot behavior | Run and configure that service separately; it is not included. |
| Screenshots or page actions | Not available in the default stack. Fetch and Playwright both report no support; both require Fire-engine. |
| Agent, Browser, interact, feedback, or specialized product, menu, audio, and video formats | Use Firecrawl Cloud, or verify the external service requirements for the specific capability. |
For the broader product comparison, see [Open Source vs Cloud](/contributing/open-source-or-cloud). For release-specific configuration, use the pinned [`docker-compose.yaml`](https://github.com/firecrawl/firecrawl/blob/v2.11.162/docker-compose.yaml) as the companion source.
## Before production
Compose gets you to first success. Production needs a few explicit choices before the API leaves a trusted network:
* **If data must survive service replacement,** add durable storage for PostgreSQL, Redis, and RabbitMQ, then define and test backup and restore procedures. The provided Compose file does not add those volumes.
* **If users or untrusted networks can reach the API,** add a supported authentication design, network access controls, and TLS at a reverse proxy or ingress. Do not expose this unauthenticated baseline publicly.
* **If you have availability or capacity requirements,** set uptime targets, monitoring, resource sizing, scaling triggers, and upgrade and rollback procedures. The Compose limits are not verified minimum requirements.
* **If data location or compliance matters,** map requests to target websites and every optional AI, proxy, or parsing provider before enabling them.
* **If secrets must be managed centrally,** move the database password out of `.env` and into your platform's secret-management system.
* **If you enable admin routes with `BULL_AUTH_KEY`,** call them under `/admin/ops/` with an `Authorization: Bearer` header, set `BULL_AUTH_KEY_PREVIOUS` while callers move to a new key, and set `BULL_AUTH_KEY_PATH_ROUTES=false` once nothing uses the `/admin//...` paths. To reach the queue UI, metrics, and diagnostic routes without a key, set `ADMIN_INTERNAL_PORT` and keep that port private. See [`SELF_HOST.md`](https://github.com/firecrawl/firecrawl/blob/main/SELF_HOST.md#admin-routes) for the full list.
These are infrastructure decisions. No single `.env` switch makes the stack production-ready.
## Where to go next
* **Still evaluating?** Keep the API on a trusted network and run `docker compose down` when you are finished.
* **Adding an open-source capability?** Use [Self-hosted feature support](#self-hosted-feature-support) to find the required provider or service, then test that path on its own.
* **Changing Firecrawl code?** Switch to [Contributor Setup](/contributing/guide) for the development environment.
* **Connecting a client?** Point the [Firecrawl CLI](/sdks/cli#connect-the-cli-to-self-hosted-firecrawl) or [local MCP server](/mcp-server/local#connect-mcp-to-self-hosted-firecrawl) at your verified API URL.
* **Moving to Kubernetes?** Start with the versioned Kubernetes or Helm references linked from [`SELF_HOST.md`](https://github.com/firecrawl/firecrawl/blob/main/SELF_HOST.md), then make the production decisions above explicit for your platform.
* **Want managed infrastructure or Cloud-only capabilities?** Compare [Open Source vs Cloud](/contributing/open-source-or-cloud).
* **Going to production?** Complete every decision in [Before production](#before-production) before exposing the API.
## Troubleshooting
### You're bypassing authentication
If you see this warning with `USE_DB_AUTHENTICATION=false`, you are on the expected first-run path. Requests use a self-hosted identity and need no API key. If the API is reachable from an untrusted network, stop and add the controls in [Before production](#before-production).
### Docker containers fail to start
If any long-running service exits, inspect container state and recent logs:
```bash theme={null}
docker compose ps --all
docker compose logs --tail=200
```
* If the source revision differs, either check out `v2.11.162` or use that release's configuration.
* If a build or container is resource-constrained, increase Docker CPU, memory, or disk capacity.
* If PostgreSQL fails, check `.env` syntax, keep `POSTGRES_DB=postgres`, and make sure the user and password values are consistent.
### Connection issues with Redis
If a container cannot connect to Redis, keep the Compose service address `redis://redis:6379`. `localhost` points back to that container, not the Redis service.
```bash theme={null}
docker compose ps redis
docker compose logs --tail=100 redis
```
If you added `REDIS_URL` or `REDIS_RATE_LIMIT_URL`, remove the override to restore the default or use an address that resolves from inside the Compose network.
### API endpoint does not respond
If port `3002` does not respond, check the API container and its logs:
```bash theme={null}
docker compose ps api
docker compose logs --tail=200 api
```
If another process owns port `3002`, stop it or change the published port consistently. During initial startup, retry only after the API container reports as running.
If `/v0/health/readiness` succeeds but `/v2/scrape` fails, inspect the API and Playwright logs because the reachability endpoint does not validate those dependencies:
```bash theme={null}
docker compose logs --tail=200 api playwright-service
```
### Scrape request times out
If the scrape times out, confirm the deployment can reach `https://example.com` and that the API and Playwright services are running. Keep curl's `--max-time` longer than the request body's `timeout` so the API can return its own timeout response.
# Overview
Source: https://docs.firecrawl.dev/dashboard
Overview of the Firecrawl dashboard and its key features
The [Firecrawl dashboard](https://www.firecrawl.dev/app) is where you manage your account, test endpoints, and monitor usage. Below is a quick tour of each section.
## Playground
The playground lets you try Firecrawl endpoints directly in the browser before integrating them into your code.
* **[Scrape](https://www.firecrawl.dev/app/playground?endpoint=scrape)**: Extract content from a single page.
* **[Search](https://www.firecrawl.dev/app/playground?endpoint=search)**: Search the web and get scraped results.
* **[Crawl](https://www.firecrawl.dev/app/playground?endpoint=crawl)**: Crawl an entire website and extract content from every page.
* **[Map](https://www.firecrawl.dev/app/playground?endpoint=map)**: Discover all URLs on a website.
## Browser
[Interact with the web](https://www.firecrawl.dev/app/browser) through a live browser session. You can create persistent profiles, run actions, and take screenshots. This is useful for pages that require authentication or complex interaction.
## Agent
The [Agent](https://www.firecrawl.dev/app/agent) is an AI-powered research tool that can autonomously browse the web, follow links, and extract structured data based on a prompt.
## Activity Logs
[Activity Logs](https://www.firecrawl.dev/app/logs) show a history of your recent API requests, including status, duration, and credits consumed.
Rows that failed or finished with errors carry a sparkles **Debug issue** button in the Actions column. It runs Firecrawl's support agent against that job and returns a diagnosis with a suggested fix you can copy. See [Debug with Ask](/features/ask#debug-from-activity-logs).
## Usage
The [Usage](https://www.firecrawl.dev/app/usage) page shows your credit consumption over time and current billing-cycle totals.
## API Keys
From the [API Keys](https://www.firecrawl.dev/app/api-keys) page you can create, view, and revoke API keys for your team. Your account must always have at least one active API key, so to revoke a key you will need to create a new one first.
## Settings
The [Settings](https://www.firecrawl.dev/app/settings) page has three tabs:
* **Team**: Invite members, assign roles, and manage your team. See [Team management & roles](#team-management--roles) below.
* **Billing**: View your current plan and invoices, set your monthly pay-as-you-go limit, and apply coupons. See also [Billing](/billing).
* **Advanced**: Webhook signing secret and team deletion.
***
## Team management & roles
Firecrawl lets you invite teammates to collaborate under a shared account. From the **Team** tab in Settings you can invite members, assign roles, and manage your team.
### Roles
Every team member is assigned one of two roles: **Admin** or **Member**. You choose the role when sending an invitation.
| Capability | Admin | Member |
| - | :-: | :-: |
| **General** | | |
| Use the team's API keys and shared resources | ✓ | ✓ |
| **Team management** | | |
| View the team member list | ✓ | ✓ |
| Leave the team | ✓ | ✓ |
| Invite new team members | ✓ | ✗ |
| Remove team members | ✓ | ✗ |
| Change a member's role | ✓ | ✗ |
| Revoke pending invitations | ✓ | ✗ |
| Edit the team name | ✓ | ✗ |
| **Billing** | | |
| View invoices and usage | ✓ | ✗ |
| Apply credit coupons | ✓ | ✗ |
| Manage subscription and billing portal | ✓ | ✗ |
| **Settings** | | |
| View the webhook signing secret | ✓ | ✓ |
| Regenerate the webhook signing secret | ✓ | ✗ |
| Delete the team | ✓ | ✗ |
In short, **Admins** have full control over team management, billing, and settings, while **Members** can use the team's resources and view usage on the Usage page but cannot access the Billing tab or modify the team.
# Debug Firecrawl with Ask
Source: https://docs.firecrawl.dev/features/ask
Debug a failed job or any Firecrawl integration issue with an agentic support API
Firecrawl `/support/ask` is an AI support agent exposed as an API. Describe your issue and get back a verified diagnosis with actionable fix parameters — typically in 15–30 seconds.
**Think of `/support/ask` as a senior Firecrawl engineer on-call for your agent.**
> [!NOTE]
>
> The Ask API is designed primarily for **AI agent callers**. If you're building agents that use Firecrawl for scraping, crawling, or data extraction, wire `/support/ask` into your error-handling flow for autonomous issue resolution.
## Endpoint
| Endpoint | Auth | Who it's for | What it does |
| - | - | - | - |
| `POST /support/ask` | Your Firecrawl API key | Your agents and apps | Full diagnostic loop scoped to your team |
## Quick start
### Debug a failing crawl
```bash theme={null}
curl -X POST https://api.firecrawl.dev/v2/support/ask \
-H "Authorization: Bearer fc-YOUR_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"question": "my crawl returned 3 pages but I expected 50"
}'
```
## Debug a failed job
Every Firecrawl job — scrape, crawl, batch scrape, search, map, or extract — can be debugged with `/support/ask`. Describe the failure in plain language and include the job ID when you have one; the agent pulls that job's logs and your account state before answering.
```bash theme={null}
curl -X POST https://api.firecrawl.dev/v2/support/ask \
-H "Authorization: Bearer fc-YOUR_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"question": "debug failed job 0f8c9a1b-4e2d-47a1-9c3f-1b2d3e4f5a6b — crawl of https://example.com failed after 12 pages",
"rationale": "user needs the full docs site indexed before their demo"
}'
```
Include as much of this as you have — each piece narrows the diagnosis:
| Detail | Why it helps |
| - | - |
| Job ID | Lets the agent read that job's logs, status, and per-page results directly |
| Target URL | Surfaces site-specific blockers like bot protection, JS rendering, or robots rules |
| Error message or status code | Separates rate limits and credit exhaustion from scrape-level failures |
| What you expected | Distinguishes a hard failure from a job that "succeeded" with missing content |
| `rationale` | Tells the agent what the end user is after so it prioritizes the right evidence |
### What Ask checks for common failures
| Symptom | What the agent investigates |
| - | - |
| Job status `failed` | Job logs, upstream HTTP status, proxy and retry history |
| Crawl returned fewer pages than expected | `limit`, `maxDiscoveryDepth`, `includePaths`/`excludePaths`, sitemap coverage, robots rules |
| Empty or truncated markdown | Client-side rendering, `waitFor` timing, required `actions`, `onlyMainContent` trimming |
| `401` / `402` / `429` responses | API key validity and restrictions, remaining credits, plan rate limits |
| Job stuck or timing out | Queue state, page-level timeouts, job concurrency for your plan |
| Webhook never fired | Delivery attempts, endpoint responses, signature verification failures |
Don't have a job ID? Hover a row's URL in [Activity Logs](https://www.firecrawl.dev/app/logs) and click **Copy ID**, or use the `id` returned when you started the job.
### Debug from Activity Logs
If you'd rather not write the call yourself, the dashboard runs the same agent for you. Open [Activity Logs](https://www.firecrawl.dev/app/logs) and look for the sparkles button in the **Actions** column of a failed row — its tooltip reads **Debug issue**. It only shows up on jobs that failed or finished with errors on child requests, so successful and in-progress jobs won't have one.
Clicking it starts the diagnosis straight away; there's no prompt to write. Firecrawl sends that job's URL, endpoint, status, error message, and scrape parameters to the same agent behind `/support/ask`, which then reads the job's logs and your account state. Scraped page content is never included.
The panel that opens gives you:
| Element | What it is |
| - | - |
| Diagnosis | The agent's explanation of what went wrong and what to change |
| Confidence badge | High, medium, or low — how sure the agent is in the answer |
| **Validated** badge | Shown when the agent tested its own suggested fix and the test passed |
| Suggested fix | The corrected parameters as JSON, with a copy button — paste them into your next call |
| Sources | Links to the docs pages the answer draws on |
If the diagnosis doesn't resolve it, **Open support ticket** at the bottom of the panel files a ticket with the agent's analysis already attached, so you don't have to re-explain the failure.
> [!NOTE]
>
> Dashboard debugging is capped at 30 runs per hour per team, and your team needs at least one API key — the agent runs under your own key, so it only ever sees your jobs.
Once you have a diagnosis, apply the returned `fixParameters` and retry — see the [agent retry pattern](#agent-retry-pattern) below.
## How it works
When you call `/support/ask`, the AI agent:
1. **Gathers evidence** — inspects your job logs, account state, credit usage, and relevant documentation in parallel
2. **Diagnoses the issue** — reasons across all evidence to identify the root cause
3. **Proposes a fix** — generates machine-actionable `fixParameters` you can apply directly to your next API call
4. **Validates the fix** — when possible, tests the fix against the live Firecrawl API (e.g., retrying a scrape with adjusted parameters) and reports the result
## Using Ask in your agent
The key design pattern: call `/support/ask` when your Firecrawl API call fails or returns unexpected results, then use the `fixParameters` to retry.
### Python example
```python theme={null}
import requests
FIRECRAWL_API_KEY = "fc-YOUR_API_KEY"
def diagnose_firecrawl_issue(question, rationale=None):
"""Call the Firecrawl Ask API to debug an issue."""
payload = {"question": question}
if rationale:
payload["rationale"] = rationale
response = requests.post(
"https://api.firecrawl.dev/v2/support/ask",
headers={
"Authorization": f"Bearer {FIRECRAWL_API_KEY}",
"Content-Type": "application/json",
},
json=payload,
)
return response.json()
# Example: debug a scrape that returned empty content
result = diagnose_firecrawl_issue(
question="scrape returned empty markdown for https://example.com",
rationale="user needs product pricing data for competitive analysis",
)
print(result["answer"])
print(result["fixParameters"]) # e.g., {"waitFor": 5000, "actions": [...]}
print(result["confidence"]) # "high", "medium", or "low"
```
### Node.js example
```javascript theme={null}
async function diagnoseFirecrawlIssue(question, rationale) {
const response = await fetch(
"https://api.firecrawl.dev/v2/support/ask",
{
method: "POST",
headers: {
Authorization: `Bearer ${process.env.FIRECRAWL_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({ question, rationale }),
}
);
return response.json();
}
// Example: debug a crawl that stopped early
const result = await diagnoseFirecrawlIssue(
"my crawl returned 3 pages but I expected 50",
"user is on their third failed crawl attempt today"
);
console.log(result.answer);
console.log(result.fixParameters);
```
### Agent retry pattern
```python theme={null}
from firecrawl import Firecrawl
client = Firecrawl(api_key="fc-YOUR_API_KEY")
# Step 1: Try the scrape
doc = client.scrape("https://example.com/pricing", formats=["markdown"])
if not doc.markdown or len(doc.markdown) < 100:
# Step 2: Ask for help debugging
diagnosis = diagnose_firecrawl_issue(
question=f"scrape returned only {len(doc.markdown or '')} chars of markdown for https://example.com/pricing",
)
# Step 3: Apply fix parameters and retry
if diagnosis.get("fixParameters"):
doc = client.scrape(
"https://example.com/pricing",
formats=["markdown"],
**diagnosis["fixParameters"],
)
```
## Parameters
### `/support/ask`
| Parameter | Type | Required | Description |
| - | - | - | - |
| `question` | string | Yes | What to debug (1–8,000 characters) |
| `rationale` | string | No | Recommended for AI callers. What the end user is trying to accomplish. Helps prioritize evidence gathering. |
| `context` | object | No | Free-form metadata from your agent, included in the debugging prompt |
## Response
### `/support/ask` response
```json theme={null}
{
"requestId": "req_...",
"answer": "<2-4 sentence prose diagnosis of the issue plus the recommended fix.>",
"confidence": "high",
"fixParameters": { "": "" },
"validation": {
"tested": true,
"result": "success",
"evidence": ""
},
"feedback": null,
"durationMs": 18432
}
```
The actual `answer`, `fixParameters`, and `validation.evidence` are produced per request by the agent based on your specific run; the example above shows the response shape, not a real diagnosis.
## Performance
| Metric | Typical | Maximum |
| - | - | - |
| Latency | 15–30 seconds | 60 seconds (hard ceiling) |
## API Reference
* [Ask endpoint API Reference](/api-reference/endpoint/ask)
Have feedback or need help? Email [help@firecrawl.com](mailto:help@firecrawl.com).
> Are you an AI agent that needs a Firecrawl API key? See [firecrawl.dev/agent-onboarding/SKILL.md](https://www.firecrawl.dev/agent-onboarding/SKILL.md) for automated onboarding instructions.
# Camel AI
Source: https://docs.firecrawl.dev/integrations/camelai
Firecrawl integrates with Camel AI as a data loader.
> [!NOTE]
>
> **Official CAMEL docs:** [docs.camel-ai.org/key_modules/loaders](https://docs.camel-ai.org/key_modules/loaders)
>
> Firecrawl ships as a CAMEL loader, turning any site into LLM-ready markdown for your agents
## Installation
```bash theme={null}
pip install "camel-ai[web-tools]"
```
The `web-tools` extra installs the Firecrawl SDK version the loader supports. A plain `pip install camel-ai` doesn't include it, and the current CAMEL release fails with `firecrawl-py` 4.x, so don't upgrade `firecrawl-py` separately in the same environment.
Set your Firecrawl key so the loader picks it up automatically:
```bash theme={null}
export FIRECRAWL_API_KEY="fc-your-api-key"
```
## Usage
With Camel AI and Firecrawl you can quickly build multi-agent systems that use data from the web.
### Using Firecrawl to Gather an Entire Website
`crawl` returns once the job finishes. Check `status`, then read the markdown from `data`.
```python theme={null}
from camel.loaders import Firecrawl
firecrawl = Firecrawl()
response = firecrawl.crawl(url="https://www.camel-ai.org/about")
print(response["status"]) # "completed" when the crawl has finished
print(response["data"][0]["markdown"])
```
### Using Firecrawl to Gather a Single Page
```python theme={null}
from camel.loaders import Firecrawl
firecrawl = Firecrawl()
response = firecrawl.scrape(url="https://www.camel-ai.org/about")
print(response["markdown"])
```
### Mapping a Site and Extracting Structured Data
`map_site` lists a site's URLs, and `structured_scrape` returns fields that match a Pydantic model.
```python theme={null}
from pydantic import BaseModel
from camel.loaders import Firecrawl
class About(BaseModel):
mission: str
firecrawl = Firecrawl()
print(firecrawl.map_site(url="https://www.camel-ai.org")["links"][:5])
print(firecrawl.structured_scrape(url="https://www.camel-ai.org/about", response_format=About))
```
> [!TIP]
>
> `Firecrawl()` reads `FIRECRAWL_API_KEY` from the environment. Pass `api_key=...` to override it, or `api_url=...` to point at a [self-hosted](/contributing/self-host) instance.
## Resources
* [CAMEL loaders documentation](https://docs.camel-ai.org/key_modules/loaders)
* [CAMEL and Firecrawl walkthrough](https://www.camel-ai.org/blogs/firecrawl)
* [Firecrawl scrape](/features/scrape) and [crawl](/features/crawl) docs
# Composio
Source: https://docs.firecrawl.dev/integrations/composio
Use Firecrawl tools inside Composio agent workflows
> [!NOTE]
>
> **Official Composio docs:** [docs.composio.dev/toolkits/firecrawl](https://docs.composio.dev/toolkits/firecrawl)
>
> Connect Firecrawl to agents and apps through Composio toolkits
## Overview
Composio exposes Firecrawl as a toolkit so your agents can search, scrape, crawl, map, and run Agent jobs without custom API wiring. The toolkit authenticates with a Firecrawl API key.
## Quick start
1. Connect Firecrawl in the [Composio dashboard](https://dashboard.composio.dev) with your Firecrawl API key
2. Review available tools in the [Firecrawl toolkit docs](https://docs.composio.dev/toolkits/firecrawl)
3. Call Firecrawl tools from your Composio powered agents or workflows
## What you can do
| Capability | Use case |
| - | - |
| **Search** | Discover sources before extraction |
| **Scrape** | Fetch page content for agent context |
| **Batch scrape** | Pull many URLs in one job |
| **Crawl** | Gather multi-page site data |
| **Map** | List a site's URLs before deciding what to pull |
| **Agent** | Gather structured fields from a prompt instead of raw text |
## Resources
* [Composio Firecrawl toolkit](https://docs.composio.dev/toolkits/firecrawl)
* [Get an API key](https://www.firecrawl.dev/app/api-keys)
# CrewAI
Source: https://docs.firecrawl.dev/integrations/crewai
Learn how to use Firecrawl with CrewAI
## Using Firecrawl with CrewAI
Firecrawl is the context API for AI agents, and [CrewAI, the framework for orchestrating AI agents](https://www.crewai.com/), ships three Firecrawl tools: FirecrawlSearchTool, FirecrawlScrapeWebsiteTool and FirecrawlCrawlWebsiteTool. Use them to let your crews search, scrape, and crawl the web for clean context.
### Installing Firecrawl Tools inside of CrewAI
* Get an API key from your [firecrawl.dev dashboard](https://www.firecrawl.dev/app/api-keys) and set it in environment variables (`FIRECRAWL_API_KEY`).
* Install the [Firecrawl SDK](https://github.com/firecrawl/firecrawl) along with `crewai[tools]` package:
```
pip install firecrawl-py 'crewai[tools]'
```
Each tool takes its Firecrawl options in a `config` dict at construction time. The URL or query comes from the agent when it calls the tool, so you only pass options up front.
## Tools
### FirecrawlCrawlWebsiteTool
#### Example
Utilize the FirecrawlCrawlWebsiteTool as follows to allow your agent to crawl websites:
```python theme={null}
from crewai_tools import FirecrawlCrawlWebsiteTool
tool = FirecrawlCrawlWebsiteTool(config={"limit": 5})
# Agents call the tool with a URL. You can also run it directly:
result = tool.run(url="https://firecrawl.dev")
print(result.status, len(result.data))
```
#### Arguments
* `api_key`: Optional. Specifies Firecrawl API key. Defaults is the `FIRECRAWL_API_KEY` environment variable.
* `config`: Optional. [Crawl parameters](/api-reference/endpoint/crawl-post) in snake_case. Passing `config` replaces the defaults below.
* `limit`: Maximum number of pages to crawl. Default: `10`.
* `max_discovery_depth`: Maximum depth for discovering pages. Default: `2`.
* `ignore_sitemap`: Whether to ignore the sitemap. Default: `True`.
* `allow_external_links`: Allow crawling external links. Default: `False`.
* `allow_subdomains`: Allow crawling subdomains. Default: `False`.
* `delay`: Delay between requests in milliseconds. Default: `None`.
* `scrape_options`: Options for each crawled page. Default: `{"formats": ["markdown"], "only_main_content": True, "timeout": 10000}`.
### FirecrawlScrapeWebsiteTool
#### Example
Utilize the FirecrawlScrapeWebsiteTool as follows to allow your agent to load websites:
```python theme={null}
from crewai_tools import FirecrawlScrapeWebsiteTool
tool = FirecrawlScrapeWebsiteTool(config={"formats": ["markdown"], "only_main_content": True})
result = tool.run(url="https://firecrawl.dev")
print(result.markdown)
```
#### Arguments
* `api_key`: Optional. Specifies Firecrawl API key. Defaults is the `FIRECRAWL_API_KEY` environment variable.
* `config`: Optional. [Scrape parameters](/api-reference/endpoint/scrape) in snake_case. Passing `config` replaces the defaults below.
* `formats`: Output formats, such as `"markdown"`, `"html"`, `"links"`, or a JSON format object for structured extraction. Default: `["markdown"]`.
* `only_main_content`: Only return the main content of the page excluding headers, navs, footers, etc. Default: `True`.
* `include_tags` / `exclude_tags`: HTML tags to include or exclude. Default: `[]`.
* `max_age`: Return a cached version if it is younger than this many milliseconds. Default: `172800000` (2 days).
* `wait_for`: Delay in milliseconds before fetching content. Default: `0`.
* `mobile`: Emulate a mobile device. Default: `False`.
* `timeout`: Timeout in milliseconds for the request. Default: `None`.
### FirecrawlSearchTool
#### Example
Utilize the FirecrawlSearchTool as follows to allow your agent to search the web:
```python theme={null}
from crewai_tools import FirecrawlSearchTool
tool = FirecrawlSearchTool(config={"limit": 3})
result = tool.run(query="what is firecrawl?")
print([item.url for item in result.web])
```
#### Arguments
* `api_key`: Optional. Specifies Firecrawl API key. Defaults is the `FIRECRAWL_API_KEY` environment variable.
* `config`: Optional. [Search parameters](/api-reference/endpoint/search) in snake_case. Passing `config` replaces the defaults below.
* `limit`: Maximum number of search results to return. Default: `5`.
* `tbs`: Time-based search filter, for example `"qdr:d"` for the past day. Default: `None`.
* `location`: Location for search results. Default: `None`.
* `timeout`: Timeout in milliseconds for the request. Default: `None`.
* `scrape_options`: Scrape each result and return its content. Default: `{"formats": ["markdown"], "only_main_content": True}`. Leave it out to get only titles, URLs, and descriptions.
# Dify
Source: https://docs.firecrawl.dev/integrations/dify
Official Firecrawl plugin for Dify workflows, plus knowledge base website sync
> [!NOTE]
>
> **Official Dify Plugin:** [marketplace.dify.ai/plugins/langgenius/firecrawl](https://marketplace.dify.ai/plugins/langgenius/firecrawl)
>
> Official plugin by Dify team • 170,000+ installs • Chatflow & Agent apps • Free to use
## Dify Integration Overview
Dify is an open-source LLM app development platform. The official Firecrawl plugin gives your Dify workflows and agents clean context from the web: Search, Scrape, Crawl, Map, and Monitor, directly in Chatflow, Workflow, and Agent apps.
> [card] Chatflow & Workflow Apps
>
> Build visual pipelines with Firecrawl nodes for data extraction
> [card] Agent Applications
>
> Give AI agents the power to scrape live web data on demand
## Firecrawl Tools in Dify
The plugin ships seven actions.
> [accordion] Search
>
> Search the web and optionally scrape the returned results, so you get fresh result metadata or full page content in one step.
>
> **Use Cases:** Research assistants, competitor discovery, grounding answers in live sources.
> [accordion] Scrape
>
> Convert any URL into clean, structured data. Transform raw HTML into actionable insights.
>
> **Use Cases:** Extract product data, scrape article content, get structured data with JSON mode.
> [accordion] Crawl
>
> Perform recursive crawls of websites and subdomains to gather extensive content.
>
> **Use Cases:** Full site content extraction, documentation scraping, multi-page data collection.
> [accordion] Map
>
> Generate a complete map of all URLs present on a website.
>
> **Use Cases:** Site structure analysis, SEO auditing, URL discovery for batch scraping.
> [accordion] Crawl Job
>
> Retrieve scraping results based on a Job ID or cancel ongoing tasks.
>
> **Use Cases:** Monitor long-running crawls, manage async scraping workflows, cancel operations when needed.
> [accordion] Create Monitor
>
> Create a scheduled monitor that re-checks a target on a recurring schedule.
>
> **Use Cases:** Keeping ingested data fresh, changelog watching, competitor tracking.
> [accordion] Monitor Checks
>
> Retrieve a monitor's details and its check results, so you can act only on the pages that changed.
>
> **Use Cases:** Incremental knowledge base updates, change alerts, downstream triggers.
## Getting Started
**1. Install Firecrawl Plugin**
Access the [Dify Plugin Marketplace](https://marketplace.dify.ai/plugins/langgenius/firecrawl) and install the Firecrawl tool
**2. Get Firecrawl API Key**
Visit [Firecrawl API Keys](https://www.firecrawl.dev/app/api-keys) and create a new API key
**3. Authorize in Dify**
Navigate to **Plugins > Firecrawl > To Authorize** and input your API key
**4. Add to Your Workflow**
Drag Firecrawl tools into your Chatflow, Workflow, or Agent application
**5. Configure & Test**
Set up parameters and test your workflow
## Usage Patterns
> [tab] Chatflow Apps
>
> **Visual Pipeline Integration**
>
> 1. Add Firecrawl node to your pipeline
> 2. Select action (Search, Scrape, Crawl, Map)
> 3. Define input variables
> 4. Execute pipeline sequentially
>
> **Example Flow:**
>
> ```
> User Input → Firecrawl (Scrape) → LLM Processing → Response
> ```
> [tab] Workflow Apps
>
> **Automated Data Processing**
>
> Build multi-step workflows with:
>
> * Scheduled scraping
> * Data transformation
> * Database storage
> * Notifications
>
> **Example Flow:**
>
> ```
> Schedule Trigger → Firecrawl (Crawl) → Data Processing → Storage
> ```
> [tab] Agent Apps
>
> **AI-Powered Web Access**
>
> Give agents real-time web scraping capabilities:
>
> 1. Add Firecrawl tool to Agent
> 2. Agent autonomously decides when to scrape
> 3. LLM analyzes extracted content
> 4. Agent provides informed responses
>
> **Use Case:** Customer support agents that reference live documentation
## Common Use Cases
> [card] AI Chatbot with Live Data
>
> Build RAG-powered chatbots that scrape and reference live website content
> [card] Content Analysis Agent
>
> Agents that research topics by scraping and analyzing multiple sources
> [card] Competitor Monitoring
>
> Automated workflows that track competitor websites and alert on changes
> [card] Data Enrichment Pipeline
>
> Extract and enrich data from websites into structured databases
## Firecrawl Actions
| Tool | Description | Best For |
| - | - | - |
| **Search** | Web search with optional page content | Grounding answers in live sources |
| **Scrape** | Single-page data extraction | Quick content capture |
| **Crawl** | Multi-page recursive crawling | Full site extraction |
| **Map** | URL discovery and site mapping | SEO analysis, URL lists |
| **Crawl Job** | Async job management | Long-running operations |
| **Create Monitor** | Scheduled re-checks of a target | Keeping ingested data fresh |
| **Monitor Checks** | Monitor details and check results | Acting only on changed pages |
## Best Practices
> [card] Agent Apps
>
> * Let agents decide when to scrape
> * Use natural language instructions
> * Enable tool calling in LLM settings
> * Monitor token usage with large scrapes
> [card] Workflow Apps
>
> * Use Map before Crawl for large sites
> * Set appropriate crawl limits
> * Add error handling nodes
> * Test with small datasets first
## Dify vs Other Platforms
| Feature | Dify | Make | Zapier | n8n |
| - | - | - | - | - |
| **Type** | LLM app platform | Workflow automation | Workflow automation | Workflow automation |
| **Best For** | AI agents & chatbots | Visual workflows | Quick automation | Developer control |
| **Pricing** | Open-source + Cloud | Operations-based | Per-task | Execution-based |
| **AI-Native** | Yes | Partial | Partial | Partial |
| **Self-Hosted** | Yes | No | No | Yes |
> [!TIP]
>
> **Pro Tip:** Dify excels at building AI-native applications where agents need dynamic web access. Perfect for chatbots, research assistants, and AI tools that need live data.
## Sync websites into the Dify knowledge base
Firecrawl can also scrape a web page into Markdown and import it into the Dify knowledge base from [Dify Cloud](https://cloud.dify.ai/).
### Configuring Firecrawl
Open your avatar menu, go to the **DataSource** page, and configure Firecrawl credentials.

Log in to your Firecrawl account, get your API key, then enter and save it in Dify.

### Scrape the target webpage
On the knowledge base creation page, select Sync from website, choose Firecrawl as the provider, and enter the URL to scrape.

Configuration options include: whether to crawl sub-pages, page crawling limit, page scraping max depth, excluded paths, include only paths, and content extraction scope. After configuring, click Run to preview the parsed pages.

### Review import results
Imported page text is stored in knowledge base documents. View the results and click Add URL to import more pages.

# Flowise
Source: https://docs.firecrawl.dev/integrations/flowise
Learn how to use Firecrawl on Flowise
## Sync web data in Flowise workflows
Firecrawl can be used inside of [Flowise the Chatflow builder](https://flowiseai.com/). This page introduces how to configure and use a Firecrawl block inside of Flowise.

### Crawling with Firecrawl blocks
1. Log in to your Firecrawl account and get your API Key, and then add it to the block as a **FireCrawl API** credential.
2. (Optional) Connect Text Splitter.
3. Set **Type** to **Crawl** to pick up the pages below the target URL.
4. Input target URL to be crawled. Use **Limit**, **Include Paths**, and **Exclude Paths** to keep the crawl small.
5. Use the resulting documents in your workflows.
### Scraping with Firecrawl blocks
1. Log in to your Firecrawl account and get your API Key, and then add it to the block as a **FireCrawl API** credential.
2. (Optional) Connect Text Splitter.
3. Set **Type** to **Scrape** to pick up a single page.
4. Input target URL to be scraped.
5. Use the resulting documents in your workflows.
### Searching and extracting with Firecrawl blocks
Set **Type** to **Search** to turn web search results for a **Query** into documents, or to **Extract** to return structured data from a URL using a **Schema** and **Prompt**.
# LangChain
Source: https://docs.firecrawl.dev/integrations/langchain
Use Firecrawl in LangChain as a document loader or as agent tools.
> [!NOTE]
>
> **Official package:** [`langchain-firecrawl`](https://pypi.org/project/langchain-firecrawl/) · [source](https://github.com/firecrawl/langchain-firecrawl)
>
> Scrape, crawl, map, extract, and search from LangChain, as a document loader or as agent tools
## Install
```bash theme={null}
pip install langchain-firecrawl
```
Get a key from [firecrawl.dev](https://www.firecrawl.dev/app/api-keys) and set it in your environment (or pass `api_key=...`):
```bash theme={null}
export FIRECRAWL_API_KEY="fc-your-api-key"
```
## Document loader
`FirecrawlLoader` returns LangChain `Document`s. Choose a `mode`:
| Mode | What it loads |
| - | - |
| `scrape` | One page |
| `crawl` | A whole site |
| `map` | Discovered URLs |
| `extract` | Structured data |
| `search` | Web search results |
```python theme={null}
from langchain_firecrawl import FirecrawlLoader
loader = FirecrawlLoader(url="https://www.firecrawl.dev", mode="scrape")
docs = loader.load()
print(docs[0].page_content[:200])
print(docs[0].metadata)
```
## Agent tools
Each capability is also a `BaseTool` you can bind to an agent:
```python theme={null}
from langchain_firecrawl import (
FirecrawlScrape,
FirecrawlCrawl,
FirecrawlMap,
FirecrawlExtract,
FirecrawlSearch,
)
scrape = FirecrawlScrape()
result = scrape.invoke({"url": "https://www.firecrawl.dev"})
print(result["markdown"])
search = FirecrawlSearch()
print(search.invoke({"query": "best web scraping libraries", "limit": 5}))
```
## LangChain JS
The `FireCrawlLoader` in `@langchain/community` still calls v1 SDK methods, so it fails with the current Firecrawl JS SDK. Until it's updated, call the [Firecrawl Node SDK](/sdks/node) directly and wrap the results in LangChain `Document`s:
```bash theme={null}
npm install firecrawl @langchain/core
```
```typescript theme={null}
import Firecrawl from "firecrawl";
import { Document } from "@langchain/core/documents";
const firecrawl = new Firecrawl(); // reads FIRECRAWL_API_KEY
const crawl = await firecrawl.crawl("https://firecrawl.dev", { limit: 5 });
const docs = crawl.data.map(
(page) => new Document({ pageContent: page.markdown ?? "", metadata: page.metadata ?? {} })
);
```
## Resources
* [`langchain-firecrawl` on PyPI](https://pypi.org/project/langchain-firecrawl/)
* [Firecrawl scrape](/features/scrape) and [crawl](/features/crawl) docs
* [Firecrawl Python SDK](/sdks/python) and [Node SDK](/sdks/node)
# Langflow
Source: https://docs.firecrawl.dev/integrations/langflow
Learn how to use Firecrawl on Langflow
## Sync web data in Langflow workflows
Firecrawl can be used inside of [Langflow, the AI workflow builder](https://www.langflow.org/). This page introduces how to configure and use a Firecrawl block inside of Langflow.

### Installing the Firecrawl bundle
The Firecrawl blocks ship in the `lfx-firecrawl` bundle, which the default Langflow install doesn't include. Install it in the same environment as Langflow, then restart Langflow:
```bash theme={null}
uv pip install lfx-firecrawl
```
The bundle adds four blocks: **Firecrawl Scrape API**, **Firecrawl Crawl API**, **Firecrawl Map API**, and **Firecrawl Search API**. Each one returns the Firecrawl API response as `Data`. See the [Langflow Firecrawl bundle docs](https://docs.langflow.org/bundles-firecrawl) for every parameter.
### Scraping with Firecrawl blocks
1. Log in to your Firecrawl account and get your API Key, and then enter it on the block or pass it in from another part of the workflow.
2. Add the **Firecrawl Scrape API** block to pick up a single page.
3. Input target URL to be scraped or pass it in from another part of the workflow.
4. Set up any scrape options depending on what website and data you are trying to get, such as the output formats and whether to return only the main content. You can also pass these in from another part of the workflow.
5. (Optional) Set **Extractor Options** to get structured JSON from the page.
6. Use the data in your workflows.
### Crawling, mapping, and searching
* **Firecrawl Crawl API** crawls a URL and its sub-pages. Set limits and paths in **Crawler Options** and per-page settings in **Scrape Options**.
* **Firecrawl Map API** returns the URLs of one or more sites.
* **Firecrawl Search API** searches the web for a query, with an optional result **Limit** and **Location**.
# LlamaIndex
Source: https://docs.firecrawl.dev/integrations/llamaindex
Firecrawl integrates with LlamaIndex as a document reader.
## Installation
```bash theme={null}
pip install 'firecrawl-py>=4.3.3' llama-index llama-index-readers-web
```
## Usage
`FireCrawlWebReader` supports `scrape`, `crawl`, `map`, `search`, and `extract` modes.
Set `FIRECRAWL_API_KEY` in your environment. The query engine in these examples uses OpenAI by default, so also set `OPENAI_API_KEY` (or configure another LLM in LlamaIndex).
### Using Firecrawl to Gather an Entire Website
```python theme={null}
import os
from llama_index.core import SummaryIndex
from llama_index.readers.web import FireCrawlWebReader
# Initialize FireCrawlWebReader to crawl a website
firecrawl_reader = FireCrawlWebReader(
api_key=os.environ["FIRECRAWL_API_KEY"], # Get a key at https://www.firecrawl.dev/app/api-keys
mode="crawl", # "scrape", "crawl", "map", "search", or "extract"
params={"limit": 10}, # Optional Firecrawl parameters for the chosen mode
)
# Load documents from the site
documents = firecrawl_reader.load_data(url="https://www.paulgraham.com/")
index = SummaryIndex.from_documents(documents)
query_engine = index.as_query_engine()
response = query_engine.query("What did the author do growing up?")
print(response)
```
### Using Firecrawl to Gather a Single Page
```python theme={null}
import os
from llama_index.core import SummaryIndex
from llama_index.readers.web import FireCrawlWebReader
# Initialize the FireCrawlWebReader with your API key and desired mode
firecrawl_reader = FireCrawlWebReader(
api_key=os.environ["FIRECRAWL_API_KEY"], # Get a key at https://www.firecrawl.dev/app/api-keys
mode="scrape", # "scrape", "crawl", "map", "search", or "extract"
)
# Load documents from a specified URL
documents = firecrawl_reader.load_data(url="https://www.paulgraham.com/worked.html")
index = SummaryIndex.from_documents(documents)
query_engine = index.as_query_engine()
response = query_engine.query("What did the author do growing up?")
print(response)
```
# Lovable
Source: https://docs.firecrawl.dev/integrations/lovable
Connect Firecrawl to Lovable apps for live web scraping and crawling
> [!NOTE]
>
> **Official Lovable docs:** [docs.lovable.dev/integrations/firecrawl](https://docs.lovable.dev/integrations/firecrawl)
>
> Give your Lovable apps clean web context from Firecrawl: search, scrape (including JSON extraction), crawl, map, and monitor sites while you build and in published apps.
## Overview
Lovable apps can use Firecrawl to scrape and crawl websites into clean Markdown or structured data in chat while you build and in published apps. Firecrawl is available as an app and chat connector.
## Quick start
1. Open **Connectors** in Lovable and select **Firecrawl**
2. Add a connection with **Managed by Lovable** (no Firecrawl account needed), or **Use your own credentials** with your own Firecrawl API key
3. Link the connection to your project, then ask Lovable to scrape or crawl with Firecrawl
## What you can build
| Capability | Use case |
| - | - |
| **Search** | Search the web and get the content of the pages it finds |
| **Map** | List every URL on a site before you crawl it |
| **Scrape** | Turn URLs into clean markdown or structured JSON |
| **Crawl** | Gather pages across a site, including subpages |
| **Structured data** | Pull fields like product details, tables, and metadata with Scrape's JSON format |
## Resources
* [Lovable Firecrawl integration](https://docs.lovable.dev/integrations/firecrawl)
* [Firecrawl scrape docs](/features/scrape)
* [Firecrawl crawl docs](/features/crawl)
# Make
Source: https://docs.firecrawl.dev/integrations/make
Official integration and workflow automation for Firecrawl and Make
> [!NOTE]
>
> **Official Make Integration:** [make.com/en/integrations/firecrawl](https://www.make.com/en/integrations/firecrawl)
>
> Connect with 3,000+ apps • Visual workflow builder • Enterprise-grade automation • AI-powered scenarios
## Make Integration Overview
Make (formerly Integromat) provides a verified, officially supported Firecrawl integration maintained by the Firecrawl team.
> [card] Visual Workflow Builder
>
> Design complex automations with Make's intuitive visual interface
> [card] Enterprise Ready
>
> Scale securely with enterprise-grade automation and controls
## Firecrawl Modules in Make
> [accordion] Actions (6 modules)
>
> ### Crawl a Website
>
> Crawl a URL and get its content from multiple pages
>
> ***
>
> ### Extract a Website
>
> Extract structured data from pages using LLMs
>
> ***
>
> ### Scrape a Website
>
> Scrape a URL and get its content from a single page
>
> ***
>
> ### Map a Website
>
> Map multiple URLs based on options
>
> ***
>
> ### Get Crawl Status
>
> Get the status of a given crawl event ID
>
> ***
>
> ### Get Extract Status
>
> Get the status of a given extraction event ID
> [accordion] Search (1 module)
>
> ### Search a Website
>
> Full-page content retrieval for any search query
> [accordion] Advanced
>
> ### Make an API Call
>
> Perform arbitrary authorized API calls for custom use cases
## Popular App Integrations
> [tab] Data Storage
>
> **Google Sheets** - Track and log scraped data in spreadsheets
>
> **Airtable** - Build structured databases with scraped content
>
> **Google Drive** - Store scraped files and reports
>
> **Notion** - Organize research and web data
> [tab] Communication
>
> **Slack** - Get alerts for website changes and updates
>
> **Telegram Bot** - Instant notifications for monitoring
>
> **Gmail** - Email reports and digests
>
> **Microsoft 365 Email** - Enterprise email automation
> [tab] CRM & Sales
>
> **HubSpot CRM** - Enrich leads with web data
>
> **monday.com** - Track competitor intelligence
>
> **ClickUp** - Manage research tasks
> [tab] AI Tools
>
> **OpenAI (ChatGPT, DALL-E)** - Analyze and summarize scraped content
>
> **Google Gemini AI** - Process and extract insights
>
> **Perplexity AI** - Enhanced research workflows
>
> **Make AI Agents** - Build adaptive AI-powered automations
## Common Workflow Patterns
> [card] Competitor Monitoring
>
> **Schedule** → Firecrawl (Scrape) → Google Sheets (Log) → Slack (Alert)
>
> Track competitor websites and get instant notifications
> [card] Lead Enrichment
>
> **Google Forms** → Firecrawl (Scrape company site) → HubSpot CRM (Update)
>
> Automatically enrich leads with company data
> [card] Content Aggregation
>
> **Schedule** → Firecrawl (Crawl blog) → OpenAI (Summarize) → Gmail (Send digest)
>
> Automated content curation and distribution
> [card] Price Monitoring
>
> **Schedule (Hourly)** → Firecrawl (Scrape) → Filter → Telegram (Alert)
>
> Real-time price tracking and alerts
## Getting Started
**1. Sign up for Firecrawl**
Get your API key at [firecrawl.dev](https://firecrawl.dev)
**2. Create a Scenario in Make**
Log into [Make](https://make.com) and click "Create a new scenario"
**3. Add Firecrawl Module**
Search for "Firecrawl" and select your desired action
**4. Connect with API Key**
Add your Firecrawl API key to authenticate
**5. Configure & Test**
Set up your workflow parameters and run a test
## Firecrawl Actions Overview
| Module | Use Case | Best For |
| - | - | - |
| **Scrape a Website** | Single-page data extraction | Quick data capture |
| **Crawl a Website** | Multi-page content collection | Full site scraping |
| **Extract a Website** | AI-powered structured extraction | Complex data needs |
| **Search a Website** | Search + full content | Research automation |
| **Map a Website** | URL discovery | SEO analysis |
## Best Practices
> [card] Performance
>
> * Use **Scrape** for single pages (fastest)
> * Use **Crawl** with limits for large sites
> * Schedule appropriately to stay within your rate limits
> * Add error handling modules
> [card] Cost Optimization
>
> * Schedule strategically (hourly/daily/weekly)
> * Use filters to prevent unnecessary runs
> * Set crawl limits to control API usage
> * Test in Firecrawl playground first
## Industry Use Cases
> [accordion] E-commerce
>
> * Competitor price monitoring
> * Product availability tracking
> * Review aggregation and analysis
> * Inventory level monitoring
> [accordion] Real Estate
>
> * Listing aggregation from multiple sources
> * Market trend analysis
> * Property data enrichment
> * Competitive pricing intelligence
> [accordion] Marketing
>
> * Competitor content monitoring
> * SEO performance tracking
> * Backlink analysis
> * Social media mention tracking
> [accordion] Finance
>
> * Market data collection
> * News and sentiment aggregation
> * Regulatory filing monitoring
> * Stock price tracking
> [accordion] HR & Recruitment
>
> * Job posting aggregation
> * Company research automation
> * Candidate background enrichment
> * Salary benchmarking
## Make vs Zapier vs n8n
| Feature | Make | Zapier | n8n |
| - | - | - | - |
| **Setup** | Visual builder, cloud | No-code, cloud | Self-hosted or cloud |
| **Pricing** | Operations-based | Per-task pricing | Execution-based |
| **Integrations** | 3,000+ apps | 9,000+ apps | 1,000+ apps and services |
| **Complexity** | Advanced workflows | Simple workflows | Complex workflows |
| **Best For** | Visual automation, mid-complexity | Quick automation | Developer control |
| **Learning Curve** | Moderate | Easy | Moderate-Advanced |
> [!TIP]
>
> **Pro Tip:** Make excels at visual workflow design and complex automations. Perfect for teams that need more control than Zapier but prefer visual building over n8n's code-first approach.
# n8n
Source: https://docs.firecrawl.dev/integrations/n8n
Learn how to use Firecrawl with n8n to give your AI workflows search, scrape, and web interaction capabilities.
## Introduction to Firecrawl and n8n
Firecrawl is the context API for AI agents, and the Firecrawl node brings Search, Scrape, Crawl, Map, Interact, and Agent into your n8n workflows. Monitor prices, aggregate content, generate leads, or feed clean context to AI agents, without writing code.

**What is n8n?**
n8n is an open-source workflow automation platform that connects different tools and services together. Think of it as a visual programming environment where you drag and drop nodes onto a canvas, connect them, and create automated workflows. With 1,900+ integrations, n8n lets you build complex automations without writing code.
## Why Use Firecrawl with n8n?
Traditional web scraping presents several challenges. Custom scripts break when websites update their structure. Complex, JavaScript-heavy sites don't render properly. Infrastructure requires constant maintenance.
Firecrawl handles these technical complexities on the scraping side, while n8n provides the automation framework. Together, they let you build production-ready workflows that:
* Extract data from any website reliably
* Connect scraped data to other business tools
* Run on schedules or triggered by events
* Scale from simple tasks to complex pipelines
This guide will walk you through setting up both platforms and building your first scraping workflow from scratch.
## Step 1: Create Your Firecrawl Account
Firecrawl provides search, scrape, and browser interaction capabilities for your AI agents and workflows. Let's set up your account and get your API credentials.
### Sign Up for Firecrawl
1. Navigate to [firecrawl.dev](https://firecrawl.dev) in your web browser
2. Click the "Get Started" or "Sign Up" button
3. Create an account using your email address or GitHub login
4. Verify your email if prompted
### Get Your API Key
After signing in, you need an API key to connect Firecrawl to n8n:
1. Go to your Firecrawl dashboard
2. Navigate to the [API Keys page](https://www.firecrawl.dev/app/api-keys)
3. Click "Create New API Key"
4. Give your key a descriptive name (e.g., "n8n Integration")
5. Copy the generated API key and save it somewhere secure
> [!NOTE]
>
> Your API key is like a password. Keep it secure and never share it publicly. You'll need this key in the next section.
Firecrawl provides free credits when you sign up, which is enough to test your workflows and complete this tutorial.
## Step 2: Set Up n8n
n8n offers two deployment options: cloud-hosted or self-hosted. For beginners, the cloud version is the fastest way to get started.
### Choose Your n8n Version
**n8n Cloud (Recommended for beginners):**
* No installation required
* Free tier available
* Managed infrastructure
* Automatic updates
**Self-Hosted:**
* Complete data control
* Run on your own servers
* Requires Docker installation
* Good for advanced users with specific security requirements
Choose the option that fits your needs. Both paths will lead you to the same workflow editor interface.
### Option A: n8n Cloud (Recommended for Beginners)
1. Visit [n8n.cloud](https://n8n.cloud)
2. Click "Start Free" or "Sign Up"
3. Register using your email address or GitHub
4. Complete the verification process
5. You'll be directed to your n8n dashboard

The free tier provides everything you need to build and test workflows. You can upgrade later if you need more execution time or advanced features.
### Option B: Self-Hosted with Docker
If you prefer to run n8n on your own infrastructure, you can set it up quickly using Docker.
**Prerequisites:**
* [Docker Desktop](https://www.docker.com/products/docker-desktop/) installed on your computer
* Basic familiarity with command line/terminal
**Installation Steps:**
1. Open your terminal or command prompt
2. Create a Docker volume to persist your workflow data:
```bash theme={null}
docker volume create n8n_data
```
This volume stores your workflows, credentials, and execution history so they persist even if you restart the container.
3. Run the n8n Docker container:
```bash theme={null}
docker run -it --rm --name n8n -p 5678:5678 -v n8n_data:/home/node/.n8n docker.n8n.io/n8nio/n8n
```
4. Wait for n8n to start. You'll see output indicating the server is running
5. Open your web browser and navigate to `http://localhost:5678`
6. Create your n8n account by registering with an email

Your self-hosted n8n instance is now running locally. The interface is identical to n8n Cloud, so you can follow the rest of this guide regardless of which option you chose.
> [!NOTE]
>
> The `--rm` flag automatically removes the container when you stop it, but your data remains safe in the `n8n_data` volume. For production deployments, see the [n8n self-hosting documentation](https://docs.n8n.io/hosting/) for more advanced configuration options.
### Understanding the n8n Interface
When you first log in to n8n, you'll see the main dashboard:

Key interface elements:
* **Workflows**: Your saved automations appear here
* **Executions**: History of workflow runs
* **Credentials**: Stored API keys and authentication tokens
* **Settings**: Account and workspace configuration
Click "Create New Workflow" to open the workflow editor.
### The Workflow Canvas
The workflow editor is where you'll build your automations:

Important elements:
* **Canvas**: The main area where you place and connect nodes
* **Add Node Button (+)**: Click this to add new nodes to your workflow
* **Node Panel**: Opens when you click "+" showing all available nodes
* **Execute Workflow**: Runs your workflow manually for testing
* **Save**: Saves your workflow configuration
Let's build your first workflow by adding the Firecrawl node.
## Step 3: Install and Configure the Firecrawl Node
Firecrawl is available in n8n as a verified node (`@mendable/n8n-nodes-firecrawl`), built and maintained by Firecrawl. You'll install the node and connect it to your Firecrawl account using the API key you created earlier. On self-hosted n8n, an instance owner installs verified nodes once, and then everyone on the instance can use them.
### Add the Firecrawl Node to Your Workflow
1. In your new workflow canvas, click the "**+**" button in the center
2. The node selection panel opens on the right side
3. In the search box at the top, type "**Firecrawl**"
4. You'll see the Firecrawl node appear in the search results
5. Click "**Install**" next to the Firecrawl node
6. Wait for the installation to complete (this takes a few seconds)
7. Once installed, click on the Firecrawl node to add it to your canvas
The Firecrawl node will appear on your canvas as a box with the Firecrawl logo. This node represents a single Firecrawl operation in your workflow.
### Connect Your Firecrawl API Key
> [!TIP]
>
> **n8n Cloud users:** The launch offer that included a free Hobby plan and 100,000 credits has expired. You can still use the one-click **"Connect to Firecrawl"** OAuth button when adding the Firecrawl node. This automatically creates a new Firecrawl team linked to your n8n account and grants **10,000 free credits**. These credits do not include a Hobby plan upgrade. To view them on the [Firecrawl dashboard](https://www.firecrawl.dev/app/usage), make sure you switch to your n8n-linked team using the team selector in the top-left corner.
Before you can use the Firecrawl node, you need to authenticate it with your API key:
1. Click on the Firecrawl node box to open its configuration panel on the right
2. At the top, you'll see a "Credential to connect with" dropdown
3. Since this is your first time, click "**Create New Credential**"
4. A credential configuration window opens
5. Enter a name for this credential (e.g., "My Firecrawl Account")
6. Paste your Firecrawl API key in the "API Key" field
7. Click "**Save**" at the bottom
The credential is now saved in n8n. You won't need to enter your API key again for future Firecrawl nodes.
> [!NOTE]
>
> The credential also has a **Base URL** field, which defaults to `https://api.firecrawl.dev/v2`. Credentials created with older versions of the node can still point at `https://api.firecrawl.dev/v1`. With a v1 Base URL, operations that only exist in v2, such as Agent, Browser, and Interact, fail with a 404 error ("The resource you are requesting could not be found"). Open the credential and set **Base URL** to `https://api.firecrawl.dev/v2`.
### Test Your Connection
Let's verify that your Firecrawl node is properly connected:
1. With the Firecrawl node still selected, look at the configuration panel
2. Set **Resource** to "**Scraping**" and **Operation** to "**Scrape URL**"
3. In the "URL" field, enter: `https://firecrawl.dev`
4. Leave other settings at their defaults for now
5. Click the "**Execute step**" button
If everything is configured correctly, you'll see the scraped content from firecrawl.dev appear in the output panel.
Congratulations! Your Firecrawl node is now connected and working.
## Step 4: Create Your Telegram Bot
Before building your first workflow, you'll need a Telegram bot to receive notifications. Telegram bots are free and easy to create through Telegram's BotFather.
### Create a Bot with BotFather
1. Open Telegram on your phone or desktop
2. Search for "**@BotFather**" (the official bot from Telegram)
3. Start a conversation with BotFather by clicking "**Start**"
4. Send the command `/newbot` to create a new bot
5. BotFather will ask you to choose a name for your bot (this is the display name users will see)
6. Enter a name like "**My Firecrawl Bot**"
7. Next, choose a username for your bot. It must end with "bot" (e.g., "**my_firecrawl_updates_bot**")
8. If the username is available, BotFather will create your bot and send you a message with your bot token

> [!NOTE]
>
> Save your bot token securely. This token is like a password that allows n8n to send messages as your bot. Never share it publicly.
### Get Your Chat ID
To send messages to yourself, you need your Telegram chat ID:
1. Open your web browser and visit this URL (replace `YOUR_BOT_TOKEN` with your actual bot token):
```
https://api.telegram.org/botYOUR_BOT_TOKEN/getUpdates
```
2. Keep this browser tab open
3. Now, search for your bot's username in Telegram (the one you just created)
4. Start a conversation with your bot by clicking "**Start**"
5. Send any message to your bot (e.g., "hello")
6. Go back to the browser tab and refresh the page
7. Look for the `"chat":{"id":` field in the JSON response
8. The number next to `"id":` is your chat ID (e.g., `123456789`)
9. Save this chat ID for later
> [!NOTE]
>
> Your chat ID is the unique identifier for your conversation with the bot. You'll use this to tell n8n where to send messages.
You now have everything needed to integrate Telegram with your n8n workflows.
## Step 5: Build Practical Workflows with Telegram
Now let's build three real-world workflows that send information directly to your Telegram. These examples demonstrate different Firecrawl operations and how to integrate them with Telegram notifications.
### Example 1: Daily Firecrawl Product Updates Summary
Get a daily summary of Firecrawl product updates delivered to your Telegram every morning.
**What you'll build:**
* Scrapes Firecrawl's product updates blog at 9 AM daily
* Uses AI to generate a summary of the content
* Sends the summary to your Telegram
**Step-by-step:**
1. Create a new workflow in n8n
2. Add a **Schedule Trigger** node:
* Click the "**+**" button on canvas
* Search for "**Schedule Trigger**"
* Configure: Every day at 9:00 AM
3. Add the **Firecrawl** node:
* Click "**+**" next to Schedule Trigger
* Search for and add "**Firecrawl**"
* Select your Firecrawl credential
* Configure:
* **Resource**: Scraping
* **Operation**: Scrape URL
* **URL**: `https://www.firecrawl.dev/blog/category/product-updates`
* **Scrape Options**: Add **Formats** and select "Summary"
4. Add the **Telegram** node:
* Click "**+**" next to Firecrawl
* Search for "**Telegram**"
* Click "**Send a text message**" to add it to the canvas
5. Set up Telegram credentials:
* Click on the Telegram node to open its configuration
* In the "Credential to connect with" dropdown, click "**Create New Credential**"
* Paste your bot token from BotFather
* Click "**Save**"

6. Configure the Telegram message:
* **Operation**: Send Message
* **Chat ID**: Enter your chat ID
* **Text**: Leave this with a "hello" message for now
* Click **Execute step** to test sending a message while receiving the summary from Firecrawl.

* Now with Firecrawl's summary structure, add the summary to the message text by dragging the `summary` field (under `data`) from the Firecrawl node output.
7. Test the workflow:
* Click "**Execute Workflow**"
* Check your Telegram for the summary message

8. Activate the workflow by toggling the "**Active**" switch
Your Telegram bot will now send you a daily summary of Firecrawl product updates every morning at 9 AM.
### Example 2: AI News Search to Telegram
This workflow uses Firecrawl's Search operation to find AI news and send formatted results to Telegram.
**Key differences from Example 1:**
* Uses a **Manual Trigger** instead of Schedule (run on demand)
* Uses **Search** operation instead of Scrape
* Includes a **Code** node to format multiple results
**Build the workflow:**
1. Create a new workflow and add a **Manual Trigger** node
2. Add **Firecrawl** node with these settings:
* **Resource**: Map & Search
* **Operation**: Search Web
* **Query**: `ai news`
* **Limit**: 5
3. Add a **Code** node to format the search results:
* Select "Run Once for All Items"
* Paste this code:
```javascript theme={null}
const results = $input.all();
let message = "Latest AI News:\n\n";
results.forEach((item) => {
const webData = item.json.data?.web || [];
webData.forEach((article, index) => {
message += `${index + 1}. ${article.title}\n`;
message += `${article.description}\n`;
message += `${article.url}\n\n`;
});
});
return [{ json: { message } }];
```
4. Update **Telegram** node (using your saved credential):
* **Text**: Drag the `message` field from Code node

> [!TIP]
>
> Replace the Manual Trigger with a Schedule Trigger to get automatic AI news updates at set intervals.
### Example 3: AI-Powered News Summary
This workflow adds AI to Example 2, using OpenAI to generate intelligent summaries of the latest AI news before sending to Telegram.
**Key changes from Example 2:**
* Add **OpenAI credentials** setup
* Add **AI Agent** node between Code and Telegram
* AI Agent analyzes and summarizes all the news articles intelligently
* Telegram receives the AI-generated summary instead of raw news list
**Modify the workflow:**
1. **Get your OpenAI API key**:
* Go to [platform.openai.com/api-keys](https://platform.openai.com/api-keys)
* Sign in or create an account
* Click "**Create new secret key**"
* Give it a name (e.g., "n8n Integration")
* Copy the API key immediately (you won't see it again)
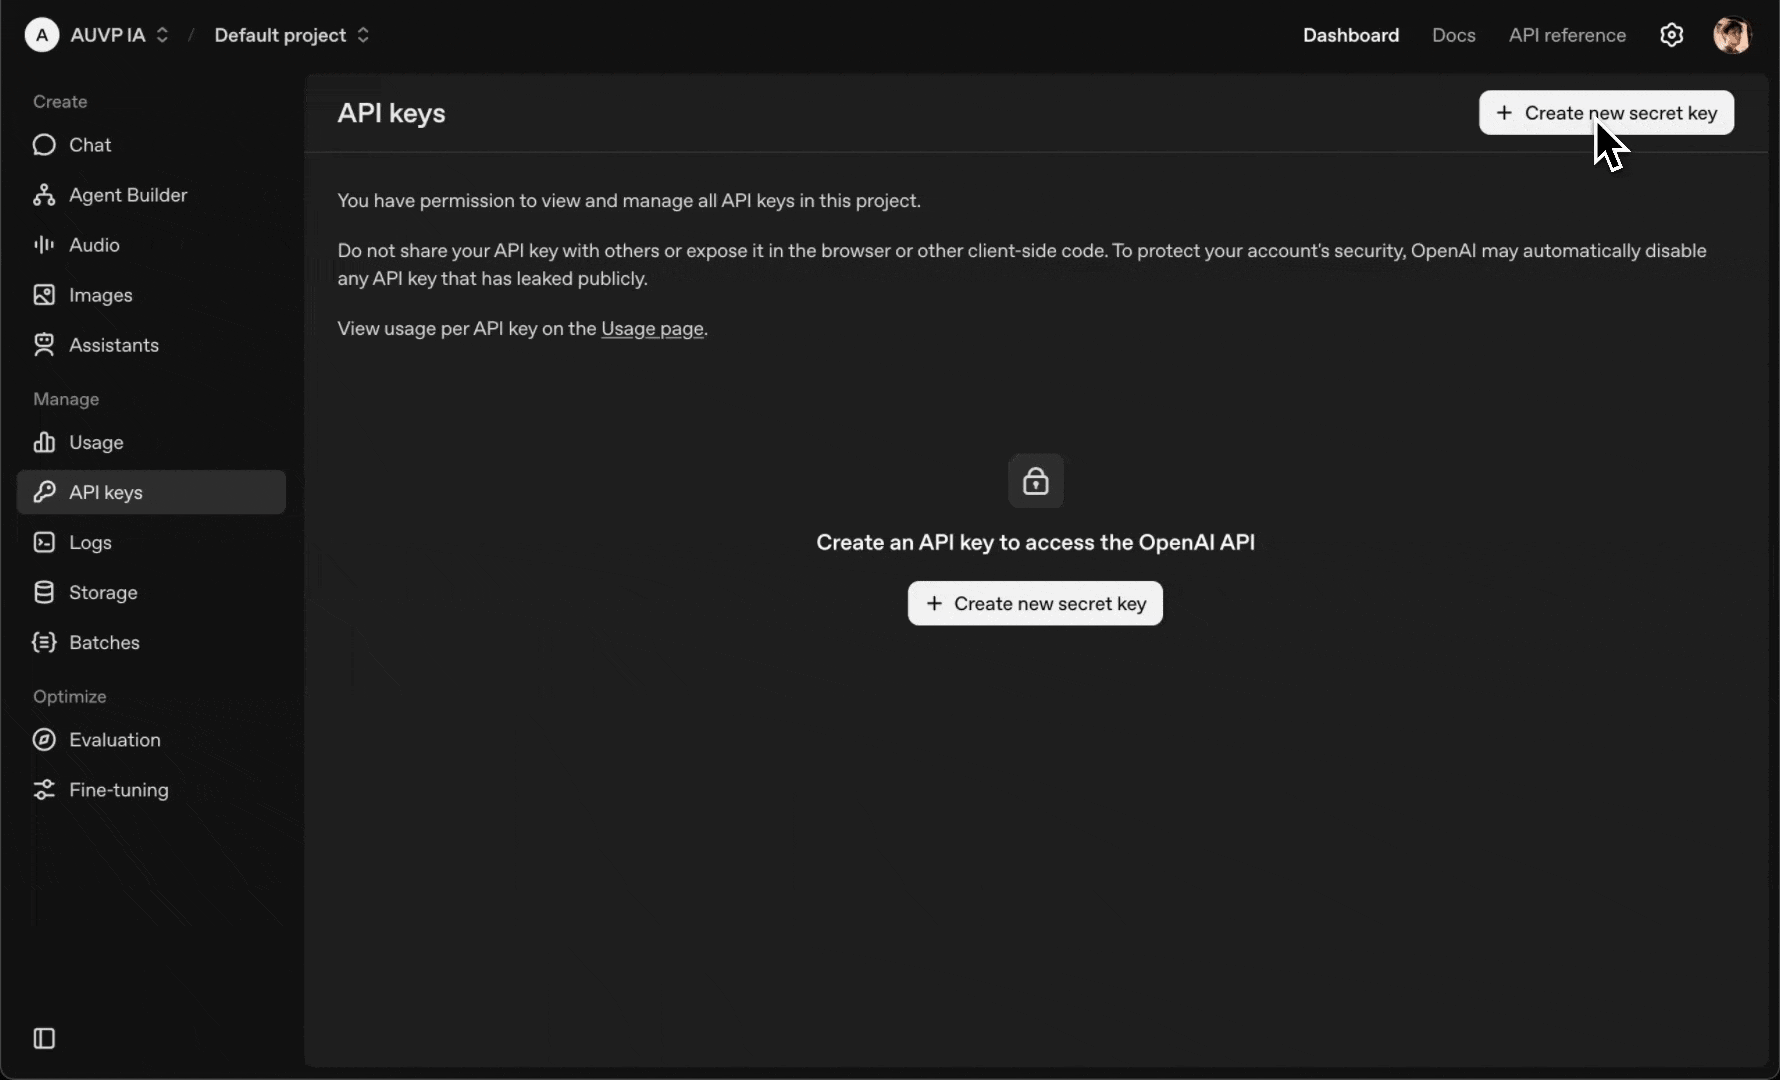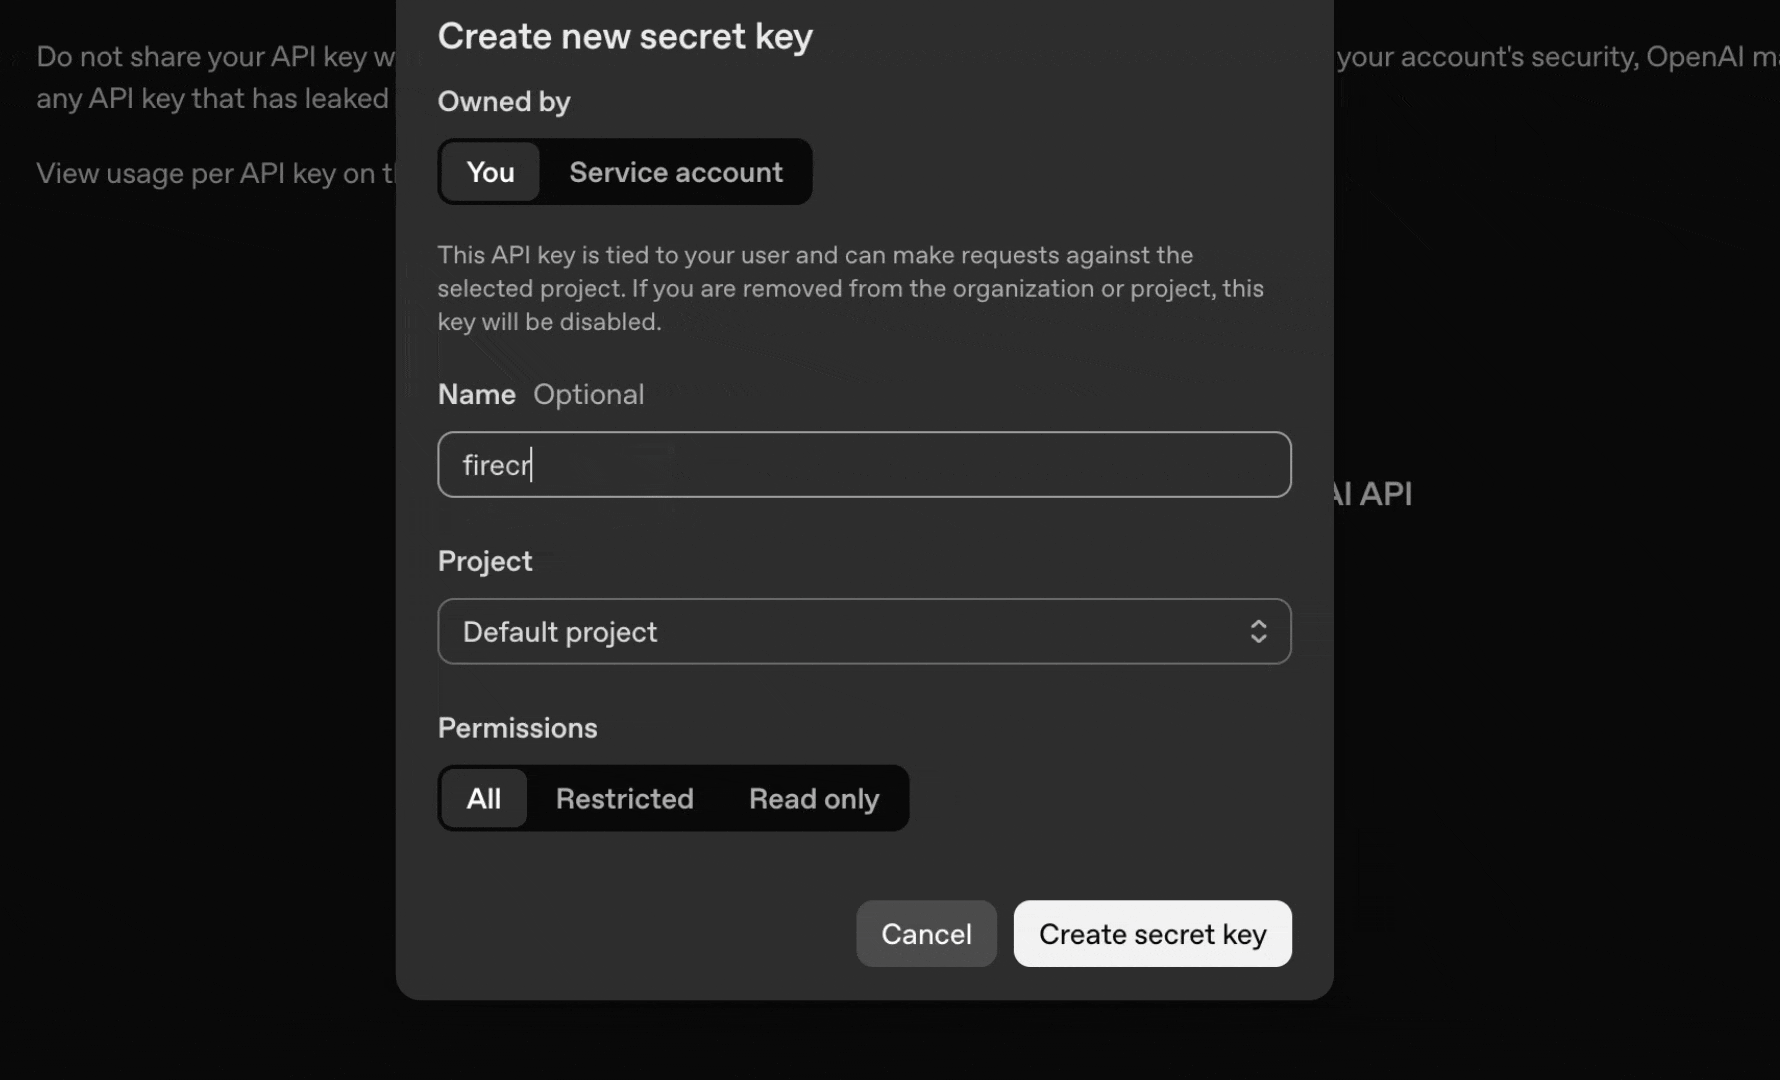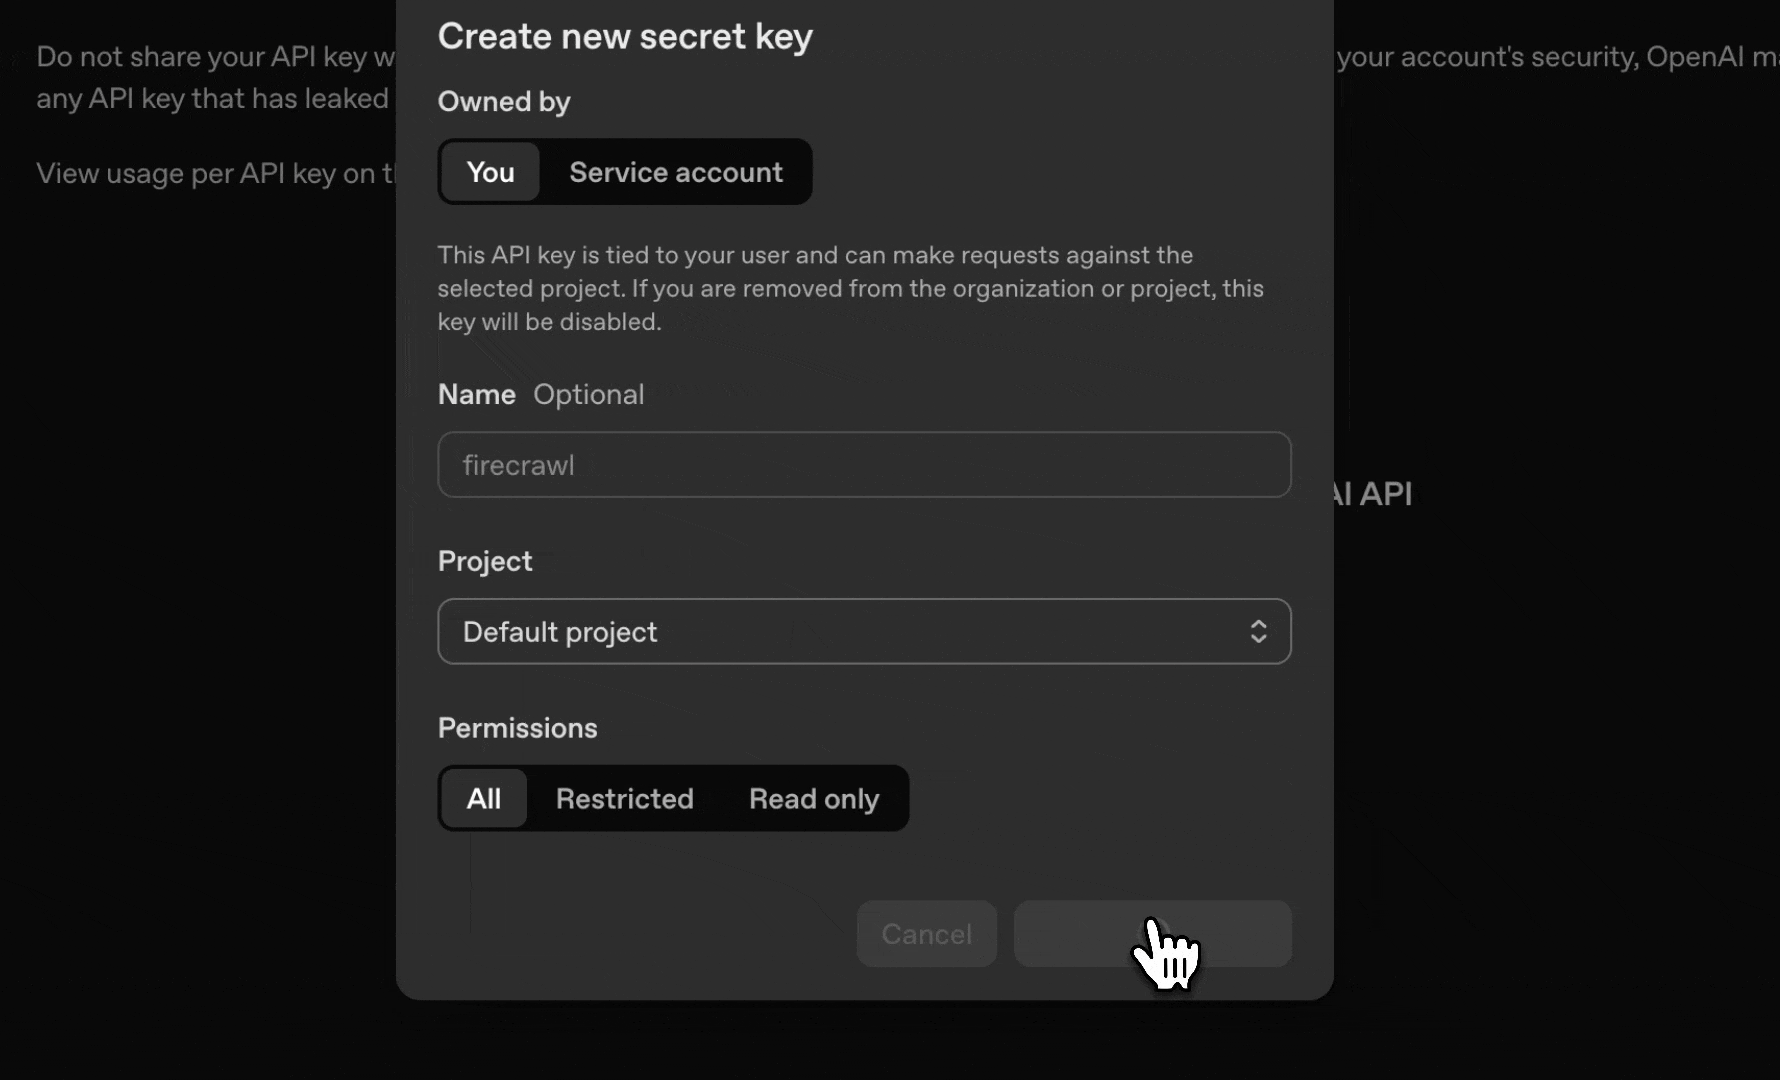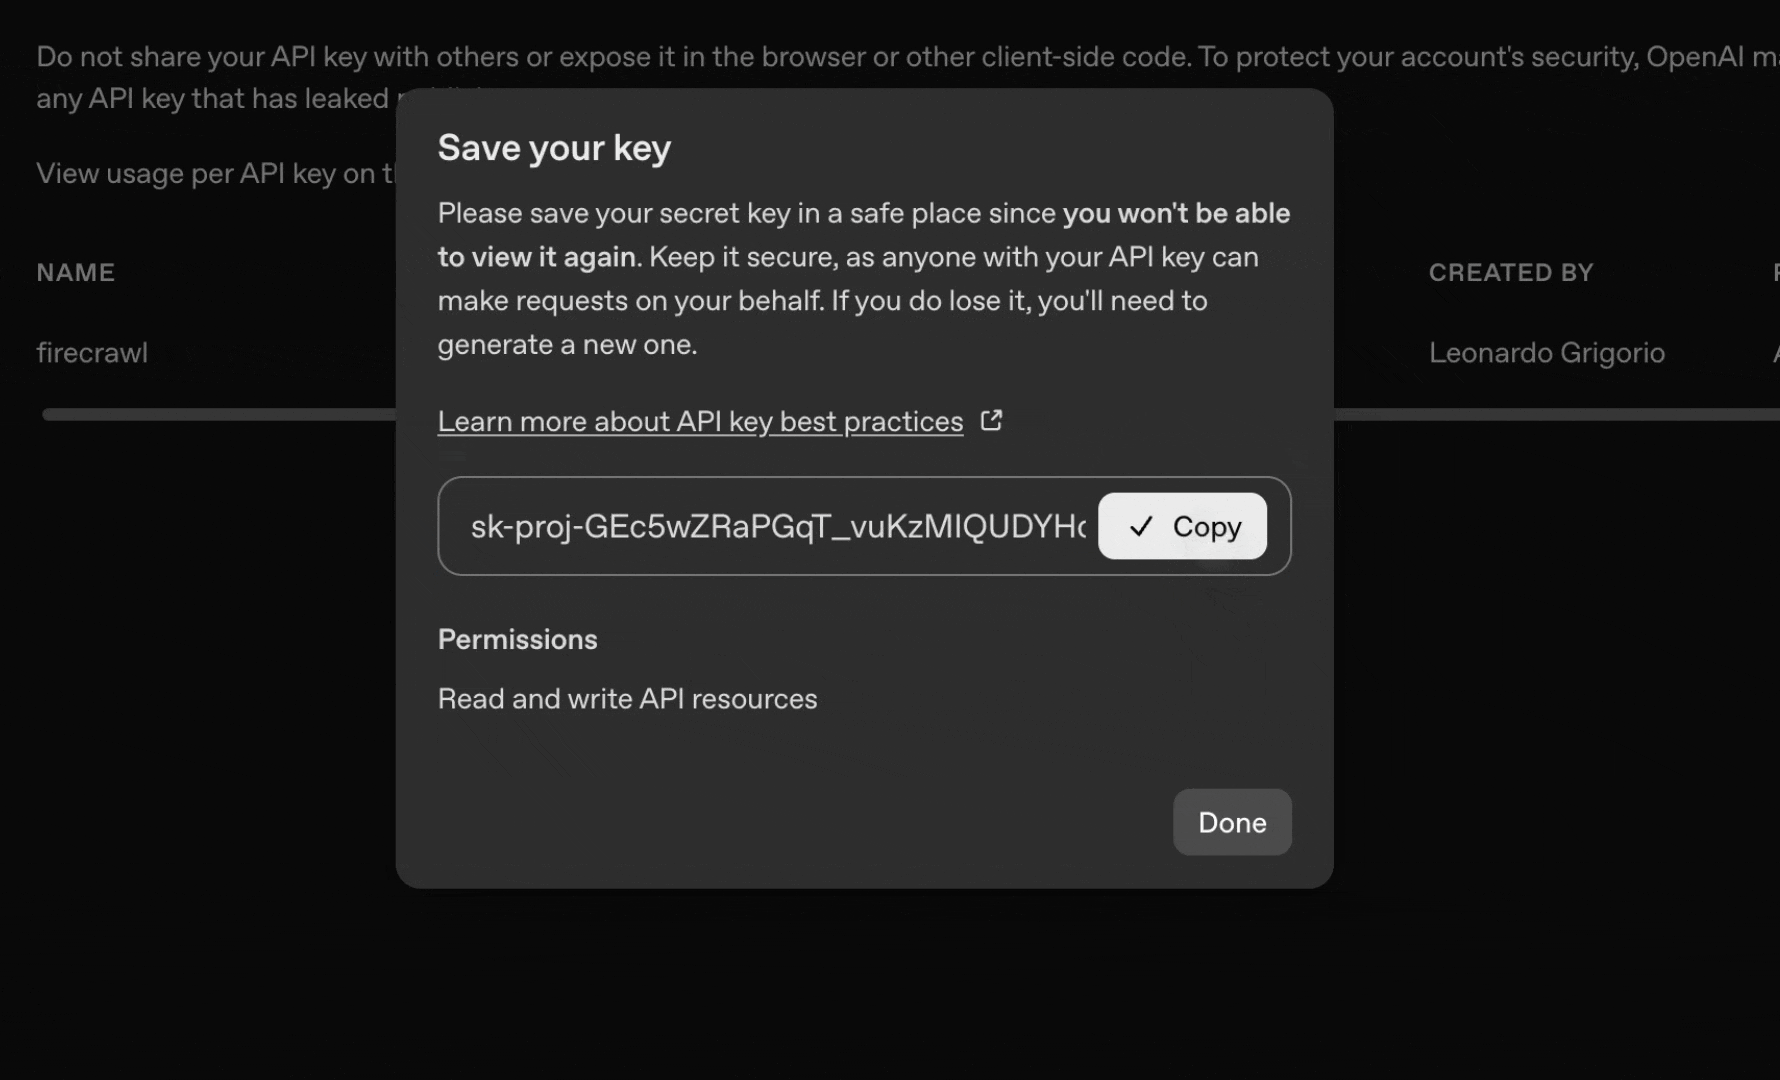
2. **Add and connect the AI Agent node**:
* Click "**+**" after the Code node
* Search for "**Basic LLM Chain**" or "**AI Agent**"
* Drag the `message` field from the Code node to the AI Agent's input prompt field
* Select **OpenAI** as the LLM provider

3. **Add your OpenAI credentials**:
* Click "**Create New Credential**" for OpenAI
* Paste your OpenAI API key
* Select model: **gpt-5-mini** (cost-effective) or **gpt-5** (more capable)
* Click "**Save**"
4. **Add the system prompt to the AI Agent**:
* In the AI Agent node, add this system prompt:
```
You are an AI news analyst. Analyze the provided AI news articles and create a concise,
insightful summary highlighting the most important developments and trends.
Group related topics together and provide context about why these developments matter.
Keep the summary conversational and engaging, around 3-4 paragraphs.
```
5. **Update the Telegram node and test**:
* Update the Telegram node:
* **Text**: Drag the AI Agent's output (the generated summary)
* Remove the old mapping to the Code node's message
* Click "**Execute Workflow**" to test
* The AI will analyze all news articles and create a summary
* Check your Telegram for the AI-generated summary

> [!NOTE]
>
> The AI Agent receives all the formatted news articles and creates an intelligent summary, making it easier to understand trends and important developments at a glance.
## Understanding Firecrawl Operations
Now that you've built some workflows, let's explore the different Firecrawl operations available in n8n. On the Firecrawl node, you first pick a **Resource** (Scraping, Crawling, Map & Search, Agent, Interact, Browser, Account, or Extract (Legacy)) and then an **Operation**. Each operation is designed for specific web data use cases.
### Scrape URL
Resource: **Scraping**. Extracts content from a single web page and returns it in various formats.
**What it does:**
* Scrapes a single URL
* Returns clean markdown, HTML, or AI-generated summaries
* Returns structured data with the **JSON** format and a prompt or schema
* Can capture screenshots and extract links
**Best for:**
* Article extraction
* Product page monitoring
* Blog post scraping
* Generating page summaries
**Example use case:** Daily blog summaries (like Example 1 above)
### Interact
Resource: **Interact**. Keeps working with a page after **Scrape URL**: click, fill forms, and navigate, using a natural language prompt or Playwright or Bash code.
**Operations:**
* **Execute Interaction**: runs a prompt or code against a scraped page, using the `scrapeId` from the Scrape URL output (`data.metadata.scrapeId`)
* **Stop Interaction**: ends the interact session for that `scrapeId`
* **Get Interact Context**: returns usage instructions for AI agents that call these operations as tools
For workflows that use Scrape followed by Interact with a persistent browser profile, set the **Profile** on the **Scrape URL** step. The Execute Interaction step only needs the `scrapeId` plus a prompt or code. Do not add `profile` to the Interact request body; Interact inherits the profile from the scrape job.
To save cookies, localStorage, and other browser state, run **Stop Interaction** when the workflow is done. If you only need to read an existing profile in a later workflow run, turn off **Save Changes** in the Scrape step's profile settings.
If your installed Firecrawl n8n node version does not show **Profile** on the Scrape URL operation, update to the latest Firecrawl n8n node. You can also pass the same `profile` object under **Additional Fields** > **Custom Properties (JSON)**:
```json theme={null}
{
"profile": {
"name": "my-profile",
"saveChanges": true
}
}
```
For details, see the [Interact documentation](/features/interact).
### Search Web
Resource: **Map & Search**. Performs web searches and returns results with optional content scraping.
**What it does:**
* Searches the web, news, or images
* Returns titles, descriptions, and URLs
* Optionally scrapes the full content of results
**Best for:**
* Research automation
* News monitoring
* Trend discovery
* Finding relevant content
**Example use case:** AI news aggregation (like Example 2 above)
### Crawl Website
Resource: **Crawling**. Recursively discovers and scrapes multiple pages from a website.
**What it does:**
* Follows links automatically
* Scrapes multiple pages in one job
* Can filter URLs by patterns
* Returns a crawl job ID; add a second Firecrawl node with **Get Crawl Status** to read the scraped pages
The Crawling resource also has **Cancel Crawl Job**, **Get Crawl Errors**, **Get Many Active Crawls**, and **Preview Crawl Parameters** (turns a natural language prompt into crawl settings).
**Best for:**
* Full documentation extraction
* Site archiving
* Multi-page data collection
### Map Website
Resource: **Map & Search**. Returns the URLs found on a website without scraping content.
**What it does:**
* Discovers links on a site
* Returns clean URL list
* Fast and lightweight
**Best for:**
* URL discovery
* Sitemap generation
* Planning larger crawls
### Batch Scrape URLs
Resource: **Scraping**. Scrapes multiple URLs in parallel in one job.
**What it does:**
* Processes a list of URLs at once, with the same scrape options for each
* More efficient than loops
* Returns a batch job ID; add **Get Batch Scrape Status** to read all results together
The Scraping resource also has **Get Batch Scrape Errors** and **Cancel Batch Scrape Job**.
**Best for:**
* Processing URL lists
* Bulk data collection
* Large-scale scraping projects
### Agent
Resource: **Agent**. Uses an AI agent to autonomously browse and extract data from websites based on a natural language prompt.
**What it does:**
* Accepts a prompt describing what data you need, plus optional URLs and a JSON schema
* AI agent navigates and extracts information autonomously
* Available as **Extract Data With AI Agent** (waits for results) and **Start AI Agent Job (Async)** (returns a job ID immediately)
* Use **Get Agent Status** to poll for results when using the async operation
**Best for:**
* Complex, multi-page data gathering guided by a prompt
* Extracting information when you don't know the exact page structure
* Research tasks that require navigating multiple pages
**Sync vs. Async:**
* **Extract Data With AI Agent** starts the job and waits for the result in one step, which is simplest for most use cases. The **Max Wait Time** parameter controls how long the node polls before timing out (default: 300 seconds, maximum: 600 seconds). If the agent job takes longer than this, the node returns a `timeout` status with the `jobId`, even though the job may still complete on the Firecrawl side. Pass that ID to **Get Agent Status**, or use the async operation for jobs that may exceed 10 minutes.
* **Start AI Agent Job (Async)** returns a job ID immediately. Add a second Firecrawl node with the **Get Agent Status** operation to retrieve results once the job completes.
For details on the agent feature, see the [Agent documentation](/features/agent).
### Extract Structured Data (legacy)
Resource: **Extract (Legacy)**. Uses AI to extract structured information from a list of URLs based on a prompt or schema, with **Get Extract Status** to read the results.
This resource calls the legacy `/extract` endpoint. For new workflows, use **Agent** instead, or **Scrape URL** with the **JSON** format when you already know the page.
### Browser Sandbox
Resource: **Browser**. Provides a persistent browser session that you can control with code, allowing multi-step browser automation within a single session.
**Operations:**
* **Create Browser Session**: starts a new browser session and returns its `id`
* **Execute Browser Code**: runs Node (Playwright), Python, or Bash code in the session, using the `id` from the Create step as the **Session ID**
* **Get Many Browser Sessions**: lists active or destroyed sessions
* **Delete Browser Session**: destroys a session when you are done
* **Get Browser Context**: returns usage instructions and active sessions for AI agents that call these operations as tools
**Best for:**
* Multi-step browser workflows that require maintaining state across pages
* Dynamic page navigation where the number of steps is not known in advance
* Workflows that use persistent browser profiles to preserve cookies and localStorage across runs
Pass the session `id` from the Create step into each subsequent Execute or Delete step. Use n8n's **Loop Over Items** node to iterate through a dynamic list of pages, calling Execute for each one within the same session.
For details on the Browser Sandbox feature, see the [Browser Sandbox documentation](/features/browser).
### Account
Resource: **Account**. Reads your team's credit usage, token usage, and queue status, so a workflow can check remaining credits before a large job.
## Workflow Templates and Examples
Instead of building from scratch, you can start with pre-built templates. The n8n community has created numerous Firecrawl workflows you can copy and customize.
### Featured Templates
> [card] [Complete n8n Tutorial](https://www.firecrawl.dev/blog/firecrawl-n8n-web-automation)
>
> Build an AI chatbot with web access using Firecrawl and n8n
> [card] [8 Production Workflows](https://www.firecrawl.dev/blog/n8n-web-scraping-workflow-templates)
>
> Ready-to-use templates for lead generation, price monitoring, and more
> [card] [Supabase pgvector RAG Pipeline](https://n8n.io/workflows/13911-scrape-and-ingest-web-content-into-supabase-pgvector-with-firecrawl/)
>
> Scrape pages into embeddings and store in Supabase pgvector for RAG
> [card] [Lead Enrichment with AI](https://n8n.io/workflows/13910-enrich-company-leads-with-firecrawl-openrouter-ai-and-supabase/)
>
> Scrape company websites and extract structured business signals
> [card] [Pinecone RAG Pipeline](https://n8n.io/workflows/13964-scrape-and-ingest-web-pages-into-a-pinecone-rag-stack-with-firecrawl-and-openai/)
>
> Scrape pages into embeddings and store in Pinecone for RAG
> [card] [n8n Community Workflows](https://n8n.io/workflows?search=firecrawl)
>
> Browse hundreds of workflows using Firecrawl
> [card] [Official n8n Integration](https://n8n.io/integrations/firecrawl/)
>
> View official integration documentation
### How to Import Templates
To use a template from the n8n community:
1. Click on a workflow template link
2. Click "**Import template to localhost:5678 self-hosted instance**" button on the template page
3. The workflow opens in your n8n instance
4. Configure credentials for each node
5. Customize settings for your use case
6. Activate the workflow
## Best Practices
Follow these guidelines to build reliable, efficient workflows:
### Testing and Debugging
* Always test workflows manually before activating schedules
* Use the "**Execute Workflow**" button to test the entire flow
* Check output data at each node to verify correctness
* Use the "**Executions**" tab to review past runs and debug issues
### Error Handling
* Add Error Trigger nodes to catch and handle failures
* Set up notifications when workflows fail
* Use the "**Continue On Fail**" setting for non-critical nodes
* Monitor your workflow executions regularly
### Performance Optimization
* Use Batch Scrape for multiple URLs instead of loops
* Set appropriate rate limits to avoid overwhelming target sites
* Cache data when possible to reduce unnecessary requests
* Schedule intensive workflows during off-peak hours
### Security
* Never expose API keys in workflow configurations
* Use n8n's credential system to securely store authentication
* Be careful when sharing workflows publicly
* Follow target websites' terms of service and robots.txt
## Next Steps
You now have the fundamentals to build web scraping automations with Firecrawl and n8n. Here's how to continue learning:
### Explore Advanced Features
* Study webhook configurations for real-time data processing
* Experiment with AI-powered extraction using prompts and schemas
* Build complex multi-step workflows with branching logic
### Join the Community
* [Firecrawl Discord](https://discord.gg/firecrawl) - Get help with Firecrawl and discuss web scraping
* [n8n Community Forum](https://community.n8n.io/) - Ask questions about workflow automation
* Share your workflows and learn from others
### Recommended Learning Path
1. Complete the example workflows in this guide
2. Modify templates from the community library
3. Build a workflow to solve a real problem in your work
4. Explore advanced Firecrawl operations
5. Contribute your own templates to help others
> [!NOTE]
>
> **Need help?** If you're stuck or have questions, the Firecrawl and n8n communities are active and helpful. Don't hesitate to ask for guidance as you build your automations.
## Additional Resources
* [Firecrawl API Documentation](/api-reference/v2-introduction)
* [n8n Documentation](https://docs.n8n.io/)
* [Web Scraping Best Practices](https://www.firecrawl.dev/blog)
# Neuron AI
Source: https://docs.firecrawl.dev/integrations/neuron-ai
Search the web and read pages as Markdown from Neuron AI agents in PHP
> [!NOTE]
>
> **Official Neuron AI docs:** [docs.neuron-ai.dev/agent/tools](https://docs.neuron-ai.dev/agent/tools)
>
> Give PHP agents Firecrawl Search and Scrape, so a Neuron AI agent can find fresh sources and read pages as clean Markdown
## Overview
[Neuron AI](https://neuron-ai.dev) is an agentic framework for PHP. It ships a Firecrawl toolkit, so a Neuron agent can search the web and read any page as clean Markdown during a run.
## Quick start
1. Install Neuron AI 4.1.3 or later:
```bash theme={null}
composer require neuron-core/neuron-ai:^4.1.3
```
2. Get an API key from your [Firecrawl dashboard](https://www.firecrawl.dev/app/api-keys) and set it as `FIRECRAWL_API_KEY`
3. Add the toolkit to your agent:
```php theme={null}
namespace App\Neuron;
use NeuronAI\Agent\Agent;
use NeuronAI\Tools\Toolkits\Firecrawl\FirecrawlToolkit;
class ResearchAgent extends Agent
{
...
protected function tools(): array
{
return [
FirecrawlToolkit::make(
key: getenv('FIRECRAWL_API_KEY')
),
];
}
}
```
## Tools
| Tool | Name the agent sees | What it does |
| - | - | - |
| `FirecrawlSearchTool` | `web_search` | Searches the web, or news when the agent asks for it, with an optional time range |
| `FirecrawlScrapeTool` | `url_reader` | Returns the main content of a page as Markdown |
You can also add either tool on its own, for example `FirecrawlSearchTool::make(key: getenv('FIRECRAWL_API_KEY'))`.
## Get page content with each search result
By default a search returns the title, URL and description of each result. Pass `scrapeOptions` and each result also carries the full page as Markdown, so the agent does not need a second call to read it:
```php theme={null}
use NeuronAI\Tools\Toolkits\Firecrawl\FirecrawlSearchTool;
FirecrawlSearchTool::make(key: getenv('FIRECRAWL_API_KEY'))->withOptions([
'limit' => 5,
'scrapeOptions' => [
'formats' => ['markdown'],
'onlyMainContent' => true,
],
]);
```
`withOptions()` replaces the defaults and accepts any [search parameter](/api-reference/endpoint/search). The search query always comes from the agent.
## Resources
* [Neuron AI tools and toolkits](https://docs.neuron-ai.dev/agent/tools)
* [Firecrawl search docs](/features/search)
* [Firecrawl scrape docs](/features/scrape)
# Pipedream
Source: https://docs.firecrawl.dev/integrations/pipedream
Add Firecrawl scrape, crawl, search, map, and extract steps to Pipedream workflows
> [!NOTE]
>
> **Official Pipedream app:** [pipedream.com/apps/firecrawl](https://pipedream.com/apps/firecrawl/)
>
> Add Firecrawl steps to Pipedream workflows triggered by schedules, webhooks, or other apps
## Overview
Use the Firecrawl Pipedream app to scrape pages, crawl sites, search the web, map URLs, and extract structured data as actions in your workflows.
## Quick start
1. Open the [Firecrawl app on Pipedream](https://pipedream.com/apps/firecrawl/)
2. Connect your Firecrawl API key
3. Add Firecrawl actions to a new or existing workflow
## What you can do
| Action | Use case |
| - | - |
| **Scrape Page** | Pull page content when a webhook or schedule fires |
| **Crawl URL** | Start a multi page crawl job (poll with **Get Crawl Data**) |
| **Search** | Discover sources before downstream steps |
| **Map URL** | List URLs on a site, optionally filtered by a search term |
| **Extract Data** | Pull structured data from one or more URLs (check a running job with **Get Extract Status**) |
## Resources
* [Pipedream Firecrawl app](https://pipedream.com/apps/firecrawl/)
* [Firecrawl API introduction](/api-reference/v2-introduction)
# Praison AI
Source: https://docs.firecrawl.dev/integrations/praison
Scrape the web with Firecrawl as a Praison AI tool
> [!NOTE]
>
> **Official Praison docs:** [praison.ai/docs/tools/external/firecrawl](https://praison.ai/docs/tools/external/firecrawl)
>
> Give Praison agents live web scraping through Firecrawl
## Overview
Praison AI can call Firecrawl as a tool so agents scrape web pages and use the cleaned content during runs.
## Quick start
1. Install the agents package, the Praison tools package, and the Firecrawl SDK:
```bash theme={null}
pip install praisonaiagents praisonai-tools firecrawl-py
```
2. Set `FIRECRAWL_API_KEY` for Firecrawl cloud
3. Pass a Firecrawl tool to your agent:
```python theme={null}
from praisonaiagents import Agent
from praisonai_tools import FirecrawlTool
agent = Agent(
name="WebScraper",
instructions="You are a web scraping assistant. Use Firecrawl to extract content.",
tools=[FirecrawlTool()],
)
print(agent.chat("Scrape the content from https://praison.ai/docs"))
```
## What you can do
| Capability | Use case |
| - | - |
| **Scrape** | Fetch cleaned page content into agent context (`FirecrawlTool.scrape`) |
| **Crawl** | Collect pages from a site (`FirecrawlTool.crawl(url, limit=10)`) |
| **Search** | Find pages for a query (`FirecrawlTool.search(query, limit=5)`) |
## Resources
* [Praison `FirecrawlTool` guide](https://praison.ai/docs/tools/external/firecrawl)
* [Firecrawl scrape docs](/features/scrape)
# Replit
Source: https://docs.firecrawl.dev/integrations/replit
Official Replit Connector for Firecrawl web search, scraping, and browser interaction
> [!NOTE]
>
> **Official Replit Connector:** [Open Integrations in Replit](https://replit.com/~?settings.show=true\&settings.tab=integrations)
>
> Search, scrape, and interact with the web • Built for Replit Agent • Core, Pro, or Enterprise plan required
## Replit Connector Overview
Firecrawl is available as an official Replit Connector. Once connected in your workspace, Replit Agent can use Firecrawl while building apps that need live web data.
> [card] Built for Replit Agent
>
> Enable Firecrawl in Integrations so Agent can search, scrape, and interact while building
> [card] Start without an API key
>
> Default: billed to your Replit account. Custom configuration: use a Firecrawl key or claim the 10,000-credit offer
## Firecrawl Capabilities in Replit
Replit Agent can build apps with Firecrawl's **search**, **scrape**, **interact**, **monitor**, **crawl**, and **parse** endpoints. Your connector configuration determines which account supplies the API key and pays for Firecrawl usage; it does not change which Firecrawl APIs an app can use.
> [accordion] Search
>
> Find relevant live web sources and excerpts for research, competitor discovery, and enrichment.
>
> **Use Cases:** Competitor discovery, research assistants, lead enrichment.
> [accordion] Scrape
>
> Turn any URL into clean data ready for LLMs, including summaries, structured fields, and app content.
>
> **Use Cases:** Product data extraction, article scraping, company page enrichment.
> [accordion] Interact
>
> Click, fill forms, and navigate multi step flows on dynamic websites.
>
> **Use Cases:** Form workflows, dynamic pages, multi step data collection.
> [accordion] Monitor
>
> Watch pages, sites, or the web for meaningful updates on a schedule. Available through the Firecrawl API in apps you build.
>
> **Use Cases:** Keyword monitoring, changelog alerts, competitive tracking.
> [accordion] Crawl
>
> Discover and scrape reachable pages across a site. Available through the Firecrawl API in apps you build.
>
> **Use Cases:** Documentation ingestion, full site extraction, multi page research.
> [accordion] Parse
>
> Convert PDFs and Word documents into Markdown or JSON. Available through the Firecrawl API in apps you build.
>
> **Use Cases:** Report parsing, document knowledge bases, file to structured data flows.
## Getting Started
**1. Open Integrations**
In a Replit workspace on a **Core**, **Pro**, or **Enterprise** plan, open **Integrations**.
**2. Connect Firecrawl**
Select **Enable new connector**, choose **Firecrawl**, use the default configuration, and select **Submit**. On Core and Pro, an account admin manages the connector for the collaborative workspace. On Enterprise, an admin manages it for the organization.
**3. Choose billing**
Keep **Use Replit default configurations** selected (no Firecrawl account needed), or open **Manage**, select **Use custom configurations**, and either paste your Firecrawl API key or claim the 10,000-credit offer, which provisions and saves a new key.
**4. Verify the connection**
In an app in the connected workspace, ask Agent to run a server-side connector test:
```text theme={null}
Run a server-side Firecrawl test.
Use the Replit connector.
Scrape https://example.com.
Use the connector-relative /scrape path.
Return only the page title and first paragraph.
Do not reveal or ask me for an API key.
Do not publish the app.
```
Confirm the proposed Firecrawl integration if prompted. The connection is working when the app's server-side connector call returns **Example Domain** with the page's first paragraph and does not ask you to supply an API key in chat or application code.
> [!NOTE]
>
> Replit's Firecrawl connector base URL already includes `/v2`. With `@replit/connectors-sdk`, use the connector-relative path `/scrape`, not `/v1/scrape`.
## Billing and credentials
> [accordion] Replit default
>
> * **Credential and billing:** Replit supplies its API key. Firecrawl requests are billed through Replit and deducted from Replit credits.
> * **Firecrawl account:** Not required.
> * **10,000-credit offer:** Not included.
> [accordion] Claim partner credits
>
> * **Credential and billing:** Replit provisions a new Firecrawl key. Firecrawl usage consumes the claimed partner credits.
> * **Firecrawl account:** A partner-associated account and key are provisioned.
> * **10,000-credit offer:** Included once per user per partner and expires 3 months after application.
> * **Success signal:** The offer shows **Claimed**, and Replit states that it is using your API key instead of billing connector usage through Replit.
> [accordion] Existing Firecrawl key
>
> * **Credential and billing:** You supply the key. Usage follows that Firecrawl account's plan, credits, and limits.
> * **Firecrawl account:** Required.
> * **10,000-credit offer:** Not added to the existing key.
> [!WARNING]
>
> Keep Firecrawl API keys in the connector's custom configuration. Do not paste keys into Agent prompts, application source, screenshots, logs, or pull requests.
> [!TIP]
>
> **Launch offer:** Open **Manage**, select **Use custom configurations**, and claim **10,000 free Firecrawl credits** to provision a **new** key. The offer applies once per user per partner, expires 3 months after it is applied, and uses Firecrawl's Free-plan limits. Pasting an existing key does not add the offer to that key. Default Replit billing does not include it. See [Partner credits](/partner-credits) for full terms.
## Usage Patterns
> [tab] Competitor analysis
>
> **Search + scrape competitors**
>
> 1. Ask Agent to find competitors with Firecrawl `/search`
> 2. Scrape each competitor site for key context
> 3. Present names, summaries, and details in a simple UI
>
> **Example prompt:**
>
> ```
> Build a competitor analysis app using Firecrawl. Search for competitors, scrape their sites, and show summaries.
> ```
> [tab] Web monitoring
>
> **Keyword monitoring app with `/monitor`**
>
> Uses the Firecrawl API in the app your Agent builds.
>
> 1. Ask Agent to build an app that calls Firecrawl `/monitor`
> 2. Let users add keywords and target sites
> 3. Run checks on a schedule, plus manual scans, and surface meaningful changes
>
> **Example prompt:**
>
> ```
> Build a keyword monitoring app with Firecrawl that watches selected sites and alerts on meaningful changes.
> ```
## Industry Use Cases
> [accordion] Ecommerce
>
> * Competitor pricing and assortment tracking
> * Product availability checks
> * Review and listing aggregation
> [accordion] Marketing & SEO
>
> * Competitor content monitoring
> * SEO audits from live pages
> * Research brief generation
> [accordion] Sales & Lead Gen
>
> * Company enrichment from public web pages
> * Lead research assistants
> * Account brief generation for outbound
> [accordion] Support & Knowledge
>
> * Always fresh documentation assistants
> * Help center and changelog monitoring
> * Internal tools that answer from live sources
## Official Blog Post
> [card] [Firecrawl is now an official Replit Connector](https://www.firecrawl.dev/blog/firecrawl-official-replit-connector)
>
> Launch overview: connect Firecrawl in your Replit workspace and build apps with live web data.
## Troubleshooting
### Firecrawl is missing from Integrations
* Confirm the workspace is on Core, Pro, or Enterprise.
* Ask the workspace or organization admin to open **Integrations → Enable new connector** and enable Firecrawl.
* Confirm the app belongs to the workspace or organization where Firecrawl was enabled.
### Agent asks for an API key
* Confirm Firecrawl is enabled for the current workspace or organization.
* Ask Agent to attach the **Firecrawl connector** to the app and use its server-side connector binding.
* If you intend to use your own key, open **Manage**, select **Use custom configurations**, and add it there instead of pasting it into the prompt.
### Agent reports withheld credentials
An inline Agent query can report an empty credential result even when Firecrawl is connected. Ask Agent to run the test through the app's server-side `@replit/connectors-sdk` binding instead. For Firecrawl v2 scraping, use the connector-relative path `/scrape`; using `/v1/scrape` produces an incorrect `/v2/v1/scrape` request.
If **Manage** shows the custom configuration as **Claimed** and says Replit is using your API key, the partner-credit claim succeeded even if the inline Agent sandbox cannot read the credential directly.
### The credit-claim option is unavailable
* Confirm you selected **Use custom configurations** under **Manage**.
* Check that the user has not already received the Replit partner offer; it applies once per user per partner.
* Ask the workspace or organization admin to confirm you have access to the connector configuration.
Replit usage can take up to 30 minutes to appear in the usage dashboard.
## FAQs
> [accordion] Do I need a Firecrawl API key?
>
> No. By default, the connector runs on Replit's API key and usage is billed to your Replit account per request. Under **Manage**, select **Use custom configurations** to paste your own Firecrawl API key or claim the 10,000-credit offer, which provisions a new key for you. The offer applies once per user per partner and expires after 3 months.
> [accordion] Which Replit plans include the Connector?
>
> Replit integrations are available on **Core**, **Pro**, or **Enterprise**. Open Integrations in your workspace and search for Firecrawl.
> [accordion] How is this different from Replit using Firecrawl internally?
>
> Replit Agent has used Firecrawl behind the scenes for fresh docs and web content. The official Connector makes Firecrawl available to your apps from the Integrations catalog.
## Related Resources
> [card] [Manage Replit Connectors](https://docs.replit.com/replitai/managing-connectors)
>
> Plan availability, setup, access, and connector administration
> [card] [Replit Agent Integrations](https://docs.replit.com/features/integrations/overview)
>
> How Agent finds and uses integrations
> [card] [Customer story](https://www.firecrawl.dev/blog/how-replit-uses-firecrawl-to-power-ai-agents)
>
> How Replit powers Agent with Firecrawl
# Stripe Projects
Source: https://docs.firecrawl.dev/integrations/stripe-projects
Provision a Firecrawl account, API key, and plan from the Stripe Projects CLI
> [!NOTE]
>
> **Official Stripe docs:** [docs.stripe.com/projects](https://docs.stripe.com/projects) · [Firecrawl in the provider directory](https://projects.dev/providers/)
>
> Firecrawl, the context API for AI agents, is a Stripe Projects provider. Add it to any project with `stripe projects add firecrawl/api`.
## Overview
[Stripe Projects](https://projects.dev) provisions third-party services from the terminal and syncs their credentials to your `.env`. Firecrawl is one of the providers, so one command creates a Firecrawl account, writes an API key into your project, and lets you pick a plan. Paid plans bill through the payment method on your Stripe account.
| You get | Detail |
| - | - |
| **Account** | A Firecrawl account keyed on your Stripe account's email. If that email already has a Firecrawl account, it is reused. |
| **API key** | A workspace API key written to your `.env`. One key covers every Firecrawl endpoint. |
| **Plan** | Free by default. Upgrade to Hobby, Standard, or Growth, monthly or yearly, from the CLI. |
| **Dashboard** | `stripe projects open firecrawl` signs you in to the Firecrawl dashboard. |
## Quick start
```bash theme={null}
stripe plugin install projects
stripe projects init
stripe projects add firecrawl/api --name firecrawl
stripe projects env --pull
```
`--name firecrawl` sets the local resource name, which becomes the prefix of the variables the CLI writes. With it the key lands in `FIRECRAWL_API_KEY`, which the Firecrawl [SDKs](/sdks/overview) and [CLI](/sdks/cli) read automatically. Without it, the resource is called `firecrawl-api` and the key lands in `FIRECRAWL_API_API_KEY`.
The CLI also writes `FIRECRAWL_API_BASE_URL` and `FIRECRAWL_DOCUMENTATION_URL`. Both are informational. The SDKs read `FIRECRAWL_API_URL`, and only for self-hosted deployments; a Stripe-provisioned account uses the hosted API, which is the default, so leave `FIRECRAWL_API_URL` unset.
From here, follow the [Node.js](/quickstarts/nodejs) or [Python](/quickstarts/python) quickstart, or the [SDK overview](/sdks/overview) for other languages. The key works with every endpoint: [search](/features/search), [scrape](/features/scrape), [crawl](/features/crawl), [map](/features/map), [interact](/features/interact), [agent](/features/agent), [parse](/features/parse), and [monitor](/features/monitoring).
## Catalog
Run `stripe projects catalog firecrawl` for the live list. The CLI shows the final price before you confirm anything.
| Slug | Kind | What it is |
| - | - | - |
| `firecrawl/api` | Service | The Firecrawl API. Provisions the account and the API key. Free tier by default. |
| `firecrawl/free` | Plan | The Free plan. No card needed. |
| `firecrawl/hobby` | Plan | The Hobby plan. Asks for `Monthly` or `Yearly`. |
| `firecrawl/standard` | Plan | The Standard plan. Asks for `Monthly` or `Yearly`. |
| `firecrawl/growth` | Plan | The Growth plan. Asks for `Monthly` or `Yearly`. |
Plans and prices match [firecrawl.dev/pricing](https://www.firecrawl.dev/pricing). Scale and Enterprise are not offered through Stripe Projects; [talk to us](https://www.firecrawl.dev/enterprise) for those.
## Manage the resource
```bash theme={null}
# Add a payment method to your Stripe account once
stripe projects billing add
# Move to a paid plan; the CLI asks which plan and which billing interval
stripe projects upgrade firecrawl
# Rotate the API key, then pull the new value into .env
stripe projects rotate firecrawl
stripe projects env --pull
# Remove Firecrawl from this project
stripe projects remove firecrawl
```
Upgrades use a Stripe [Shared Payment Token](https://docs.stripe.com/agentic-commerce/concepts/shared-payment-tokens), so Firecrawl never sees your card details. The plan shows up in your Firecrawl dashboard like any other subscription. To go back to Free, run `stripe projects downgrade firecrawl` and pick `free`, or change the plan from [Billing](https://www.firecrawl.dev/app/settings?tab=billing) in the dashboard.
## Accounts and billing
* **One Stripe account, one Firecrawl account.** Firecrawl looks up your Stripe account's email. A new email gets a new Firecrawl account, already verified, with a team and a default API key. An email that already has a Firecrawl account reuses the team it linked through Stripe before; the first time, it gets a new team named `via stripe` in its own organization, so Stripe billing stays separate from your other Firecrawl teams.
* **Everyone on the Stripe account can act on the linked Firecrawl account** through Projects, in line with Stripe's model. The Firecrawl dashboard shows the account under the Stripe account's email.
* **Paid plans are Firecrawl subscriptions**, paid with your Shared Payment Token and reported by `stripe projects spend`. Credits, rate limits, and features match the same plan bought on firecrawl.dev.
* **Removing the resource cancels its plan.** The account and API key stay.
## Coding agents
Stripe Projects is built for agents as much as for people. Stripe publishes a [skill](https://docs.stripe.com/projects#coding-agent) that teaches Claude Code, Cursor, Codex, and other agents the Projects CLI, and `stripe projects llm-context` bundles this page with the guidance of every other provider in the project.
```bash theme={null}
npx skills add https://docs.stripe.com --skill stripe-projects -g -y
```
When an agent provisions Firecrawl: copy the slug from `stripe projects catalog firecrawl --json` rather than guessing it, pass `--name firecrawl`, run `stripe projects env --pull` and use `FIRECRAWL_API_KEY` from the environment rather than editing `.env`, and leave paid upgrades to the human, since they charge the card on the Stripe account. `--accept-tos` accepts the [Firecrawl Terms of Service](https://www.firecrawl.dev/terms-of-service) on the human's behalf, so confirm with them first. The rest of the agent setup is on [Build with AI](/ai-onboarding).
## Troubleshooting
| What you see | What to do |
| - | - |
| `Provider connection requires re-authentication` | Run `stripe projects link firecrawl`, then retry. |
| `Unknown provider or category: firecrawl` | Run `stripe plugin upgrade projects`, then `stripe projects catalog firecrawl --refresh`. |
| Paid provisioning fails | Run `stripe projects billing add` to confirm a payment method. If your Firecrawl account already has a paid plan, change it from the dashboard instead. |
| The key lands in `FIRECRAWL_API_API_KEY` | You provisioned without `--name`. Export it as `FIRECRAWL_API_KEY`, or remove the resource and add it again with `--name firecrawl`. |
Still stuck? Email [help@firecrawl.com](mailto:help@firecrawl.com) with the Stripe request id from the error.
## Resources
* [Stripe Projects docs](https://docs.stripe.com/projects)
* [Provider directory](https://projects.dev/providers/) and [templates](https://projects.dev/templates/); the Shopify Trending Products template bundles Firecrawl
* [Firecrawl pricing](https://www.firecrawl.dev/pricing)
* Other ways to get a key: the [dashboard](https://www.firecrawl.dev/app/api-keys), the [Vercel Marketplace](/quickstarts/vercel-marketplace), or [Firecrawl for Platforms](/firecrawl-for-platforms) if you run a platform
# Tines
Source: https://docs.firecrawl.dev/integrations/tines
Call Firecrawl search, scrape, extract, map, and crawl from Tines stories with HTTP Request actions
> [!NOTE]
>
> **Tines docs:** [HTTP Request action](https://www.tines.com/docs/actions/types/http-request/) and [Credentials](https://www.tines.com/docs/credentials/)
>
> Add live web data from Firecrawl to Tines stories
## Overview
Tines stories can call any REST API with the HTTP Request action. Pointing that action at the Firecrawl API lets a story search the web, scrape a page into markdown, pull structured data, map a site, or crawl it, and pass the result to the next action in the story.
## Quick start
1. [Create a Firecrawl API key](https://www.firecrawl.dev/app/api-keys)
2. In Tines, open **Credentials**, create a **Text** credential named `firecrawl`, and paste the key as its value
3. Add an **HTTP Request** action to your story and configure it as shown below
Referencing the key as `<>` keeps it out of the action configuration.
## Scrape a page
This action sends a scrape request and emits the page as markdown:
```json theme={null}
{
"url": "https://api.firecrawl.dev/v2/scrape",
"method": "post",
"content_type": "json",
"headers": {
"Authorization": "Bearer <>"
},
"payload": {
"url": "https://example.com",
"formats": ["markdown"],
"integration": "_tines"
}
}
```
Replace `https://example.com` with a URL from an upstream event, for example `<>`. The optional `integration` field labels requests that come from Tines.
## What you can do
| Capability | Endpoint | Use case |
| - | - | - |
| **Search** | `POST /v2/search` | Find sources for a question or alert before later actions |
| **Scrape** | `POST /v2/scrape` | Turn a URL into markdown or structured JSON |
| **Extract** | `POST /v2/scrape` with a `json` format | Pull fields such as a title or product details with a prompt and schema |
| **Map** | `POST /v2/map` | List the URLs on a site |
| **Crawl** | `POST /v2/crawl` | Gather pages across a site, then poll for the result |
All endpoints use the base URL `https://api.firecrawl.dev`, the same `Authorization` header, and a JSON body.
## Search the web
```json theme={null}
{
"url": "https://api.firecrawl.dev/v2/search",
"method": "post",
"content_type": "json",
"headers": {
"Authorization": "Bearer <>"
},
"payload": {
"query": "firecrawl web scraping",
"limit": 5,
"sources": ["web"],
"integration": "_tines"
}
}
```
## Extract structured data
Set the `formats` entry to the `json` type with a prompt and a JSON schema:
```json theme={null}
{
"url": "https://api.firecrawl.dev/v2/scrape",
"method": "post",
"content_type": "json",
"headers": {
"Authorization": "Bearer <>"
},
"payload": {
"url": "https://example.com",
"formats": [
{
"type": "json",
"prompt": "Extract the page title",
"schema": {
"type": "object",
"properties": { "title": { "type": "string" } }
}
}
],
"integration": "_tines"
}
}
```
## Crawl a site
A crawl runs asynchronously. Use one action to start it and a second action to read the result.
**Start the crawl** with `POST /v2/crawl`:
```json theme={null}
{
"url": "https://api.firecrawl.dev/v2/crawl",
"method": "post",
"content_type": "json",
"headers": {
"Authorization": "Bearer <>"
},
"payload": {
"url": "https://example.com",
"limit": 10,
"integration": "_tines"
}
}
```
The response includes an `id`. **Check the status** with a second HTTP Request action that reads the crawl by that `id`, and repeat it until the `status` is `completed`:
```json theme={null}
{
"url": "https://api.firecrawl.dev/v2/crawl/<>",
"method": "get",
"headers": {
"Authorization": "Bearer <>"
}
}
```
Here `start_crawl` is the name of the action that started the crawl.
## Resources
* [Tines HTTP Request action](https://www.tines.com/docs/actions/types/http-request/)
* [Tines credentials](https://www.tines.com/docs/credentials/)
* [Firecrawl API introduction](/api-reference/v2-introduction)
* [Firecrawl scrape docs](/features/scrape)
* [Firecrawl crawl docs](/features/crawl)
# Zapier
Source: https://docs.firecrawl.dev/integrations/zapier
Official tutorials and Zapier integration templates for Firecrawl automation
> [!NOTE]
>
> **Official Zapier Integration:** [zapier.com/apps/firecrawl/integrations](https://zapier.com/apps/firecrawl/integrations)
>
> Connect with 9,000+ apps • No-code automation • Pre-built Zap templates • Cloud-based
## Official Blog Post
> [card] [How Zapier uses Firecrawl](https://www.firecrawl.dev/blog/how-zapier-uses-firecrawl-to-power-chatbots)
>
> Real-world case study: How Zapier integrated Firecrawl into Zapier Chatbots in a single afternoon.
## Popular Integrations
> [accordion] Data Storage & Databases
>
> ### Google Sheets
>
> → [View Integration](https://zapier.com/apps/google-sheets/integrations/firecrawl)
>
> Track competitor data, centralize marketing insights, and automate data collection.
>
> **Best For:** Business owners, marketing teams
>
> ***
>
> ### Airtable
>
> → [View Integration](https://zapier.com/apps/airtable/integrations/firecrawl)
>
> Build lead generation databases and content aggregation systems with structured storage.
>
> **Best For:** Sales teams, project managers
>
> ***
>
> ### Zapier Tables
>
> → [View Integration](https://zapier.com/apps/zapier-tables/integrations/firecrawl)
>
> No-code database automation for employee onboarding and centralized lead management.
>
> **Best For:** HR teams, operations
> [accordion] Communication & Notifications
>
> ### Slack
>
> → [View Integration](https://zapier.com/apps/slack/integrations/firecrawl)
>
> Get website change notifications, competitor monitoring alerts, and market intelligence updates.
>
> **Best For:** Marketing teams, product managers
>
> ***
>
> ### Telegram
>
> → [View Integration](https://zapier.com/apps/telegram/integrations/firecrawl)
>
> Instant price alerts, breaking news notifications, and real-time monitoring.
>
> **Best For:** Traders, news enthusiasts
> [accordion] CRM & Sales
>
> ### HubSpot
>
> → [View Integration](https://zapier.com/apps/hubspot/integrations/firecrawl)
>
> Contact enrichment, lead scoring with web data, and marketing automation.
>
> **Best For:** Marketing ops, sales ops
>
> ***
>
> ### Pipedrive
>
> → [View Integration](https://zapier.com/apps/pipedrive/integrations/firecrawl)
>
> Lead enrichment from websites and competitor intelligence tracking.
>
> **Best For:** Sales teams, account executives
>
> ***
>
> ### Attio
>
> → [View Integration](https://zapier.com/apps/attio/integrations/firecrawl)
>
> Modern CRM data enrichment and relationship intelligence.
>
> **Best For:** Modern sales teams
> [accordion] Productivity & Documentation
>
> ### Google Docs
>
> → [View Integration](https://zapier.com/apps/google-docs/integrations/firecrawl)
>
> Automated report generation, research documentation, and content aggregation.
>
> **Best For:** Researchers, content creators
>
> ***
>
> ### Notion
>
> → [View Integration](https://zapier.com/apps/notion/integrations/firecrawl)
>
> Knowledge base updates, research library building, and content curation.
>
> **Best For:** Product teams, researchers
> [accordion] Zapier Native Tools
>
> ### Schedule by Zapier
>
> → [View Integration](https://zapier.com/apps/schedule/integrations/firecrawl)
>
> Run hourly, daily, weekly, or monthly scraping automatically.
>
> ***
>
> ### Zapier Interfaces
>
> → [View Integration](https://zapier.com/apps/interfaces/integrations/firecrawl)
>
> Build custom internal tools with form-based scraping and team dashboards.
>
> **Best For:** Operations teams
>
> ***
>
> ### Zapier Chatbots
>
> → [View Integration](https://zapier.com/apps/zapier-chatbots/integrations/firecrawl)
>
> AI chatbots with live web knowledge for customer support and lead generation.
>
> > [!NOTE]
> >
> > Official Zapier product uses Firecrawl internally
## Firecrawl Actions
| Action | Use Case |
| - | - |
| **/Scrape Page** | Quick single-page data capture |
| **/Crawl Website** | Full site scraping with multiple pages |
| **/Extract Data** | AI-powered extraction with custom schemas |
| **/Search Data** | Research automation with search + scrape |
| **/Map Data** | SEO analysis and site structure mapping |
| **Run Agent** | Gather data from the web with a prompt, optional URLs and schema, and a credit cap |
| **Get Data From /Crawl**, **Get Data From /Extract**, **Get Agent Status** | Read the results of an earlier crawl, extract, or agent job |
| **Cancel Agent** | Stop a running agent job |
## Quick Reference
> [card] Getting Started
>
> 1. Sign up at [firecrawl.dev](https://firecrawl.dev)
> 2. Get your API key
> 3. Create a Zap in Zapier
> 4. Connect Firecrawl with your API key
> 5. Choose your workflow and activate
> [card] Best Practices
>
> * Use `/Scrape Page` for single pages (faster)
> * Schedule strategically (hourly/daily/weekly)
> * Test in Firecrawl playground first
> * Add error handling for failed scrapes
> * Use filters to prevent unnecessary runs
## Industry Use Cases
> [accordion] E-commerce
>
> * Price monitoring across competitors
> * Product availability tracking
> * Review aggregation
> [accordion] Real Estate
>
> * Listing aggregation
> * Market trend analysis
> * Property data collection
> [accordion] Marketing
>
> * Competitor content tracking
> * SEO monitoring
> * Backlink analysis
> [accordion] Finance
>
> * Market data collection
> * News aggregation
> * Regulatory filing monitoring
> [accordion] Recruitment
>
> * Job posting aggregation
> * Company research automation
> * Candidate information enrichment
## Zapier vs n8n
| Feature | Zapier | n8n |
| - | - | - |
| **Setup** | No-code, cloud-based | Self-hosted or cloud |
| **Pricing** | Per-task pricing | Execution-based |
| **Integrations** | 9,000+ apps | 1,000+ apps and services |
| **Best For** | Quick automation, non-technical users | Custom logic, developers |
> [!TIP]
>
> **Pro Tip:** Start with Zapier's pre-built templates and customize as needed. Perfect for quick, no-code automation!
# CLI
Source: https://docs.firecrawl.dev/sdks/cli
Firecrawl skills are an easy way for AI agents such as Codex, Claude Code, Cursor, and OpenCode to use Firecrawl through the CLI.
Search, scrape, parse, crawl, map, interact, run agent jobs, and monitor changes directly from the terminal. The Firecrawl CLI is the context API for AI agents on the command line: it works standalone, or with skills that AI coding agents like Codex, Claude Code, Cursor, Hermes Agent, and OpenCode can discover and use automatically.
## Installation
If you are using an AI agent like Codex, Claude Code, Cursor, or OpenCode, you can install the Firecrawl skills below and the agent will set them up for you.
```bash theme={null}
npx -y firecrawl-cli@latest init --all --browser
```
* `--all` skips agent selection and initializes every detected agent
* `--browser` opens the browser for Firecrawl authentication automatically
> [!NOTE]
>
> After installing the skills, restart your agent for it to discover them.
You can also manually install the Firecrawl CLI globally using npm:
```bash CLI theme={null}
# Install globally with npm
npm install -g firecrawl-cli
```
## Authentication
Before using the CLI, you need to authenticate with your Firecrawl API key.
> [!NOTE]
>
> **Some CLI commands work without logging in.** With no API key configured, supported commands fall back to the keyless free tier — free, but rate-limited per IP. See [Rate Limits](/rate-limits#keyless-no-api-key) for the current keyless command list and caveats. [Sign up for a free key](https://firecrawl.dev) for 1,000 credits and higher limits; the CLI uses it automatically once configured.
### Login
```bash CLI theme={null}
# Interactive login (opens browser or prompts for API key)
firecrawl login
# Login with browser authentication (recommended for agents)
firecrawl login --browser
# Login with API key directly
firecrawl login --api-key fc-YOUR-API-KEY
# Or set via environment variable
export FIRECRAWL_API_KEY=fc-YOUR-API-KEY
```
### View Configuration
```bash CLI theme={null}
# View current configuration and authentication status
firecrawl view-config
```
### Logout
```bash CLI theme={null}
# Clear stored credentials
firecrawl logout
```
### Connect the CLI to self-hosted Firecrawl
First, get one scrape working with the [self-hosting guide](/contributing/self-host). Then point the CLI at that API with `--api-url` or `FIRECRAWL_API_URL`:
```bash CLI theme={null}
# Use a local Firecrawl instance (no API key required)
firecrawl --api-url http://localhost:3002 scrape https://example.com
# Or set via environment variable
export FIRECRAWL_API_URL=http://localhost:3002
firecrawl scrape https://example.com
# Configure and persist the custom API URL
firecrawl config --api-url http://localhost:3002
```
When you use a custom API URL instead of `https://api.firecrawl.dev`, the CLI skips Firecrawl Cloud API-key authentication. That matches the trusted-network quickstart, where `USE_DB_AUTHENTICATION=false`.
> [!WARNING]
>
> Keep an unauthenticated API on a trusted network. If you add an authentication
> proxy or another access-control layer, verify that the CLI can send the
> credentials that layer requires before depending on this path.
The CLI can call only the capabilities enabled in your deployment. Check [self-hosted feature support](/contributing/self-host#self-hosted-feature-support) before using Cloud-only or provider-dependent commands.
### Check Status
Verify installation, authentication, and view rate limits:
```bash CLI theme={null}
firecrawl --status
```
Output when ready:
```
🔥 firecrawl cli v1.16.2
● Authenticated via FIRECRAWL_API_KEY
Concurrency: 0/100 jobs (parallel scrape limit)
Credits: 500,000 remaining
```
* **Concurrency**: Maximum parallel jobs. Run parallel operations close to this limit but not above.
* **Credits**: Remaining API credits. Each scrape/crawl consumes credits.
## Commands
> [!NOTE]
>
> The hidden `firecrawl browser` command is deprecated for agent workflows. Use `firecrawl scrape ` first, then `firecrawl interact ...` with the resulting scrape session.
### Scrape
Scrape a single URL and extract its content in various formats.
> [!TIP]
>
> Use `--only-main-content` to get clean output without navigation, footers, and
> ads. This is recommended for most use cases where you want just the article or
> main page content.
```bash CLI theme={null}
# Scrape a URL (default: markdown output)
firecrawl https://example.com
# Or use the explicit scrape command
firecrawl scrape https://example.com
# Recommended: use --only-main-content for clean output without nav/footer
firecrawl https://example.com --only-main-content
```
#### Output Formats
```bash CLI theme={null}
# Get HTML output
firecrawl https://example.com --html
# Multiple formats (returns JSON)
firecrawl https://example.com --format markdown,links
# Get images from a page
firecrawl https://example.com --format images
# Get a summary of the page content
firecrawl https://example.com --format summary
# Track changes on a page
firecrawl https://example.com --format changeTracking
# Available formats: markdown, html, rawHtml, links, screenshot, json, images, summary, changeTracking, attributes, branding, product
```
#### Scrape Options
```bash CLI theme={null}
# Extract only main content (removes navs, footers)
firecrawl https://example.com --only-main-content
# Wait for JavaScript rendering
firecrawl https://example.com --wait-for 3000
# Take a screenshot
firecrawl https://example.com --screenshot
# Extract structured JSON with a schema
firecrawl https://example.com --format json --schema '{"type":"object","properties":{"title":{"type":"string"}}}'
# Run lightweight scrape actions before extraction
firecrawl https://example.com --actions '[{"type":"wait","milliseconds":1000}]'
# Select proxy mode
firecrawl https://example.com --proxy basic
# Redact personally identifiable information
firecrawl https://example.com --redact-pii
# Include/exclude specific HTML tags
firecrawl https://example.com --include-tags article,main
firecrawl https://example.com --exclude-tags nav,footer
# Save output to file
firecrawl https://example.com -o output.md
# Pretty print JSON output
firecrawl https://example.com --format markdown,links --pretty
# Force JSON output even with single format
firecrawl https://example.com --json
# Show request timing information
firecrawl https://example.com --timing
```
**Available Options:**
| Option | Short | Description |
| - | - | - |
| `--url ` | `-u` | URL to scrape (alternative to positional argument) |
| `--format ` | `-f` | Output formats (comma-separated): `markdown`, `html`, `rawHtml`, `links`, `screenshot`, `json`, `images`, `summary`, `changeTracking`, `attributes`, `branding` |
| `--html` | `-H` | Shortcut for `--format html` |
| `--only-main-content` | | Extract only main content |
| `--wait-for ` | | Wait time in milliseconds for JS rendering |
| `--screenshot` | | Take a screenshot |
| `--full-page-screenshot` | | Take a full page screenshot |
| `--include-tags ` | | HTML tags to include (comma-separated) |
| `--exclude-tags ` | | HTML tags to exclude (comma-separated) |
| `--schema ` | | JSON schema for structured extraction |
| `--schema-file ` | | Path to JSON schema file |
| `--actions ` | | JSON actions array to run during scrape |
| `--actions-file ` | | Path to JSON actions file |
| `--proxy ` | | Proxy mode for scraping (for example, `auto` or `basic`) |
| `--redact-pii` | | Redact personally identifiable information from returned content |
| `--output ` | `-o` | Save output to file |
| `--json` | | Force JSON output even with single format |
| `--pretty` | | Pretty print JSON output |
| `--timing` | | Show request timing and other useful information |
| `--alexandria ` | | Run an [Alexandria](/features/alexandria) tool, given as `provider/capability`, instead of scraping a URL. Repeat to run more than one tool |
| `--options ` | | JSON input for each Alexandria tool, in the same order |
| `--request-id ` | | Request ID for an Alexandria run. Use the same ID to recover the same run |
| `--domain-tools` | | Also return Alexandria tools that match the scraped URL. The tools do not run |
***
### Search
Search the web and optionally scrape the results.
```bash CLI theme={null}
# Search the web
firecrawl search "web scraping tutorials"
# Limit results
firecrawl search "AI news" --limit 10
# Pretty print results
firecrawl search "machine learning" --pretty
```
#### Search Options
```bash CLI theme={null}
# Search specific sources
firecrawl search "AI" --sources web,news,images
# Search with category filters
firecrawl search "react hooks" --categories developer
firecrawl search "machine learning" --categories research,pdf
# Time-based filtering
firecrawl search "tech news" --tbs qdr:h # Last hour
firecrawl search "tech news" --tbs qdr:d # Last day
firecrawl search "tech news" --tbs qdr:w # Last week
firecrawl search "tech news" --tbs qdr:m # Last month
firecrawl search "tech news" --tbs qdr:y # Last year
# Location-based search
firecrawl search "restaurants" --location "Berlin,Germany" --country DE
# Search and scrape results
firecrawl search "documentation" --scrape --scrape-formats markdown
# Save to file
firecrawl search "firecrawl" --pretty -o results.json
```
**Available Options:**
| Option | Description |
| - | - |
| `--limit ` | Maximum results (default: 5, max: 100) |
| `--sources ` | Sources to search: `web`, `images`, `news`, `alexandria` (comma-separated, default: `web,alexandria`). Use `web` to omit Alexandria tools |
| `--domain-tools` | Include Alexandria tools for the domains in web results (on by default with `alexandria`) |
| `--no-domain-tools` | Turn off domain matching for Alexandria tools |
| `--tool-detail ` | Alexandria tool detail: `compact` (default), `summary`, or `full` (includes contracts) |
| `--categories ` | Filter by category: `research`, `pdf`, `developer`, `gov` (comma-separated) |
| `--tbs ` | Time filter: `qdr:h` (hour), `qdr:d` (day), `qdr:w` (week), `qdr:m` (month), `qdr:y` (year) |
| `--location ` | Geo-targeting (e.g., "Berlin,Germany") |
| `--country ` | ISO country code (default: US) |
| `--timeout ` | Timeout in milliseconds (default: 60000) |
| `--ignore-invalid-urls` | Exclude URLs invalid for other Firecrawl endpoints |
| `--scrape` | Scrape search results |
| `--scrape-formats ` | Formats for scraped content (default: markdown) |
| `--only-main-content` | Include only main content when scraping (default: true) |
| `--json` | Output as JSON |
| `--output ` | Save output to file |
| `--pretty` | Pretty print JSON output |
***
### Alexandria
Find and run data tools from [Alexandria](/features/alexandria), the Firecrawl catalogue of third-party data providers. Discovery is free. A tool run costs the price listed on the tool.
```bash CLI theme={null}
# Find tools for a task (tools only, no web results)
firecrawl search alexandria "podcast conversations about AI agents"
# Browse categories, then providers and their tools
firecrawl alexandria list
firecrawl list particle
# Read the inputs and response of one tool
firecrawl find-tools --options '{"providers":["particle"],"capabilities":["podcasts/episodes/search"],"level":"tools","expand":["options","response"]}' --json
# Run the tool
firecrawl scrape particle/podcasts/episodes/search --options '{"semantic_search":"AI agents","limit":2}'
```
`firecrawl scrape provider/capability` is a short form of `firecrawl scrape --alexandria provider/capability`. Tool addresses go directly to Alexandria. They never fall back to a URL scrape.
#### Provider terms
When a provider returns `THIRD_PARTY_DATA_TERMS_REQUIRED`, read its terms first:
```bash CLI theme={null}
firecrawl alexandria terms show particle --pretty
```
An org admin accepts terms at the link in the error or at [Data sources settings](https://www.firecrawl.dev/app/settings?tab=data-sources). The CLI cannot accept terms. After acceptance, run the original command again.
Use `firecrawl alexandria feedback` to report issues or request capabilities, within 20 minutes of your last Alexandria search, discovery, or execution. Each submission refunds 1 credit, up to 10 credits per website and 100 credits per team each UTC day. Run `firecrawl alexandria feedback --help` for options.
***
### Developer
Search the [Developer Index](/features/developer) — issues, merged pull requests, and READMEs from public code repositories, alongside curated documentation sites.
```bash CLI theme={null}
firecrawl developer "how do I configure retries" --limit 10
```
**Available Options:**
| Option | Description |
| - | - |
| `--limit ` | Number of results to return (default: 10, max: 100) |
| `--skills-only` | Search only indexed agent-skill files (default: false) |
| `--json` | Output as compact JSON |
| `--output ` | Save output to file |
| `--pretty` | Pretty print JSON output |
***
### Government
Search the [Firecrawl Government Index](/features/gov) — statutes, regulations, codes, court opinions, and other government publications from US federal, state, and local government sources.
```bash CLI theme={null}
firecrawl gov "food labeling requirements for allergens" --limit 10
```
**Available Options:**
| Option | Description |
| - | - |
| `--limit ` | Number of results to return (default: 10, max: 100) |
| `--json` | Output as compact JSON |
| `--pretty` | Pretty print JSON output |
| `--output ` | Save output to file |
| `--jurisdiction ` | Keep one jurisdiction: `us` or `us-` plus a state or territory code, such as `us-ca` |
| `--court ` | Keep one court, by CourtListener court id, such as `scotus` |
| `--court-type ` | Keep one type of court, such as `federal-appellate` or `state-supreme` |
| `--cites ` | Keep pages that cite one law or case, such as `"42 U.S.C. § 1983"` |
| `--domain ` | Keep pages from one site, such as `irs.gov` |
Filters keep only pages the index has labeled, so a filtered search can leave out relevant pages, and no results does not mean none exist.
***
### Map
Discover all URLs on a website quickly.
```bash CLI theme={null}
# Discover all URLs on a website
firecrawl map https://example.com
# Output as JSON
firecrawl map https://example.com --json
# Limit number of URLs
firecrawl map https://example.com --limit 500
```
#### Map Options
```bash CLI theme={null}
# Filter URLs by search query
firecrawl map https://example.com --search "blog"
# Include subdomains
firecrawl map https://example.com --include-subdomains
# Control sitemap usage
firecrawl map https://example.com --sitemap include # Use sitemap
firecrawl map https://example.com --sitemap skip # Skip sitemap
firecrawl map https://example.com --sitemap only # Only use sitemap
# Ignore query parameters (dedupe URLs)
firecrawl map https://example.com --ignore-query-parameters
# Wait for map to complete with timeout
firecrawl map https://example.com --wait --timeout 60
# Save to file
firecrawl map https://example.com -o urls.txt
firecrawl map https://example.com --json --pretty -o urls.json
```
**Available Options:**
| Option | Description |
| - | - |
| `--url ` | URL to map (alternative to positional argument) |
| `--limit ` | Maximum URLs to discover |
| `--search ` | Filter URLs by search query |
| `--sitemap ` | Sitemap handling: `include`, `skip`, `only` |
| `--include-subdomains` | Include subdomains |
| `--ignore-query-parameters` | Treat URLs with different params as same |
| `--wait` | Wait for map to complete |
| `--timeout ` | Timeout in seconds |
| `--json` | Output as JSON |
| `--output ` | Save output to file |
| `--pretty` | Pretty print JSON output |
***
### Interact
Scrape a page, then interact with it using natural language or code. Interact uses the most recent scrape by default, or you can pass a specific scrape ID.
```bash CLI theme={null}
# 1. Scrape Amazon's homepage (scrape ID is saved automatically)
firecrawl scrape https://www.amazon.com
# 2. Interact — search for a product and get its price
firecrawl interact "Search for iPhone 16 Pro Max"
firecrawl interact "Click on the first result and tell me the price"
# 3. Stop the session
firecrawl interact stop
```
**Available Options:**
| Option | Description |
| - | - |
| `-p, --prompt ` | AI prompt (alternative to positional argument) |
| `-c, --code ` | Code to execute in the live page session |
| `-s, --scrape-id ` | Scrape job ID (default: last scrape) |
| `--python` | Execute code as Python/Playwright |
| `--node` | Execute code as Node.js/Playwright (default) |
| `--bash` | Execute code as Bash |
| `--timeout ` | Timeout in seconds (1-300, default: 30) |
| `--output ` | Save output to file |
| `--json` | Output as JSON format |
***
### Crawl
Crawl an entire website starting from a URL.
```bash CLI theme={null}
# Start a crawl (returns job ID immediately)
firecrawl crawl https://example.com
# Wait for crawl to complete
firecrawl crawl https://example.com --wait
# Wait with progress indicator
firecrawl crawl https://example.com --wait --progress
```
#### Check Crawl Status
```bash CLI theme={null}
# Check crawl status using job ID
firecrawl crawl
# Example with a real job ID
firecrawl crawl 550e8400-e29b-41d4-a716-446655440000
```
#### Crawl Options
```bash CLI theme={null}
# Limit crawl depth and pages
firecrawl crawl https://example.com --limit 100 --max-depth 3 --wait
# Include only specific paths
firecrawl crawl https://example.com --include-paths /blog,/docs --wait
# Exclude specific paths
firecrawl crawl https://example.com --exclude-paths /admin,/login --wait
# Include subdomains
firecrawl crawl https://example.com --allow-subdomains --wait
# Crawl entire domain
firecrawl crawl https://example.com --crawl-entire-domain --wait
# Rate limiting
firecrawl crawl https://example.com --delay 1000 --max-concurrency 2 --wait
# Pass scrape options to each crawled page
firecrawl crawl https://example.com --scrape-options '{"formats":["markdown"],"onlyMainContent":true}'
# Send crawl completion events to a webhook
firecrawl crawl https://example.com --webhook '{"url":"https://example.com/webhook","events":["completed"]}'
# Cancel an active crawl
firecrawl crawl --cancel
# Custom polling interval and timeout
firecrawl crawl https://example.com --wait --poll-interval 10 --timeout 300
# Save results to file
firecrawl crawl https://example.com --wait --pretty -o results.json
```
**Available Options:**
| Option | Description |
| - | - |
| `--url ` | URL to crawl (alternative to positional argument) |
| `--wait` | Wait for crawl to complete |
| `--progress` | Show progress indicator while waiting |
| `--poll-interval ` | Polling interval (default: 5) |
| `--timeout ` | Timeout when waiting |
| `--status` | Check status of existing crawl job |
| `--limit ` | Maximum pages to crawl |
| `--max-depth ` | Maximum crawl depth |
| `--include-paths ` | Paths to include (comma-separated) |
| `--exclude-paths ` | Paths to exclude (comma-separated) |
| `--sitemap ` | Sitemap handling: `include`, `skip`, `only` |
| `--allow-subdomains` | Include subdomains |
| `--allow-external-links` | Follow external links |
| `--crawl-entire-domain` | Crawl entire domain |
| `--ignore-query-parameters` | Treat URLs with different params as same |
| `--delay ` | Delay between requests |
| `--max-concurrency ` | Maximum concurrent requests |
| `--scrape-options ` | JSON scrape options passed to each page |
| `--scrape-options-file ` | Path to scrape options JSON file |
| `--webhook ` | Webhook URL or configuration |
| `--cancel` | Cancel an active crawl job by job ID |
| `--output ` | Save output to file |
| `--pretty` | Pretty print JSON output |
***
### Monitor
Create recurring scrapes or crawls that diff each run against the previous snapshot. Add a goal when you want Firecrawl to judge which changed pages are meaningful for your use case.
```bash CLI theme={null}
firecrawl monitor create --name "Hacker News AI" \
--schedule "every 30 minutes" \
--goal "Alert when a new Hacker News story related to AI enters the top 10. Ignore changes to stories that are not about AI. Do not alert on changes outside the top 10." \
--page https://news.ycombinator.com
firecrawl monitor run
firecrawl monitor checks --limit 10
firecrawl monitor check --page-status changed
firecrawl monitor update \
--goal "Alert when a new Hacker News story related to AI enters the top 10. Do not alert on changes outside the top 10."
firecrawl monitor delete
```
Monitor goals should stay short and faithful to the user's intent: say what should trigger an alert, restate any stated scope, and include exclusions only when they are obvious or explicitly requested. If the user asks for "any change", keep the goal broad.
**Available Options:**
| Option | Description |
| - | - |
| `--name ` | Monitor name |
| `--goal ` | Goal for meaningful-change judging |
| `--cron ` | Cron schedule, for example `*/30 * * * *` |
| `--schedule ` | Natural-language schedule, for example `hourly` |
| `--timezone ` | Schedule timezone, default `UTC` |
| `--page ` | Single page URL to scrape on each check |
| `--scrape-urls ` | Comma-separated page URLs to scrape on each check |
| `--crawl-url